

Building the world's AI data provenance network: @datafdn. prev @amazon, @dapperlabs
Global
Joined March 2017
- Tweets8.4K
- Following1.5K
- Followers10.4K
- Likes23K




Apparently, in the AI data market, "exclusive" is a bit of a flexible term.
We've spent years building a repository of data that we're now opening up for exclusivity checks through Echo.
Turns out having a few years' head start comes in handy.
teapaw.org/datafdn/status/2123825…

Amznthropic


In an increasingly chaotic, cut-throat and SHADY AI training data economy, Trace helps you:
1) know where your data comes from (provenance)
2) whether its actually exclusive
3) what happens to it along the way
any data you buy/sell should be on Trace.
A third-party provider recently tried to sell @psdnai its own training data.
The duplicate was identified immediately thanks to the digital receipts recorded on Trace.
This is why we're building Trace: without it, there is no way for AI labs to verify “exclusive” data as actually exclusive.
Very high signal contribution to the robotics training space from Poseidon’s bleeding edge research!
Open for anyone to use.
Happy training and evaluating 💪

Today, we're releasing EgoCrowd-500H, a new dataset accompanying our @corl_conf 2026 research on quality failures in crowdsourced egocentric video.
• 300 stereo clips
• 2.5 hours of footage
• 50 human-reviewed clips
Out now on @huggingface.
Andrea retweeted
We're honored to present research at @corl_conf.
Our team studied 500 hours of crowdsourced egocentric video to better understand where data collection goes wrong, and how to improve quality control for Physical AI.
One key finding: 90% of footage in flagged clips falls outside labeled failure intervals. Rejecting entire clips can mean discarding a lot of potentially useful data.
Tremendous work by @iamrashminagpal, @sebliu, @jdubpark, and Sandeep Chinchali.
First look at our research poster below. Catch us tomorrow at the 'Oops, I Erred' #CoRL2026 workshop ↴

Going live with @joshkriger on @TheEdgeofShow at 1:30pm ET.
Tune in:

AI runs on data, but who gets to own it?
Josh Kriger with Andrea Muttoni (@devrelius) of The Data Foundation on the next Edge Live. We're getting into a topic that deserves more attention.
📅 November 5 | 1:30 PM CST
Watch live on YouTube, X & LinkedIn.

last week in SF i went to a robotics for healthcare event.
stuff that is being worked on is pure sci fi:
head surgeon at Neuralink gave a talk around controlling the brain.. tldr, pretty much everything that happens in our body is controlled by the brain (either consciously or unconsciously), especially the deeper we go into the brain.
so if you can control your brain via an implant, imagine a future where you can decide your fertility, turn off your depression, increase your concentration, all via an app?
The talk was a theoretical thought exercise, but even so, some massive philosophical and ethical dilemmas are about to be uncovered soon.
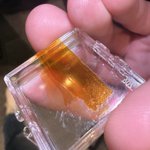
another pretty cool thing was seeing some robots that are being worked on that are essentially microscopic screws that inch their way into your brain via external magnets. a researcher showed me this box containing a microrobot...can you find the robot in this photo?
one big takeaway for me was how it seemed everyone there was complaining about training data; how little of it there is, and how bad most of it is today.
every single company there is looking for data that is:
- higher resolution (e.g. EEGs are very low res)
- higher in quantity (i.e. never enough data!)
- and more longitudinal (i.e. spanning more time).
if you're in the data business, my advice is look into healthcare robotics because they are absolutely starved for data. Ideally multi modal to increase signal (e.g. EEG + tactile + vision, etc), over longer periods of time.
very fascinating industry, likely one of the most impactful for our future. Will be keeping a close eye on it.

If I were Reddit I would laser focus on being a safe haven for *human* discussion, in an increasingly bot/slop infested world.
Focusing on things like human verification, ai detection, etc.
Otherwise it will inevitably die in a sea of KPI-friendly bots it’s already getting engulfed in.

Yesterday's earnings call with Reddit's CEO will be referenced for years to come.
Reddit, $RDDT, is now down -42% in 8 trading days.
AI has disrupted search, and the internet more broadly, forever.
Our thoughts on this are included below.

This is a MASSIVE problem in the data industry rn.
now that everyone is selling data, having receipts to PROVE the data you source is exclusive will set you apart in an sea of snake oil salesmen.
If you are a data company, be like kled.
use trace.datafdn.org


I went through every data vendor that launched in the last 3 weeks. Almost all of them are lying about their revenue, their lab partnerships, and their backgrounds.
(skip to 1:04 if you want to skip context)
Too many founders and VCs have been fooled by these people. Stop believing everything you hear. Data is much harder than most people think.
Enjoyed speaking with @HeleneBraunn about the thinking behind our recent decisions, what we've learned along the way, and where we're headed next with @SuiFoundation.
Thoughtful piece that captures the bigger picture.
coindesk.com/business/2026/1…

Data exclusivity is a massive problem in the ai training data space.
Vendors sell “exclusive” data to multiple buyers and they can’t verify it’s actually exclusive without some audit trail. That is what Trace is.
If you are buying an exclusive dataset you should be confident it’s actually exclusive. The best way to check is to see if that data already exists on Trace.
Force your data vendor to use Trace and protect yourself!
Help train AI, earn 50 bucks an hour and you have the peace of mind that all your contributions will be fully tracked on Trace!
This quoted post is unavailable.

Andrea retweeted

soon you'll see more and more AI use cases landing on @WalrusProtocol
THIS IS JUST A START
100%. This is why what we are doing with Trace is so important.
and you can all now see why we are teaming up with Sui and Walrus.

One of the defining questions of the AI era is going to be “How do you know?”
How do you know what is real when anything can be generated? How do you know what really happened versus what you were told happened? How do you know where a piece of data came from? How do you know it has not been changed? How do you know what an agent actually did on your behalf?
I think about this all the time
Verifiability is going to matter as much as intelligence
One of the main reasons Sui stood out is they already built a lot of the components needed for Trace to grow as the data layer end to end:
- storage (walrus),
- dynamic access control (seal),
- verifiable (but off chain) compute like inference in TEEs (nautilus).
Sourcing, access control, processing and inference can now be all on the same stack, and Trace’s audit layer can formally prove and verify every single step giving more depth and weight to the metadata it stores in turn becoming a source of truth for AI data.
This is the master plan for Trace.
Andrea retweeted

Trace registers over 3M data receipts EVERY DAY
Currently, we are able to surface tons of metadata related to a receipt's provenance:
- Did the contributor sign ToS/PP?
- Where did the data come from?
- When was it captured/uploaded? By what device?
This is the 1st major step in making the data that apps like @useKled collect SELLABLE to AI labs
But the next step is actually verifying ourselves that this information is true:
- Scanning the file itself to discover its metadata
- Verifying the data wasn't tampered with
- Keeping the original copy
By storing files on @WalrusProtocol, we can verify that every data receipt is what is says it is
And give frontier AI labs the complete confidence needed to purchase data in bulk
Trace turns any company into a data company


Walrus is becoming the default storage layer for @datafdn and Trace, the onchain registry for rights-cleared AI training data.
Trace records where AI training data came from and who owns it.
Walrus stores the original file, keeping it tamper-proof and accessible only to licensed buyers.
Trace has already registered more than 250M contributions and adds over 3M receipts a day, from apps that license data to frontier AI labs.
The next generation of AI will be trained on data from people, making provenance a procurement requirement. Walrus and @SuiNetwork make that provenance verifiable.
Read the announcement: sui.io/blog/data-network-joi…


This is a big step forward for DATA with a $30M investment from Sui. This makes Sui Foundation the largest holder of DATA, above DATA Foundation and PIP Labs.
Our founder SY Lee is also joining Sui as a strategic adviser on AI and training data.
Most importantly, bringing Trace and the 275M+ data receipts onto the Sui stack gives us the infrastructure to go beyond provenance alone, with reference data storage, access control, and stronger verification for the real-world data AI increasingly depends on.
Excited for what we will build together.
DATA is coming to @SuiNetwork.
The DATA Network and Trace are joining the Sui stack, bringing a live supply of rights-cleared AI training data to infrastructure built for AI workloads.
With 250M+ receipts already recorded by Trace, AI labs will be able to source real-world data with verifiable provenance, while @WalrusProtocol provides the underlying storage layer.
Sui Foundation is investing $30 million in the DATA Network, establishing the largest institutional stake in the network, alongside the continuing holdings of PIP Labs and the DATA Foundation. Furthering the alignment, SY Lee, founder of the DATA Network and CEO of PIP Labs, joins Sui Foundation as Strategic Advisor.
In the coming months:
▸ The DATA Network will be upgraded to run as a protocol natively on Sui
▸ Walrus becomes the default storage layer for DATA Foundation apps
▸ $DATA remains the token of the DATA protocol
The next chapter of DATA starts here.

Big day today 👀
CEO @devrelius has been busy at:
▸ @WeAreDevs
▸ @kbwofficial
▸ @token2049
Next stop: Sui Basecamp @SuiNetwork.

