The leading platform for crowdsourced benchmarks, competitions, and hackathons where the community shapes real-world progress in AI.

San Francisco
Joined October 2009
How tightly can you pack (n) squares into a square? 📦 Lining squares up in a grid often wastes space, and tilting just a few of them at the right angle can make the box smaller. In Squares in Squares, you'll pack 1 to 1,000 unit squares into the smallest square container you can. Only 59 of those puzzles have proven best answers, so the rest are open. 💰 Prize Pool: $50,000 ⏰ Entry Deadline: July 11, 2027 🏆 Prize Milestones: At 3, 6, and 9 months
5
7
1
33
5,817
This is a well-studied open problem in combinatorial geometry: the best-known solutions come from decades of work by mathematicians and programmers. Join the competition here: kaggle.com/competitions/squa…
1
1
4
1,998
Can frontier models actually predict how real people behave? 🕺 Today, in collaboration with @RunRehearsals, we are launching Human Behavior Bench, the first public benchmark that tests whether AI can understand human preference and everyday decision-making. AI models have gotten increasingly good at coding, but knowing for whom to build is the next frontier of challenges for AI models to capture. Human Behavior Bench evaluates models on predicting real human behavior across health, entertainment, recreation, values, and consumption. To build this baseline, we gathered ground truth data directly from real people and evaluated models across a wide range of everyday scenarios: • Ground truth baseline: 1,244 US adults surveyed (June-Sept 2026) • Some cohorts are traditional demographic indicators such as age, income, and location • Other filters are behavioral e.g. GLP-1 patients and recent car buyers • 750 cases total (149 public / 601 private) across finance, health, recreation, values, and consumption • Scored using 1-TVD (total variation distance) Base models still have a significant gap to close to accurately predict human behavior by cohort. LLMs’ predictions tend to converge towards the mean, while the true distribution of human preferences vary greatly. Against a human noise ceiling of ~93, the current leaderboard scores are: Rehearsals’ Engram 1.0 (AI Twins) tops the leaderboard at 94.1%, followed by Gemini 4 Argon at 80.6% Claude Opus 5 at 80.2%, GPT-5.6 Sol at 79.5%.
37
33
10
352
21,282
Off-the-shelf models perform well on the general population (scoring around 85), but fail when predicting deeper, specific cohorts (scoring closer to 55-60) where they drift back to the "average American." Where base models struggle most: • Hypothetical reactions (e.g., pricing increases or medical decisions) • Abstract value sentiments and attitudes • Testing novel concepts or products
1
9
1,673
Where the accuracy impacts understanding real people: • 55–64 year olds in the Northeast, after a $4/mo streaming price hike: 70% of people actually keep their plan. But every model predicts that only 36–47% would. • Older Midwest shoppers paying by phone/watch: 25% in reality. Every model says 6% or less. • Rural drivers who renew car insurance without shopping around: 24% in reality. Every model claims around 50%.
7
1,382
Ready to identify molecules from mass spectra in the Enveda CASMI 2026 competition? 🧪 Check out this starter notebook by haideptry. It walks you through candidate retrieval and reranking across four evidence channels, and is a great starting point to search spectral libraries, match structural analogs, simulate fragmentation, and rank candidates with a neural fingerprint model. kaggle.com/code/haideptry/en…
5
8
87
11,089
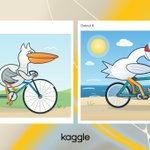
Which model outputs the best pelican riding a bike? 🪽🚲 Inspired by @simonw's pelican test, models generate an SVG and humans rate the results. GPT-6 Astra currently leads, with Gemini 4 Argon close behind. Vote now for the best one at kaggle.com/benchmarks/kaggle…
22
7
6
87
11,567
We’ve teamed up with Google DeepMind and Zapier to host the inaugural Bench Summit by Kaggle. Gain hands-on insights from the AI startups and researchers defining today’s evaluation standards, and get closer to the frontier. Secure your spot or apply to speak: rsvp.withgoogle.com/events/b…
6
22
2
136
10,858
Can you identify which LLM wrote a passage from the text alone? 👀 Each AI lab leaves behind distinct stylistic markers in vocabulary, phrasing, and punctuation. In Name That LLM, you'll identify which of 18 leading models from 6 organizations (Anthropic, Google, Moonshot AI, OpenAI, Qwen, and ZAI) wrote each unlabeled passage. 💰 Prize Pool: $50,000 ⏰ Entry Deadline: January 6, 2027
21
77
27
806
66,056
Your solutions will show how reliably today's frontier models can be fingerprinted from short text alone, helping researchers audit open benchmarks and understand what makes each model family distinct. Enter the competition here: kaggle.com/competitions/name…
2
3
1
54
7,849
What's the one Kaggle competition or hackathon you'll never forget?
13
8
1
56
13,062
Huge congratulations to Francis Halzen on the Nobel Prize, a landmark moment in astrophysics! 🏆 It was an honor for our Kaggle community to collaborate with the IceCube Neutrino Observatory in 2023, building open-source ML models to help predict the direction of neutrinos.
BREAKING NEWS The Royal Swedish Academy of Sciences has decided to award the 2026 #NobelPrize in Physics to Francis Halzen “for decisive contributions to the IceCube Neutrino Observatory and the discovery of high-energy neutrinos of astrophysical origin.”
9
42
6
280
14,975
The @NFL Big Data Bowl 2027 is live! 🏈 Build an analytical framework that uncovers non-obvious, actionable linkages between 10 Hz Combine sensor tracking data and future regular-season NFL game performance. • Prize Pool: $100,000 • Entry Deadline: January 6, 2027
3
13
1
83
11,580
Look beyond conventional scouting wisdom: your submission could help coaches and evaluators identify hidden talent, avoid costly draft busts, and design position-specific player development protocols. Join the Open or University Track here: kaggle.com/competitions/nfl-…
1
4
2,284
What's your best Kaggle hackathon tip? 👀
14
5
1
95
19,055
Export your AutoScientist open weights to Kaggle 💻 Can't wait to see what the community builds and shares!
Proud to support 33M+ Kaggle builders. 🎉 AutoScientist open weights now export directly to @kaggle.
1
13
101
14,747
Finish the sentence: "My Kaggle workflow isn't complete without..."
15
1
1
46
12,835
Post-train an open model into a coding agent that accelerates developer workflows on everyday hardware. The Gemma 4 Developer Agent Competition, hosted by @googlegemma and Kaggle, is live! 💰 Total Prize Pool: $100,000 ⏰ Entry Deadline: November 25, 2026
14
98
13
1,259
74,494