

Autonomous Security Swarms, backed by @ycombinator X25
Joined April 2025
- Tweets69
- Following66
- Followers696
- Likes172





MindFort is bring swarm testing to native MCP.
Teams can now run security swarms against their MCP, authenticated with oath, to find and fix critical security vulnerabilities in hours.
This launch is a part of a series of upcoming features to help secure AI native/AI infrastructure companies. AI native teams are already moving fast, and MindFort Swarms help teams move even faster.
MCP targets are now in GA, available to all through the Targets page.
Learn more: docs.mindfort.ai/guides/targ…
Today we're launching MindFort Validator, allowing teams to clear every false positive from their existing scanners, bug bounty programs, and agents.
1. Upload findings via MCP, API, or in platform
2. MindFort swarms exploit each finding, and triage accordingly.
3. Obsolete findings are discarded, and confirmed findings include a proof of exploitation
With the recent spike in agent-led attacks, we're hosting an urgent webinar on Wednesday Oct 28th, exploring how defenders are using agent swarms for red-teaming.
Led by previous team-members at OpenAI, Anthropic, Netspi, and ProjectDiscovery, you won't want to miss this one.
Register here: luma.com/pls7bty7

MindFort AI retweeted

excited to announce this partnership with @mindfort!
over a dozen series A+ companies have found sev0 and sev1's using our hosted deepseek v4.1 flash abliterated model!
however, dozens more have spent $10k+ without seeing ROI. it can be difficult to engineer the ideal harness and prompts for pentesting when it's not your #1 priority.
it's usually better to use providers like @mindfort that have spent hundreds of hours thinking about this
give 'em a shot: mindfort.ai/morph


We're excited to announce a new partnership with the team at @morphllm to bring the latest abliterated open models to MindFort Swarms.
In response to the rapid increase of agent-led cyberattacks, we needed a partner that was able to meet the inference requirements needed to run large scale agent swarms.
MindFort is designed to let teams safely deploy security swarms to quickly find vulnerabilities in their products and services.
Try today: mindfort.ai/morph

We're excited to announce a new partnership with the team at @morphllm to bring the latest abliterated open models to MindFort Swarms.
In response to the rapid increase of agent-led cyberattacks, we needed a partner that was able to meet the inference requirements needed to run large scale agent swarms.
MindFort is designed to let teams safely deploy security swarms to quickly find vulnerabilities in their products and services.
Try today: mindfort.ai/morph
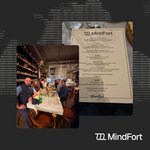
We hosted a dinner for Tech Week and brought together top security leaders from Twilio, Perplexity, Snap, DoorDash, Marvell, and Standard Insurance.
We discussed the evolving threat landscape, how defenders need to adapt, and why building and using security swarms is a must for every enterprise.

We evaluated DeepSeek-V4.1-Flash-1017 on NexBench, producing the highest score out of 18 total models.
NexBench provides signals of a model's ability to discover, reason about, and execute real exploits against a real target in a messy environment, while measuring price-to-performance ratio, token efficiency, and more.
See our thread for more findings (1/4)

1
7
369
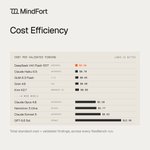
Compared to all models, DeepSeek V4.1 Flash-1017 also leads all models in cost efficiency, having the best cost efficiency ratio, per validated finding.
(3/4)

1
35
DeepSeek now leads on the pareto frontier, setting the standard for long-running cyber models that can attack a target continuously.
Full NexBench standings here: mindfort.ai/research/nexbenc…

31
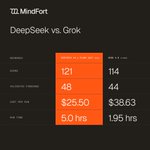
We tested DeepSeek V4.1 Flash 1017 on NexBench, and it placed 1st in overall performance and cost to performance ratio, beating our previous #1 (Grok 4.6), with 30% less dollar spend.
NexBench tests a model's ability to recon, exploit, and chain vulnerabilities in hyper-realistic environments, while measuring price-to-performance ratio, token efficiency, and more.
Our full write-up is coming soon, but one this is clear: open models are becoming the most powerful tools defenders have, besting many of the models available from frontier labs for offensive work.

We're hosting an exclusive security leader dinner next Wednesday, for LA Tech Week.
We're gathering some of the most influential security minds in SoCal who protect some of the world's largest companies for a moderated discussion on practical strategies to protect against agent swarm attacks, and how teams are using swarms today.
Space is tight, apply here for our last two spots: partiful.com/e/1IfzV8OoBBcU1…


Today, we're launching PR Security Reviewer, allowing teams to bring frontier security testing to every new code change.
Starting today, you can:
• Set up an automatic security review on every pull request
• See validated findings right on the PR, before it merges
• Patch issues in the same workflow your team already reviews code in
Try Security Reviewer today @ mindfort.ai

MindFort AI retweeted

Last week, we evaled Grok 4.6 and 4.7 in our agent harness to test the models' ability to reason about, write, and execute real exploits against a target in a messy environment.
Grok 4.6 scored incredibly well, becoming the best model we've ever tested at recon, pentesting, and reporting validated findings.
Even more impressively, it did so at a $0.88 cost per finding, making it our 2nd most cost-efficient model for cyber use.
See our updated findings here: mindfort.ai/research/nexbenc…

Our CEO, @bveiseh, presented at OWASP LA on the state of OffSec, and why defenders need to build their own security agents.
We discuss the future of security in the age of powerful offensive AI, legacy DAST, human pentesters, and more below:
youtube.com/watch?v=MdPSZAcy…
MindFort maps your cloud into one attack surface graph.
Connect a provider like Vercel using a team-scoped access token. The graph covers domains, DNS records, environment variables, firewall configs, users, and integrations, synced through Cartography. Switch from a grouped layout to radial or layered when you need to see the structure differently.
Live in beta today.

MindFort AI retweeted
Today, we're announcing NexBench, our internal benchmark for measuring which models can lead an offensive-security harness, balancing validated findings, token efficiency, and cost across real-world environments.
Current evals for cybersecurity have a fatal flaw: they are boxed in. Real world environments are messy, ambiguous, and contain layered vulnerabilities that can be chained together in different ways. They also have various deployment and authentication shapes, as well as various sizes which make it challenging for agents to actually navigate through.
That is why we created our own eval, modeled off the thousands of real world environments we have observed our agents navigate through.
Read more: mindfort.ai/research/introdu…

Today, the MindFort MCP is expanding to the full spectrum of our platform.
Agents can now access the full capabilities of MindFort with our MCP, from scoping a target and reviewing a finding to confirming a fix.
Now, you can run the entire workflow through the way agents already work: through tool calls, without needing to touch our UI.

Today, we're announcing NexBench, our internal benchmark for measuring which models can lead an offensive-security harness, balancing validated findings, token efficiency, and cost across real-world environments.
Current evals for cybersecurity have a fatal flaw: they are boxed in. Real world environments are messy, ambiguous, and contain layered vulnerabilities that can be chained together in different ways. They also have various deployment and authentication shapes, as well as various sizes which make it challenging for agents to actually navigate through.
That is why we created our own eval, modeled off the thousands of real world environments we have observed our agents navigate through.
Read more: mindfort.ai/research/introdu…