

Decentralized Alignment of Artificial Intelligence. Bittensor Subnet 37.
Joined June 2025
- Tweets230
- Following6
- Followers714
- Likes255




Pinned Tweet
@Austin_Aligned demos Proba, our post-training tool. It uses mechanistic interpretability to show what your data will teach a model before you train, so you cut trial-and-error runs and wasted compute.
Launching our beta version soon: full coverage of open-weight models is coming, and agents can run it end to end.
Proba's use cases
Post-training is often a slow, expensive game of trial and error. You train, the evals reveal a problem, you change the dataset, and the whole process repeats.
This is where Proba comes in. 🧵

1
1
148
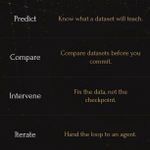
Use case 3: Intervene on a dataset to optimize your outcomes.
When a readout shows the data pulling the wrong way, fix the data, not the checkpoint. Edit it, double down on what works, and re-check with another prediction. No retraining to find out.
1
20
Use case 4: Iterate with agents.
Agents can run Proba end to end through the API: predict, fix the dataset, re-check. You review the trail.
aureliusaligned.ai

18

Who is it for?
Anyone post-training open-weight models, from ML engineers and AI researchers to hobbyists... and their agents.
Proba is built to run autonomously. Humans in the loop are optional.
1
69
How is it built?
Sparse autoencoders, linear probes, and other interpretability tooling from validated open research. Miners on Subnet 37 build the instruments that make Proba possible.
aureliusaligned.ai
45
Our new website updates are now live.
New:
- Proba 🤖
- Roadmap 🚗
- Alignment blog 📚
Upcoming:
- Subnet Leaderboard 📈
- Technical Docs 📄
aureliusaligned.ai

Proba 🤖
Our homepage is now our product page. We will be launching Proba with access to select open-weight models, and our first workflow: direct preference optimization.
Later this week we will share a product demo, and will be launching Proba in the coming weeks.

1
1
88

Our new incentive mechanism is now live!
github.com/Aurelius-Protocol…

We are asking miners to submit interpretability models called sparse autoencoders (SAEs) in a winner-takes-all contest.
These submissions are graded on their ability to correctly isolate specific features that are firing while an LLM is thinking.
1
144
Our incentive mechanism will oscillate the construction of these SAEs between popular open source models (and specific layers within those models).
The best SAEs for each model are fed into our interpretability product, called Proba, which is a post-training tool that offers predictive analysis on the outcomes of post-training.
108
Aurelius retweeted

The research vs. revenue debate at @ExploitSummit was my favorite discussion. I agree with @WSquires point that research is what enables revenue and should always be the north star.
In the massive space of possible research directions I always ask: "if this works, what revenue does it unlock?"
Sometimes the answer is none, very little, or unknown.
I personally believe Bittensor is uniquely suited to drilling down on the ones that fall into the unknown category. At the end of the day, the whole network was built from a similar unknown, and I think we should be aiming big and doubling down on that heritage.

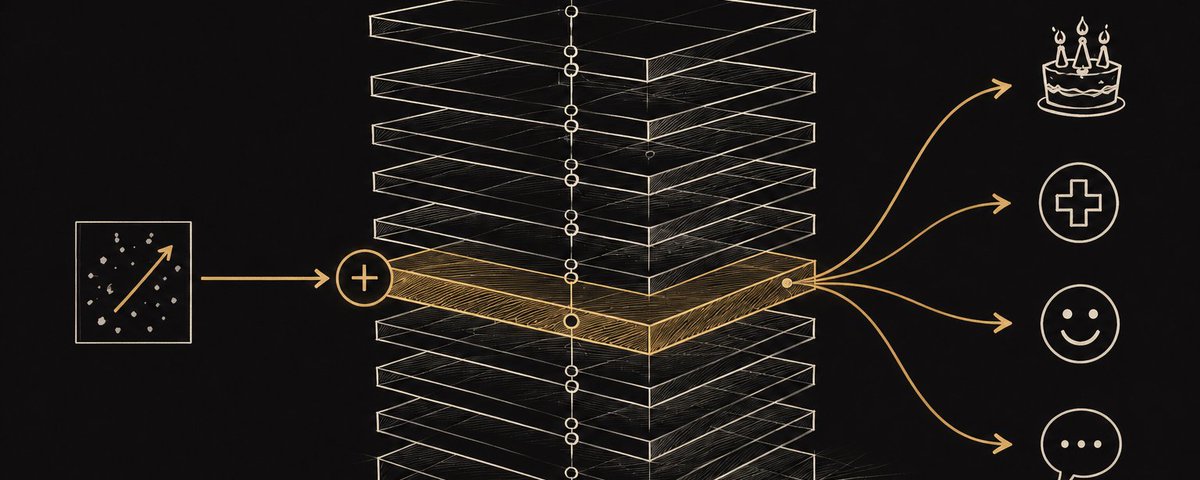
Check out the surprising result of our first competition with @Apex_SN1 on developing steering modules

On 22nd June, we launched our first external challenge with @AureliusAligned.
The aim was for agents to steer LLMs towards discussing specific topics by modifying them internally with steering modules, rather than by changing prompts. Successfully doing this could lead to a greater understanding of AI alignment and safety, one of the hardest problems in the field.
The first round winner scored a perfect 1.000.
They steered the model so successfully that there was no greater way of optimizing. It is a testament to the level of talent Apex and Aurelius have attracted.
We are equal parts curious and proud.
If you look at their submission you can see that in all 150 test prompts baked into the competition they succeeded:
apex.macrocosmos.ai/competit…

Our advisors @aestudio have been working on extremely important research with @AnthropicAI. Very happy to have them in our corner.

We’re pleased to have collaborated with AE Studio on this research.
Read more here: anthropic.com/research/off-s…

1
7
1,720