






Arys Wisnu retweeted

jujur gw respect dia bet as finance + personal growth influencer, tp soal ini dia blunder maksimum sih, ini mah timpa brutal dan overclaiming 🫠 keknya dia ke-skip matkul socio informatika pas di binus


Why isnt it called “Samantha”?

We believe voice is the most natural way to interact with intelligence, so we created Dessa, the most authentic full-duplex speech model ever built. Talking with it feels like talking with a person…full of emotion, nuance, pauses, and a natural cadence.
block.xyz/dessa

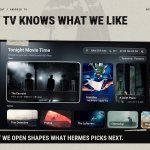
I've seen everyone vibe coding their TV to remove the bloat, which i did too. but i also connected mine to Hermes for movie picks and our family schedule.
lunch with the family gets light Indonesian movies and crime-case YouTube videos. movie night with my wife gets horror and sci-fi rated 7+ on Netflix or HBO Max.
the picks also follow our taste. Hermes sees what we open on the TV, skips what we’ve already watched, and drops anything we mark "not for us".
finally i can ask Hermes: "recommend me a folk horror movie that prominently features nature, forests and trees, to watch on the TV tonight"


warga Bali yang mau isi bensin, cek dulu di sini ya. ada perkiraan lama antre tiap SPBU (dihitung dari lalu lintas Google Maps), SPBU paling sepi di dekatmu, plus CCTV langsung
Cek Antrian SPBU se-Bali: antrespbu.id


Been doing this since shitty Opus 5 came out back then except for the video

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.


Finally

Welcome back to Hermes Agent, Claude
New official plugin that uses Claude SDK without the tradeoffs to enable Claude Code subscriptions to work in Hermes Agent again!
Check it out and install it here: hermes-agent.nousresearch.co…

Arys Wisnu retweeted
Okay, everyone wants us to give the unbiased facts.
Jev compaction here has a lot of problems. The biggest problems:
- When I ran it on our public compaction eval (that you can run too), it resulted in a programmatic rule, that you dont need any Jev or other model for - it simply removed all tool calls from the chat history
- This means you could do it for free, first of all, but second of all, it means you run into a viscious cycle.
Every compaction, there are less and less tool calls to remove from the chat history, meaning it compacts less and less tokens, until there is no room for compaction, and you hit a hard stop, and can't compact anymore.
- And, if you are cycling like this, every compaction breaks your cache, so you're paying 10x the price on input tokens, and keeping more input tokens each round means a higher baseline cost after compaction as well.
Here's the full reproducible eval that you can run against Hermes Agent between the two (Hermes' vs Jev's):
github.com/NousResearch/herm…


found the perfect use case for @typesafeai Jev:
instant compaction
in 2026, why is compaction still a summarization prompt?
Jev can make it instant by scoring every tool call and dropping what’s irrelevant

Great writeup. Two caveats: 'attributed to agents' ≠ authored, and the 52% cost/session drop partly rides the frontier getting cheaper. The fixed-model 34% is the honest number. Cheap agents that ship broken code are expensive downstream.
Stealing the MCP-via-shell trick.


haven’t written a long post in awhile.
this one is about how i work now, with what i call lazy maxxing.
aryswisnu.com/blog/lazy-maxx…
