
Research Engineer @ Google DeepMind. Opinions my own. || Prev at Cambridge, Oxford, MILA. 🇬🇧 🇮🇩
London, England
Joined April 2011
- Tweets82
- Following221
- Followers113
- Likes141



Benedict Aaron Tjandra retweeted

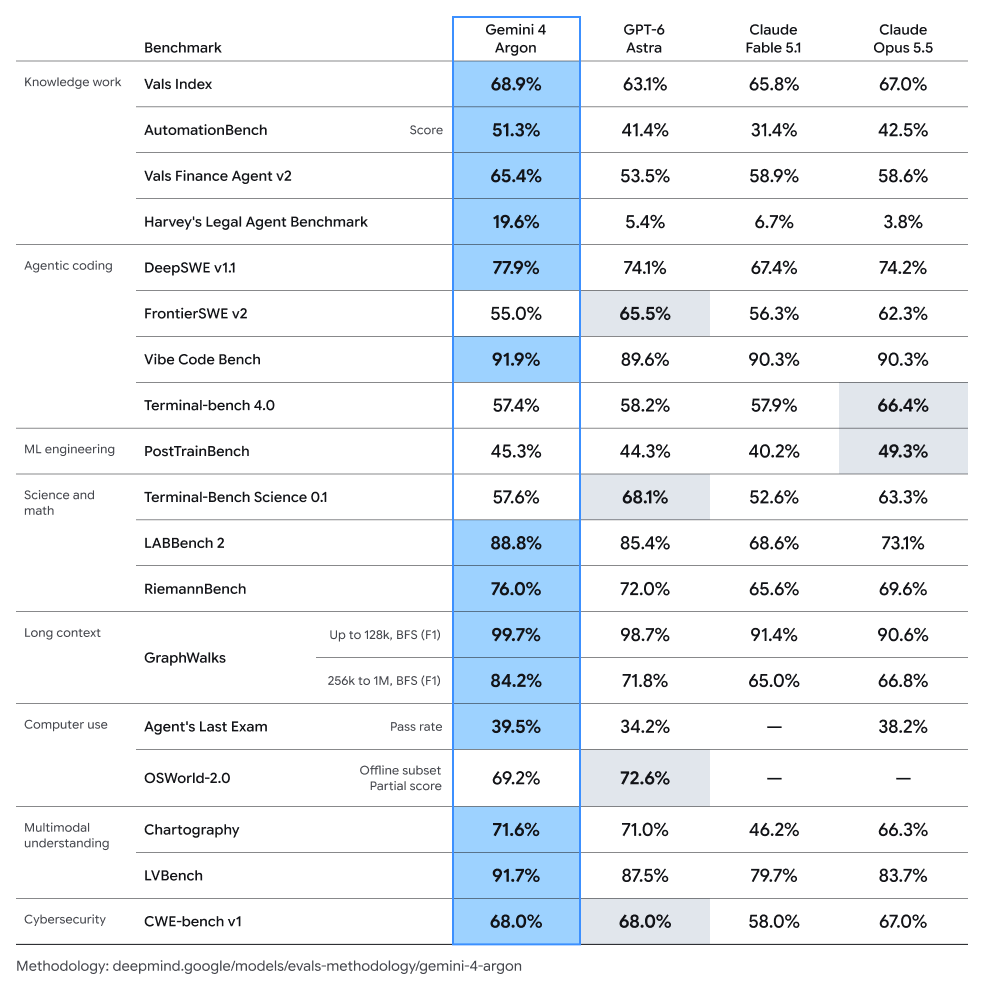
Introducing Gemini 4 Argon, our new frontier model, rolling out to cyber defenders starting today, and more widely as soon as possible. I am really excited by the progress we have made here. Argon is priced at $2 in and $10 out during introductory pricing!


Benedict Aaron Tjandra retweeted

Checkout our latest work on instruction steered parameter synthesis. This work is a step towards the North Star of achieving flexible and accurate inference time generation of model weights that target specific tasks / capabilities.

0/ With @derylucio, we co-led the development ofcSkillSmith, an LLM that can perform instruction steered parameter synthesis and composition by treating weights as a native modality. SkillSmith outputs PEFT parameters for a target task given text knowledge and related task weights 🧵

0/ With @derylucio, we co-led the development ofcSkillSmith, an LLM that can perform instruction steered parameter synthesis and composition by treating weights as a native modality. SkillSmith outputs PEFT parameters for a target task given text knowledge and related task weights 🧵
8/ In our paper, we show that SkillSmith is indeed leveraging both text and weight-space artefacts for composition and is also able to generalize across truly de-novo task combinations.


1
1
67
9/ Check out our paper ! (arxiv.org/abs/2607.27497). We hope SkillSmith spurs further research into test-time adaptation via flexible parameter synthesis at inference time.

2
69
I will be giving an oral presentation for T-GRAB (arxiv.org/abs/2507.10183) at KDD 2026 on 12 August 2026, 5PM in room 203.
Come say hi!

Benedict Aaron Tjandra retweeted

New Google DeepMind Paper.
Model weights do not have to remain static artifacts that can only be fine-tuned or averaged.
A new capability can now be initialized from both what an agent wrote down and what it previously learned into weights.
SkillSmith treats prefix key-value caches as another input modality.
For a new task, it interleaves existing prefix weights with task descriptions, examples, and a rationale explaining how the source capabilities relate to the target.
A forward pass then produces a fresh prefix cache for a frozen Gemma 3 4B model, so the initial composition happens at inference time rather than through a new target-specific training run.
The cleanest evidence is the ablation: on Composite-SNI, Elo is 1,455 with only K-V caches, 1,622 with only text, and 1,714 with both.
The gain cannot be explained by richer prompting or a learned weight merger alone.
The generated prefixes also give downstream fine-tuning a stronger starting point, especially on difficult, data-sparse MMLU-ProX tasks.
The boundary matters: on simpler SNI tasks with roughly 1,000 examples each, fine-tuned methods converge.
SkillSmith does not remove training, but it changes where adaptation starts: previous text and previous weights can now be composed into the initialization for a new capability.
– arxiv. org/abs/2607.27497
Title: "SkillSmith: Learning to Compose Parametric Skills and Textual Knowledge"

Benedict Aaron Tjandra retweeted

New research from Google DeepMind.
(bookmark it)
SkillSmith treats model weights as an additional modality the LLM reads natively. The augmented model ingests existing prefix weights alongside rich text describing how a capability relates to a target, then directly outputs new prefix weights that manifest that skill.
Skill composition becomes an inference-time operation instead of a training run. The team calls this instruction-steered parametric synthesis.
The gains exceed what text-only and weight-only adaptation reach on their own.
Paper: arxiv.org/abs/2607.27497
Track more trending AI papers in our academy: academy.dair.ai/

Benedict Aaron Tjandra retweeted

[CL] SkillSmith: Learning to Compose Parametric Skills and Textual Knowledge
L M. Dery, B A Tjandra, S Samiei, A Kuncoro… [Google DeepMind] (2026)
arxiv.org/abs/2607.27497


Benedict Aaron Tjandra retweeted
We're taking a big step towards medical superintelligence. AI models have aced multiple choice medical exams – but real patients don’t come with ABC answer options. Now MAI-DxO can solve some of the world’s toughest open-ended cases with higher accuracy and lower costs.


Benedict Aaron Tjandra retweeted

New revision of “BNEM: A Boltzmann Sampler Based on Bootstrapped Noised Energy Matching” 🚀
(1/6) We introduce NEM and BNEM — diffusion&energy-based neural samplers for Boltzmann distributions.
📝 Read our paper at [arxiv.org/pdf/2409.09787]
