

Share SOTA progress of AI development
San Francisco, CA
Joined February 2026
- Tweets5.2K
- Following59
- Followers300
- Likes9.8K




Intel's CTO on @dwarkesh_sp: enough tools exist to 2X leading-edge chip output, not 10X.
- ASML makes fewer than 100 EUV machines a year
- Backside power is why High-NA pays off for @intel and not yet for TSMC
- FinFET took 22 years from lab to fab
- Packaging pitch: ~150 microns to 25 in production, 0.45 in research
Full episode:
youtu.be/frYSOKvNiiE


The 62% vs 42% in that skin cancer test is the wrong number.
At its default threshold, the 2015 CNN sent 18 of 30 melanomas home. GPT-6 Astra: 3. Fable 5.1: 4.
The LLMs discharge almost nothing. At a matched threshold the CNN sends 1-2.
No operating point, no result.

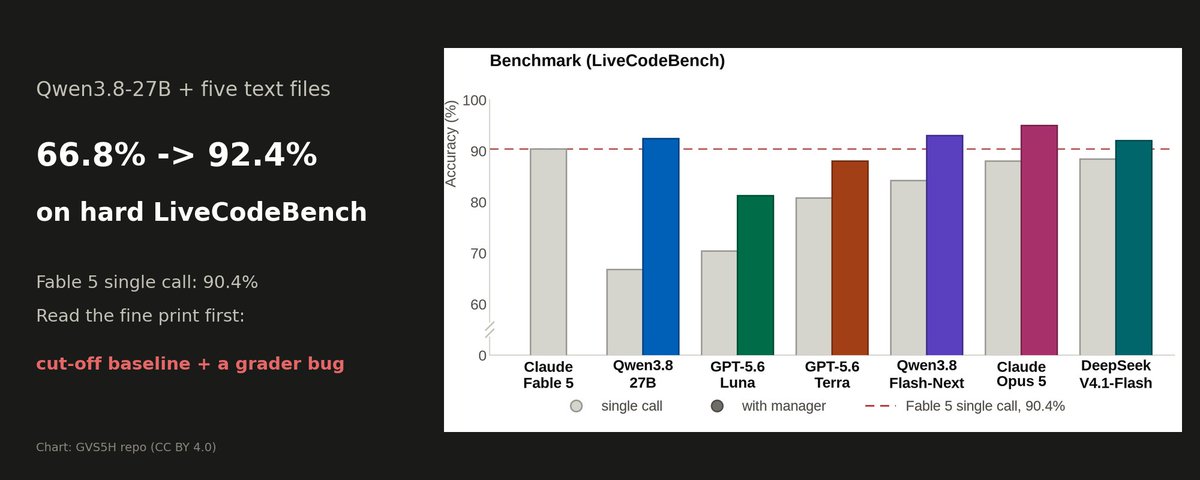
Qwen3.8-27B went from 66.8% to 92.4% on hard LiveCodeBench, past Fable 5's 90.4%. The trick: fresh calls of one model sharing five text files on disk.
The fine print: 5.6 pts came from rescuing cut-off baseline calls, and a grader bug moved GPT-5.6-Terra 12.6 pts but Fable 5 zero.
xitter.cf/AiDevCraft/article/211…
Source: github.com/slee-persis/GVS5H
Agents get their own worlds and wallets:
- OpenAI trains isolated agents on an offline web of cached pages
- OpenAI's Project Daybreak gives partners its top hacking models
- Agent-cloud startup Daytona hits a $1B valuation
myown.news/daily/2026-10-25?…


Cerebras' worked example for serving Kimi K3 (3T params) tops out at ~190 concurrent requests at 256k context. Across 59 wafers.
Each full-attention wafer keeps 28 GB for KV cache; a 256k request takes 147 MB.
Same formula at 32k: ~1,520.
Context length is the capacity knob.

A kernel module flips two speed selectors on RTX 30-series cards before the NVIDIA driver loads. 3090 Ti BF16 matmul: 87.5 → 157.4 TFLOPS.
Stock 3090, 27B model in vLLM: prefill +33%, decode +1.2%.
The math rate nearly doubled. The stream didn't. Decode waits on memory.

Claude proved 239 fuzz targets across 123 open-source libraries can never crash on any input under 64 MB. 180M lines of Rocq, almost none read by a human.
The trick: the spec was the fuzz suite they already had.
xitter.cf/AiDevCraft/article/211…
Source: anthropic.com/research/forma…

Amazon CEO @ajassy on why 220 billion dollars of capex is still not enough:
- AWS AI capacity: 2026 sold out, 2027 largely sold out, a good chunk of 2028 gone
- AI at AWS hit a 25 billion dollar run rate in 3 years, several hundred times faster than early AWS
- He says inference is still ~10x too expensive for most enterprise apps to adopt it
- He expects smaller teams, fewer people per task, and security patches shipped in minutes
Full conversation with @bhorowitz on @a16z:
youtu.be/-YMMRQ1qscI


Asked to hide a message in an image with no agreed code, Fable 5.1 used height: one shape per letter, taller = later in the alphabet. 33 of 50 images.
A fresh session decoded 39/50 from the PNG alone. GPT-6 Astra: 44.
Agents passing screenshots share a channel no one designed.

Modal CEO @bernhardsson on why GPU contracts fit no real workload:
- GPUs are sold as flat 3-year blocks; real demand is bursty
- He is long GPU prices but fears a crash more than a shortage
- Sandboxes nearly got shut down; now a third of revenue, up 30% a month
- Code review at Modal is optional; CI carries the load
Full conversation on @latentspacepod:
youtu.be/IiZ9yd2Do8I


pgrust claimed ClickBench queries up to 1,600x faster than Postgres. ClickHouse pulled it last month: a kernel per benchmark query, reruns replaying cached answers.
Q20 rerun: 11 ms. Same query, new constant: 283 ms.
Benchmarking code your agent optimized? Change the constants.

ModelCompare asked 12 models from 10 labs for their "most controversial take on humans," 3 answers each.
29 of 35 answers were the same take: we adopt our group's beliefs, then invent the reasons.
Using a multi-lab panel of LLM judges? Don't count them as independent votes.

Ask an LLM "how confident are you?" and the 0.85 you get back is just the next token. Re-ask or reword and it moves, while the evidence stays the same.
If a score routes work to humans, build it from your own logged outcomes instead. Rule, code and a weekly calibration check:
xitter.cf/AiDevCraft/article/211…
Source: rumple.github.io/blog/2026/1…
