
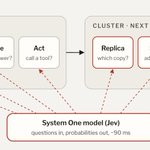

What if a fast “System One” model like Jev could make decisions for an LLM serving system?
- Which model to route to.
- Whether to use a cached response.
- Who runs next.
- How to manage the KV cache.
We built JevServe-Bench to find out. 🧵

4/ And these predictions can directly improve the serving engine.
Using Jev's output-length predictions to prioritize shorter requests:
SLO attainment: 75% → 99%
P90 TTFT: 8.3s → 0.17s
Think you can beat a model that takes 92ms? Try 5 questions yourself:
Playground: supercomputing-system-ai-lab…
Blog: supercomputing-system-ai-lab…
Joint work with Banghao Chi, Jiahuan Yu, @_Minjia_Zhang_ at SSAIL Lab, UIUC.
More to come.
Xinyu Lian retweeted
Today, we welcome the 2026 Microsoft Research Fellowship cohort, an inspiring global community of fellows and advisors helping to shape what’s next across science, technology, and society. Join us in celebrating this year’s recipients: msft.it/6013Q45bX
These contributions span the following themes:
• AI for global and societal impact
• AI fundamentals: scalable reasoning, model adaption and evaluation
• Biological and scientific modeling
• Foundational systems & infrastructure for AI
• Human-AI collaboration and interaction
• Multimodal & embodied intelligence
Xinyu Lian retweeted

Excited to share that our work SuperOffload received an Honorable Mention for the ASPLOS 2026 Best Paper Award 🎉
Proud of the team for pushing forward system design for large-scale AI. Xinyu gave a great talk presenting the work. In addition, it was also wonderful to spend time with collaborators and the broader community.

Xinyu Lian retweeted
SuperOffload boosts large-scale #LLM training efficiency on tightly coupled GPU/CPU Superchips—up to 4× faster on GH200 vs prior approaches. Built on DeepSpeed ZeRO Stage 3 by @Alexlian0806 @toh_tana @_Minjia_Zhang_ & Tunji Ruwase
Read #PyTorchFoundation's latest blog: hubs.la/Q03MYQl70
#PyTorch #OpenSourceAI

Xinyu Lian retweeted
🚀 SuperOffload: Unleashing the Power of Large-Scale LLM Training on Superchips
Superchips like the NVIDIA GH200 offer tightly coupled GPU-CPU architectures for AI workloads. But most existing offloading techniques were designed for traditional PCIe-based systems. Are we truly tapping into their full potential for LLM training?
🎯 SuperOffload is our answer to this challenge, a new DeepSpeed component rethinking offloading from the ground up, specially designed for LLM training on Superchips.
✨ SuperOffload is exact -- no approximation, no heuristics, and no changes to your training algorithm. Just faster, larger model with longer sequence training using the same code, which are made possible by system-level optimizations exploiting Superchip architecture.
🧪 SuperOffload allows you:
- Finetune models like GPT-OSS-20B, Qwen3-14B, and Phi-4 on a single GH200
- Up to 4X faster speed than previous approaches like ZeRO-Offload
- Effortlessly scales to:
-- Qwen3-30B-A3B and Seed-OSS-36B on 2 x GH200s
-- LLaMA2-70B on 4 x GH200s
-- 1M sequence length on 8x GH200 with 55% MFU
- Easy-to-use: Fully integrated and open-sourced in DeepSpeed. Just a few lines of code to enable!
📚 Read more through official PyTorch blog: pytorch.org/blog/superoffloa…
🧠 For more technical details, please read our technical report: arxiv.org/abs/2509.21271
🛠️ SuperOffload is fully open-sourced through DeepSpeed. Try it now: github.com/deepspeedai/DeepS…
📄 SuperOffload has been accepted to ASPLOS 2026! Kudos to Xinyu Lian (@Alexlian0806), Masahiro Tanaka (@toh_tana), and Olatunji Ruwase.
🎤 Featured at PyTorch Conference 2025
SuperOffload will be featured in the DeepSpeed & vLLM keynote at this year's PyTorch Conference in San Francisco.
🔥Come see how we're rethinking large-scale LLM training for the Superchip era: events.linuxfoundation.org/p…

Xinyu Lian retweeted

The Universal Checkpointing paper is out! arxiv.org/abs/2406.18820
If you remember the @BigscienceW BLOOM-176B training, Tunji Ruwase and I co-invented this technology for Megatron-Deepspeed in order to enable to quickly scale up and down node topology while continuing training.
Since then @MSFTDeepSpeed continued improving on that and it has now been fully integrated into Deepspeed.
The blog post is here: github.com/microsoft/DeepSpe…

Xinyu Lian retweeted

#ILLINOIS CS professor Darko Marinov & former students Qingzhou Luo, Farah Hariri & Lamyaa Eloussi were awarded 2024 Test of Time Honorable Mention by the ACM ICF of Software Engineering for their 2014 paper "An empirical analysis of flaky tests." 🔸🔹
siebelschool.illinois.edu/ne…

ALT Darko Marinov
Thanks to my wonderful advisor @tianyin_xu for the enlightening broadcast! Explore our work on configuration testing and my research presented at @ICSEconf 2023 on uRTS, a test selection method for both source code and configuration change. mir.cs.illinois.edu/marinov/… 📖

In the last two years, Xinyu has been working with Darko Marinov and other @plfmse faculty to integrate the research on Configuration Testing (Ctest) into @IllinoisCS grad-level courses, including CS 527 (Software Engineering) and CS 591SE. Ctest is now a course project in 523.
One midnight, as the TA for CS527 at #UIUC, I was reading students' experience on the challenges they faced in software development. One story left me impressed. (1/2)
