

New Data Structures and Algorithms papers from https://xitter.cf/t.co/xCXkX8eAeB. Thank you to arXiv for use of its open access interoperability.
- Tweets6.8K
- Following2
- Followers1.3K
- Likes3




ALT A path or cycle in a 2-edge-coloured graph is alternating if consecutive edges have different colours. These objects are natural analogues of paths and cycles in graphs, and even more so in digraphs. A well-studied class is that of acyclic 2-edge-coloured graphs, that is, those forbidding alternating cycles. In particular, (acyclic) 2-edge-coloured graphs generalize directed (acyclic) graphs (DAGs), but the complexity of problems on DAGs is much better understood than that of the corresponding problems on acyclic 2-edge-coloured graphs. We investigate the complexity of two such problems, whose directed counterparts are well-known. Our first result is an nᴼ⁽ᵏ⁾-time algorithm for the alternating k-linkage problem on acyclic 2-edge-coloured graphs. This problem asks for k vertex-disjoint alternating paths joining k prescribed pairs of vertices. This generalizes the directed k-linkage algorithm for DAGs. For every fixed k, this also yields a polynomial-time algorithm for finding k internal

ALT We study the fundamental problem of PAC learning positive linear combinations of k arbitrary ReLU activations on ℝᵈ with respect to the Gaussian distribution, in L₂ loss. We give the first fully-polynomial time algorithm for this learning task. Specifically, our algorithm draws poly(d, k, 1/∊) samples, runs in poly(d, k, 1/∊) time, and outputs a hypothesis that is ∊-close to the target concept with high probability. All prior algorithms for this problem require super-polynomial time in k or 1/∊, or leverage strong well-conditioned assumptions on the weight matrix. On a technical level, our approach develops a novel boosting procedure of a “weak” learner that recovers the hidden weight vectors to constant error, in a list-decodable manner. To develop this “weak” learning procedure, we leverage implicit tensor computation techniques to construct a low-degree filtering procedure based on Hermite tensors of the target function. This procedure amplifies separation among (clusters of) weight

ALT Boolean matrix multiplication is a fundamental operation in many graph-based applications, including web and social network analysis, information retrieval, and graph query evaluation. However, conventional sparse representations such as CSR}/CSC still incur significant space and time costs on large graphs. In this work, we introduce a method for multiplying Boolean matrices based on a biclique-based compressed representation that decomposes them into dense bipartite subgraphs, thereby capturing large sets of implicit edges. We first improve the iterative biclique extraction algorithm of Hern\'andez and Navarro by introducing percentile-based parameter adaptation that dynamically adjusts its parameters according to the degree distribution, enhancing both extraction efficiency and compression ratio. We then extend the Schoor multiplication algorithm to operate directly on biclique-encoded matrices, thereby enabling a compositional form of multiplication where the output can also be repr

ALT We study the structure and exact certification of nonnegative tensor decompositions supplied through rational factor matrices. Every failure of minimality or essential uniqueness contains an irreducible positive exchange between p supplied terms and q competing terms. A dimension count based on the Lovitz–Petrov splitting theorem bounds the effective order of such an exchange, the sum over the modes of the joint factor-span dimension minus one, by p+q-2, and this bound is attained at every supplied length R≥2. After eliminating ambient-row variables by the Farkas lemma, the resulting semialgebraic systems have fewer than 2R² real variables. For input bit length L, this gives a deterministic G(R)Lᴼ⁽ᴿ²)-time algorithm that computes the nonnegative rank and an exact minimum-length decomposition, decides minimality and essential uniqueness, and returns exact witnesses when either property fails. The exponent is independent of the tensor order and the mode dimensions. For Lebesgue moment te

ALT The selection problem asks to find the k-th smallest element in a given set X. Its complexity is well-known to be Θ(|X|) for every fixed k. We consider the poset selection problem where a partial order P on X is given, and the underlying order of X is guaranteed to be a linear extension of P. This generalizes several variants of the selection problem studied before. Our main result is an algorithm that performs O( k + OPT(P,k) ) comparisons, where OPT(P,k) is the minimum number of comparisons required for the input (P,k). If P is a rooted tree, we obtain an O( OPT log (k / OPT) ) algorithm, which can be further improved to O( OPT log log (k/OPT) ) or O( OPT log OPT) under mild assumptions about P. Our algorithms are based on the work of Kaplan, Kozma, Zamir, and Zwick [SOSA 2019], who used Chazelle's soft heaps [J. ACM 2000] to simplify several older results. We introduce a new soft heap variant, the weighted soft heap, which allows greater control over which elements get corrupted.

ALT We consider the problem of maintaining the triconnectivity in some biconnected graph G in the incremental dynamic setting. We consider updates in the form of edge insertions and edge subdivisions, and triconnectivity queries, i.e. queries of the form "are there at least three vertex disjoint paths between a and b?". All algorithms presented in this paper are deterministic. All queries and updates are answered in worst-case O(log n) time. By combining this result for biconnected graphs with a result of Holm and Rotenberg [SODA'20] we get an algorithm for general graphs with a worst-case running time of O(log² n) per operation. These algorithms represent an improvement of the state-of-the-art by a factor of O(log n).
![We establish an Ω(d) lower bound on the competitive ratio of convex body chasing in ℝᵈ with ℓₚ movement costs for any p ∈ [1, ∞). Previously, the best known lower bound for general p was Ω(max{√d, d¹⁻¹/ᵖ}), established by Bubeck et al. (2019); a linear lower bound was known only for p = ∞, realized by the standard construction of chasing faces of a hypercube. Our lower bound strictly improves on the prior bound for every fixed p ∈ [1, ∞) and shows that the functional Steiner point algorithm of Sellke (2023) - which has competitive ratio O(d) - is asymptotically optimal for every ℓₚ norm. Our lower bound is based on the recursive construction of Bubeck, Coester, and Rabani (2023) for metrical service systems, which gives a lower bound of Ω(r²) for requests of size O(r) in that setting. We show that requests in their construction, each comprising a set of discrete points in a graph metric, can be mapped to the vertices of convex requests in a (2r+1)-dimensional vector space while approxi](https://pbs.twimg.com/media/HVj-ronWMAAqWoO.png?name=orig)
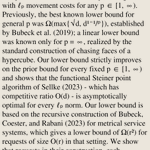
ALT We establish an Ω(d) lower bound on the competitive ratio of convex body chasing in ℝᵈ with ℓₚ movement costs for any p ∈ [1, ∞). Previously, the best known lower bound for general p was Ω(max{√d, d¹⁻¹/ᵖ}), established by Bubeck et al. (2019); a linear lower bound was known only for p = ∞, realized by the standard construction of chasing faces of a hypercube. Our lower bound strictly improves on the prior bound for every fixed p ∈ [1, ∞) and shows that the functional Steiner point algorithm of Sellke (2023) - which has competitive ratio O(d) - is asymptotically optimal for every ℓₚ norm. Our lower bound is based on the recursive construction of Bubeck, Coester, and Rabani (2023) for metrical service systems, which gives a lower bound of Ω(r²) for requests of size O(r) in that setting. We show that requests in their construction, each comprising a set of discrete points in a graph metric, can be mapped to the vertices of convex requests in a (2r+1)-dimensional vector space while approxi

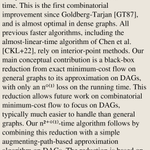
ALT We give a combinatorial algorithm that computes an exact minimum-cost flow in n²⁺ᵒ⁽¹⁾ time. This is the first combinatorial improvement since Goldberg-Tarjan [GT87], and is almost optimal in dense graphs. All previous faster algorithms, including the almost-linear-time algorithm of Chen et al. [CKL+22], rely on interior-point methods. Our main conceptual contribution is a black-box reduction from exact minimum-cost flow on general graphs to its approximation on DAGs, with only an nᵒ⁽¹⁾ loss on the running time. This reduction allows future work on combinatorial minimum-cost flow to focus on DAGs, typically much easier to handle than general graphs. Our n²⁺ᵒ⁽¹⁾-time algorithm follows by combining this reduction with a simple augmenting-path-based approximation algorithm on DAGs. The reduction is based on a new structural result, called a flow-cost-preserving DAG projection. Given an arbitrary directed graph, this construction produces a DAG that approximately preserves both the congesti

ALT The Polytope Scheduling Problem (PSP) is a general framework for preemptive scheduling in which feasible instantaneous job allocations form a packing polytope. In the nonclairvoyant online setting, Proportional Fairness (PF), a practical allocation rule rooted in market theory, is the leading general-purpose algorithm. On a single machine, PF coincides with weighted Round-Robin, which is 2-competitive for weighted completion time with uniform release dates (optimal for nonclairvoyant algorithms) and (2+ε)-speed O(1/ε)-competitive for weighted flow time. Known guarantees beyond a single machine are weaker. This raises a central question: Are these heterogeneous environments intrinsically harder than a single machine under nonclairvoyance? We show that they are not: PF retains both single-machine guarantees on the novel class of support-submodular polytopes, which includes unrelated machines and polymatroids. On unrelated machines, this refutes a belief (JACM'18, SODA'25) that PF is not

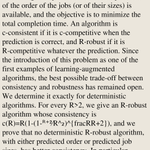
ALT We study preemptive single-machine scheduling with predictions, where a prediction of the order of the jobs (or of their sizes) is available, and the objective is to minimize the total completion time. An algorithm is c-consistent if it is c-competitive when the prediction is correct, and R-robust if it is R-competitive whatever the prediction. Since the introduction of this problem as one of the first examples of learning-augmented algorithms, the best possible trade-off between consistency and robustness has remained open. We determine it exactly for deterministic algorithms. For every R>2, we give an R-robust algorithm whose consistency is c(R)=R(1-(1-ᴿ⁺²⁄R^₂)^{fracRR+2}), and we prove that no deterministic R-robust algorithm, with either predicted order or predicted job sizes, has better consistency. In particular, consistency 1+\eps is achievable with robustness \eps^-1/2+¹⁄₆+O(√\eps), whereas all previous algorithms required robustness Θ(1/\eps). Our algorithm is greedy: it follo

ALT The asymptotic competitive ratio of online bin packing has been bracketed since 2018 by the lower bound 1.54278 of Balogh, Bekesi, Dosa, Epstein and Levin and the upper bound 1.57829 of their Advanced Harmonic algorithm. We revisit both sides with exact rational computation and prove what the computations say. On the upper bound, we rebuild the certification of Advanced Harmonic as an exact optimization over its dual parameters; with the published parameters this already certifies a ratio strictly below the published one, and re-tuning the algorithm's proportion parameters gives a certified ratio of 1.5782147437 (an exact rational), independently re-verified on all 402 scenarios. To our knowledge this is the first movement of the upper bound since 2018. On the lower bound, we prove that the 2018 adversary construction is rigid: extending it by any finite number of new batches of ordinary size (outside the window of sizes s with 2s > 1 and rational part at most 0.64819), placed anywhere

ALT The Smallest Grammar Problem (SGP) asks for a smallest straight-line grammar generating a given string, where size is the total length of the right-hand sides. Rules may be nested, so locally optimal choices of repeated fragments need not combine into an optimal grammar. We show that in an optimal grammar one can choose an occurrence of the expansion of each auxiliary nonterminal such that these intervals are pairwise disjoint. Hence the dictionary can be read off from a partition of the input, decoupling the choice of the dictionary from the parsing of rules. Using this property together with a bound on references to rules of length two, we obtain an exact algorithm running in O¹.⁸⁷²³^ⁿ time and O(n) words of space, improving the O³^ⁿ bound of Casel et al. for general grammars. For alphabet size σ and R=logσ n, we give a 2^O((n/R)log(R+1))-time algorithm, which is subexponential for fixed alphabets. Conversely, using an anchor-based projection from encoded grammars back to source gram

ALT Smith's rule orders jobs by their weight-to-processing-time ratios. We study the robustness of its list schedule on identical parallel machines when job j is ordered using a nominal processing time μⱼ and its true processing time satisfies μⱼ≤ pⱼ≤αμⱼ, where α≥1. We determine the exact worst-case approximation ratio against the clairvoyant optimum, taking the supremum over machine counts. The ratio is an explicit continuous piecewise-algebraic function of α. It equals the Kawaguchi–Kyan constant (1+√2)/2 at α=1 and is exactly √(α) for α≥4. On one machine the exact ratio is √(α). For every fixed machine count, no deterministic nonpreemptive algorithm can improve on this guarantee, even with knowledge of α. The proof reduces to a common nominal Smith ratio and endpoint errors. Cutting the list schedule at its minimum final machine load yields a prefix–suffix certificate; two packings of matching lower-bound instances explain the branches below α=4. We also prove a nominal-to-robust transf

ALT Since the early days of fine-grained complexity, many geometric problems have been shown to require quadratic time under the 3SUM Hypothesis. But as the 3SUM Hypothesis was recently refuted, these lower bounds have lost their foundation. In this note we point out that many of them can be recovered under an alternative hardness assumption, the k-AP Hypothesis. The required changes to the proofs are trivial, so the lower bounds remain just as easy to teach.

ALT We prove the all-exp property for the Traveling Salesman Problem with the 2-opt neighborhood, and for (3,2,2)- and (2,3,2)-Maximum Constraint Assignment with the flip neighborhood. The all-exp property states that infinitely many instances have an initial solution from which every sequence of improving moves to a local optimum, and hence every run of local search, has exponential length. For the Traveling Salesman Problem, the all-exp property was previously known for every k-opt neighborhood with k ≥ 3, so our result for 2-opt completes the picture for all k-kopt neighborhoods. In (p,q,r)-Maximum Constraint Assignment, each constraint involves at most p variables, each variable occurs in at most q constraints, and each domain has size r. Decreasing any of the parameters of (3,2,2) or (2,3,2) yields a problem in which every sequence of improving flips has polynomial length, so both Maximum Constraint Assignment results are tight. All three results settle long-standing open problems. Ou

ALT Data summarization techniques, such as coresets, are essential for scaling clustering algorithms to massive datasets. We study uniform sampling, which is an extremely simple and ultra-efficient method to construct coresets, in the context of weak, stable, and strong coresets for the k-means problem in Hilbert space. We begin with the fundamental case k=1, and establish matching upper and lower bounds on the sample complexity of stable and weak coresets, finding that the two notions require different sample complexities. As a consequence, we obtain tight bounds for stable 1-median coresets in ℓ₁ and ℓ₂ (and thus also Kendall–tau and Jaccard metrics), removing the dimension dependence of Carmel and Krauthgamer (ICLR 2026). Our analysis is substantially simpler than prior work and reduces to bounding the deviation of the sample mean. For the general k-means problem on ρ-separated instances, a well-studied structural assumption on the input, we show that uniform sampling yields a stable co

ALT We introduce peak-aware one-way trading (PA-OWT), an online problem in which a player must purchase a fixed quantity of an asset by a deadline, minimizing its total cost plus a charge proportional to the largest single purchase at any time. The model is motivated by electricity procurement, where the cost of energy rewards buying at low prices, but peak demand charges discourage concentrating purchases in short periods. Balancing these incentives is challenging when future prices are unknown: a large purchase can establish a peak that later decisions cannot undo. We develop a peak-aware online algorithm that balances price and peak control with deadline feasibility and achieves the order-optimal competitive ratio. We further extend our results to a learning-augmented algorithm that uses predictions of optimal purchasing decisions to achieve an order-optimal consistency-robustness tradeoff, exploiting accurate advice while retaining worst-case guarantees in the face of arbitrary predict

ALT We consider the class of open addressing hash tables that uses a fixed offset sequence r₀,r₁,…,rₙ₋₁ to find an open slot in the table. As special cases this subsumes linear probing (rᵢ=i) and quadratic probing (rᵢ=i²). We give a simple analysis that the expected insertion time when the load factor is 1-∊ is O(∊⁻²). This bound is tight for linear probing (but not for quadratic probing), so the analysis cannot be improved at this level of generality.

ALT The delayed deterministic finite automaton (D²FA) is a powerful tool for compressing the prohibitively large deterministic finite automata (DFAs) used in modern signature-based deep packet inspection systems. A D²FA augments a DFA with unlabeled default transitions to remove transitions that are similar. This technique works well in practice and has inspired numerous subsequent studies. However, existing approaches do not guarantee a D²FA of optimal size as they restrict the default transitions to form a forest. In this paper, we consider the problem of finding an optimal D²FA. We make the key observation that cycles of default transitions can be valid and produce a smaller D²FA, provided that for every character in the alphabet, at least one state in the cycle has an outgoing transition labeled by that character. This observation raises fundamental questions concerning the computational complexity of finding an optimal D²FA and the approximation guarantee of the standard (forest-restr

ALT A proper vertex coloring assigns colors to vertices so that adjacent vertices have distinct colors. A Kempe change in a proper vertex coloring exchanges two colors on one component of the subgraph induced by the vertices of those colors. For a fixed palette of k colors, textscKempe Reachability asks whether two given proper vertex colorings of the same graph are connected by a sequence of Kempe changes. This problem is known to be PSPACE-complete for every fixed k≥ 3. A graph is claw-free if no vertex has three pairwise nonadjacent neighbors. The line graph of a graph has one vertex for each edge, with two vertices adjacent exactly when the corresponding edges share an end. Line graphs are claw-free, and their Kempe changes correspond to edge-Kempe changes in the original graph, which exchange two colors on one component of the subgraph formed by the edges of those colors. A claw-free graph with a proper k-coloring has maximum degree at most 2k-2, whereas for k≥ 4 all proper k-coloring