

Open Source Data Orchestration for Analytics and Machine Learning in the Cloud @TachyonProject is now @Alluxio! [email protected]
Joined October 2015
- Tweets2.7K
- Following196
- Followers1.3K
- Likes1.7K





Healthy-looking training jobs can still lose time.
Checkpoint writes can add hidden stalls, retries, and burst traffic.
Alluxio Write Cache lands checkpoints close to compute first, then persists asynchronously to durable storage. 👇
na2.hubs.ly/H08hC6g0
#AIInfra #GPU

🧩 The AI data layer is not just where data lives.
It is how data is read, written, reused, cached, and served across the ML pipeline.
Our white paper maps the access patterns behind large-scale AI architecture:
na2.hubs.ly/H07_9910
#AIInfra #MLOps

S3 doesn’t have to be the performance ceiling.
In MLPerf Storage v3.0, Alluxio kept S3 as the system of record while delivering 147.03 GiB/s write and 124.34 GiB/s read bandwidth for Llama 3 405B checkpointing.
na2.hubs.ly/H07ZSc70
#AIInfra #MLPerf

Chasing GPUs across clouds shouldn't break your data pipelines.
Unify multi-cloud AI data access:
🔗 Single namespace across GPU clusters
⚡ 1 TB/s aggregate I/O across 10+ clouds
🔌 Keep source-of-truth data lakes intact
#MultiCloud #MLOps

🧩 Egress fees crippling your AI inference margins?
Fireworks AI optimized their model deployment pipeline:
🏷️ 50% egress cost reduction
🛠️ 4+ hrs/wk saved
🚀 8–10 GB/s load speeds
Full case study: alluxio.io/customer-stories/…
#FinOps #AIInference

📦 Copied datasets multiply in multi-cluster training.
@Coupang uses Alluxio to cache hot data near GPU jobs while the central lake stays the source of truth.
na2.hubs.ly/H07VqgL0
#AIInfra

🌐 GPUs scattered across multiple environments?
Your data doesn't have to be.
Unify data access across silos without manual copying:
🔗 Global logical view
🗂️ Single directory structure
🔌 Broad storage compatibility
na2.hubs.ly/H07SKp50
#MultiCloud #AIArchitecture

Your GPU dashboard says 100%. Your training progress says otherwise. 📉
The hidden bottleneck? The "checkpoint tax."
Writing massive 15TB+ checkpoints directly to S3 stalls your GPUs and kills training speed.
How to fix it: na2.hubs.ly/H07QZTR0
#MLOps #AIInfra

Why do AI clusters stall at a billion files? Centralized metadata.
Alluxio’s DORA eliminates these single points of failure:
▪️ Fully decentralized metadata
▪️ Near-linear scaling
▪️ Compute-side NVMe locality
Technical breakdown: na2.hubs.ly/H07NxDd0
#AIArchitecture

📉 4,241s vs. 208s.
That is the difference between reading 1TB of data across cloud regions vs. using a compute-adjacent cache.
Alluxio + Ray on Anyscale(@anyscalecompute) benchmark:
▪️ 20x faster reads
▪️ Amortized network costs
na2.hubs.ly/H07MFLT0
#AIInfra #Ray #GPU

⏱️15 minutes changes the architecture conversation.
Blackout Power Trading kept feature data in S3, added Alluxio as a low-latency cache, and scaled from 5K to 100K+ ML models in the same daily trading window.
na2.hubs.ly/H07KPSD0
#AIInfra

🌊 Keep GPUs saturated without touching your underlying data architecture:
▪️ Sub-ms time-to-first-byte (TTFB)
▪️ >90% GPU utilization
▪️ Zero data migration from object storage
Here's how it works:
na2.hubs.ly/H07Jscp0
#MLOps #AI

🔬 0.3ms average latency & 61.6 GB/s throughput.
Alluxio + @Oracle Cloud bare-metal benchmark results:
▪️ 0.3ms avg latency (WARP)
▪️ 61.6 GB/s throughput (6-node cluster)
▪️ >90% GPU utilization (MLPerf)
Read how: na2.hubs.ly/H07Gk180
#AIInfrastructure #OCI

GPUs shouldn't sit idle while models save their state.
Alluxio AI 3.9 introduces a POSIX Write Cache to eliminate distributed training bottlenecks 💽
▪️ 7.6 GiB/s per node throughput
▪️ Sub-2ms P99 latency
Read how: na2.hubs.ly/H07F1Bd0
#MLOps #GPU

How do you distribute terabyte model weights without cold start delays?
RedNote(@xiaohongshu) used Alluxio to accelerate their ML pipeline:
▪️ 10x faster model downloads
▪️ 45% higher CPU utilization
▪️ Erased storage bottlenecks
Read how: na2.hubs.ly/H07BVz-0
#MLOps #AI

PyTorch tuning is not one knob.
It is a path: storage → DataLoader → CPU preprocessing → memory copy → GPU execution.
A slowdown anywhere can limit the training job. Our eBook covers how to diagnose the path and tune the right layer.
na2.hubs.ly/H07zJsB0
#AIInfra #GPU

Multi-cloud data sync creates massive overhead.
Geely (@GeelyAutoGlobal) decoupled compute & storage with Alluxio to fix this:
⚙️ Unified namespaces
⚙️ Centralized security
⚙️ Bridged HDFS & OSS APIs
Read how:na2.hubs.ly/H07yhZk0
#MultiCloud #DataEngineering

Scaling your ML pipeline?
A one-size-fits-all storage strategy will bottleneck your AI platform. Every stage - from ingestion to inference - demands distinct data access patterns.
Explore reference architectures in our whitepaper: na2.hubs.ly/H07wYdX0
#ML #DataEngineering

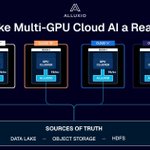
GPU scarcity means you need multi-cloud AI. The barrier? Data gravity.
Decouple compute from storage with a distributed cache to:
▪️ Access GPUs anywhere
▪️ Avoid vendor lock-in
▪️ Stop copying data lakes
Read the guide: alluxio.io/blog/make-multi-g…
#MultiCloud #GPU #AI

Stop GPUs from idling while massive LLMs download.
Fireworks AI deployed Alluxio's cache to accelerate cold starts:
🔹 1 TB/s+ throughput
🔹 750GB loads in 1-3 mins (down from hours)
🔹 Zero app changes
Read how: na2.hubs.ly/H07thN70
#MLOps #GPU #LLM
