

Building the AI Company Brain
Sydney, Australia
Joined April 2014
- Tweets830
- Following62
- Followers583
- Likes915
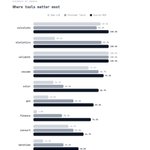




We ran gpt-5.4-nano through 240 computation problems across 10 domains.
Raw LLM: 37.9% correct
Provider tools: 56.7%
Euclid MCP tools: 74.2%
Three domains hit 100%.
Here's what we learned. (thread)
1
83
Results across all 10 domains. Sorted by where Euclid helps most.
Regex is the interesting outlier: 100% raw, 58.3% with tools. LLMs are already pattern machines. Not every domain needs a tool.

1
57
We're building Euclid: deterministic computation tools for AI agents.
This is EuclidBench, our open benchmark for measuring how well agents use tools.
More models coming. Full blog post: euclidtools.com/blog/announc…
16
1/13: LLMs are terrible at maths. Not sometimes. Reliably. Ask any frontier model to calculate NPV or convert a hex colour, it'll confidently give you the wrong answer. Fine for chat. Dealbreaker for agents. I'm building a fix. 🧵
1
15