




Pinned Tweet
Our video model runs in seconds and takes the #2-6 spots on independent benchmarks for human preference by @DesignArena
This is how far post-training and model optimization can push the frontier, building on the wonderful open work of legends like @MiniMax_AI's H3.
Incredibly proud of our small and insanely talented team. Can't wait to see what you'll all build & scale with this model! On our side we're just getting started 👀

P-Video-2 Pro (Quality) and P-Video-2 Pro (Speed) by @PrunaAI tie each other for #2 on Design Arena's Image to Video leaderboard with an Elo of 1325.
Based on MiniMax H3 by @MiniMax, P-Video-2 Pro (Quality) generates in 8.0 seconds, while P-Video-2 Pro (Speed) has an 4.5-second generation time, placing it on the Pareto frontier of Preference vs Speed.
Congratulations to the entire @PrunaAI team!


made a full music video with Claudia, @anabology's AI pop star 🎤 and open-sourced it 😍
every shot lip-synced on our video models at @PrunaAI. the whole final cut: $6.69 of video gen
here's exactly how I made it, step by step and what I learned 🧵
All available here: code, prompts, recipes, workflows, the Claude Code tool senses and skills !
github.com/LeRayan/claudia-l…
@anabology 's work was so cool to start from and hidden workflows from some big platforms get reverse engineered anyway, so I'd rather build and give it all back
Power to creatives, and i hope our very fast and affordable video models help them get even more control :)

huge thanks to @anabology for making Claudia open. none of this would be possible without it !
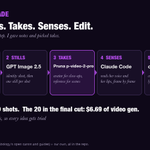
song is @suno, stills from @OpenAI GPT Image 2.5, direction with @claudeai Claude Code, video with @PrunaAI pruna.ai/p-video-2-pro-avata…
hit me up if you have questions or if I can help with anything! 💜

Not everyone wants an API. Lots of you want efficient models you run yourselves, with full control. This one's for you 💜
Qwen-Image 2.1 recommends a separate 9B prompt upsampler that reasons before it writes. It makes a huge difference, yet plenty of people still switch it off because it's slow and eats VRAM.
So one of our 6-step LoRAs distills that upsampler in. Short prompt in, no second model, no extra pass. No CFG, and the other adapter stays faithful for edits.
For infographics, dense text or prompts that need real reasoning, keep the full upsampler on.
Open weights, runs in @ComfyUI too, built on @Alibaba_Qwen's work. Go push it!

Today, we open-source v0.2 of P-Q-Image-2.1, two new 6-step LoRA adapters for Qwen-Image-2.1 by @Alibaba_Qwen. The first distillation that removes the prompt-upsampling step!
- 𝗛𝗼𝘄 𝗲𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝘁 𝗶𝘀 𝗶𝘁? Generate or edit images in just 6 steps instead of 40. Use 6-steps for preserving inputs when editing and 6-steps-upsampled for improved visual quality and shorter end-to-end generation.
- 𝗛𝗼𝘄 𝗴𝗼𝗼𝗱 𝗶𝘀 𝗶𝘁? 6-step distillation provides improved quality with few generation steps. 6-steps-upsampled is the first distillation that removes the need for a separate prompt-upsampling step. This means 41 to 80 seconds saved, depending on your prompt style.
- 𝗛𝗼𝘄 𝗱𝗼𝗲𝘀 𝗶𝘁 𝘄𝗼𝗿𝗸? The LoRA adapters load directly on top of Qwen-Image-2.1, so the pipeline stays unchanged. Few-step distillation cuts the diffusion cost, and the upsampled adapter also removes the prompt-upsampling step before image generation.
🤗 Open Weights: huggingface.co/PrunaAI/P-Q-I…
👉 HF Space: huggingface.co/spaces/PrunaA…
Top quality and the most efficient, in the same model 🤩
Post-training is a beautiful thing. I'll be posting a lot more of what our models can do
P-Video-2-Pro-Avatar is #1 in overall human ratings, at a fraction of the cost and in seconds.
- Quality: #1 of 10 models at 768p
- Cost: 7× cheaper, just $0.02/s vs $0.14/s at 480p
- Speed: 3× faster, just ~9.7s for a 10s clip at 480p
- # 1 for music videos at 768p and #2 at 480p
Across both Quality × Price and Quality × Speed, P-Video-2-Pro-Avatar stands out in the high-quality, low-cost, fast-generation region.
From UGC ads to music videos, create high-quality talking avatars without compromising on speed or budget.
Benchmarked by @RapidataAI.
🧩 API & Playground: buff.ly/OHtx3eM
📚 Documentation: buff.ly/bHQHKV0
📊 P-Bench: buff.ly/Fk54Z2K


Rayan retweeted

🗞️ Last week's efficiency papers (1) highlighted that the biggest wins come from skipping work the model doesn't need and (2) that a speedup only exists on a given machine.
Here is my selection of 5 ML efficiency papers 🧵
Step 1 complete
𝐓𝐡𝐞 𝐏𝐥𝐚𝐲𝐠𝐫𝐨𝐮𝐧𝐝 𝐢𝐬 𝐛𝐚𝐜𝐤 𝐚𝐧𝐝 𝐛𝐞𝐭𝐭𝐞𝐫 𝐭𝐡𝐚𝐧 𝐞𝐯𝐞𝐫!
If you haven’t noticed yet, the Playground is available again, now powered directly by the API. This means:
1) Forget about sharing it with others and being limited
2) No more 5-generation limit -> Use your credits to create as much as you want.
Sign up now in the Dashboard, add your payment information, and get $20 in free credits (+100 video generations), with no other commitment required!
Start creating in the Playground today: buff.ly/OHtx3eM
Rayan retweeted

I can't believe what they say on this talk show 👀
By P-Video-2-Pro-Avatar
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Best avatar model on the market!
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
A new era, and it's coming for image and video too. The question used to be "can the model do it?" It's becoming "how fast and how much?"
We bet Pruna on this second one

This is directionally consistent with our internal data @cognition. Many tasks within software engineering are now "intelligence saturated." Once any model can do the task well, cost and speed are all that matter.