

Building Apache Maka(Incubating), focusing on AI agent. 中文/EN
Joined March 2011
- Tweets2.5K
- Following542
- Followers1.7K
- Likes3.9K


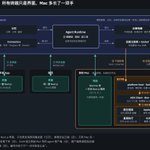


现在 Maka Rust 分支已经做到,3000 个 Agent 并行的情况下,内存占用控制到 1.2GB 了。
对比之下 Codex 大概需要十几个 GB。
Maka Rust 还在持续快速迭代中,目标下个月中完成 Rust 全面切换!

现在几乎主要的 Agent 都是用 Electron 方案,Codex、Claude...一旦同时跑的 Session 和工作多了,性能消耗和资源占用都很大,尤其是 Web 渲染的各种动画。
我们在把整个 Maka 重写为 Rust + GPUI。为未来几十/上百/上千个 agent 并行做好准备。
已经几乎可用了:
github.com/apache/maka/tree/…
现在 Maka 已经把 GUI 完全做到终端里了,在 TUI 里实现了 GUI 的效果!

刚刚基本已经完成将gui带到terminal中来,基于github.com/longbridge/nsh 并添加tui支持。
实现在分支(包括vendor的nsh的tui支持)
github.com/apache/maka/tree/…
我的操作比较墨迹,时长比较长,所以建议视频开2倍速


昨天一个海外客户下单+订单管理页面,团队找用友询价,居然报2.6万美金...
整个页面和商城都停留在 10 年前的水平,技术栈感觉也很久没更新了。
自己快速搓了个 demo,评估下一周就能开发完上线,再去 AWS 买个 VPS,预计总成本 200 美金/年。
很难想象以后这些 SaaS 还有谁采购...
所有工作先在内部按可验证证据、实际影响范围和可恢复性分级,再决定顺序与投入:P0为严重、广泛或不可恢复的核心目标、安全、资金或权限损害,立即处理;P1为核心目标、关键功能或实际交付实质受阻,优先解决,不一概视为紧急;

LlamaFactory 团队开始做 Agent 自进化了!
让 Agent 根据评测反馈改自己的指令和 skills,再用测试验证有没有用。
这个和 DSH 对 Agent Harness,还有之前的一些 Agent 自进化方向的工作不谋而合。
还开源了 awesome-rsi 和 GDPevo 评测集,做 Agent 和 RSI 的朋友可以一起关注下~

👋 Hi everyone! Long time no see
We're the LlamaFactory team. After passing 70k stars on GitHub, we're now building the "LlamaFactory" of recursive self-improvement (RSI), towards a unified, efficient, stable, and flexible framework for agent self-evolution. Excited to share our team's latest work with you all.
TL;DR:
🐧 We've open-sourced PenguinHarness, a multi-agent self-evolution framework that brings every RSI algorithm under one roof, over 2,600 GitHub stars.
📖 To get a fuller picture of existing RSI work, we went through 140 papers, organized and categorized them into the awesome-rsi repo, and published a survey paper.
📊 To compare self-evolution efficiency across algorithms fairly, we built GDPevo, a self-evolution benchmark covering 6 enterprise scenarios and 240 tasks, and used it to evaluate 6 mainstream agents.
The details:
Following the same philosophy as LlamaFactory, we want to bring all RSI-related data, models, algorithms, and benchmarks into a unified open-source harness, so everyone can try and debug RSI more easily. We've already integrated 5 RSI algorithms and 7 benchmarks, and we're aiming for 100+ down the road.
Borrowing from DSH's "everything is a plugin" approach, we've packaged every algorithm and benchmark as a plugin. They're fully decoupled, so users can freely mix and match any RSI algorithm to evolve different agents. We also built a modern desktop client that installs in one click on any OS and runs locally, so you can grab the latest version from our website.
Website: penguin.ooo/
OSS Repo: github.com/Prism-Shadow/peng…
To better understand where the academic work stands today, we open-sourced the awesome-rsi repo and published a survey paper covering 140 recent works. We also mapped the trajectory of RSI against that of deep learning — many concepts line up one-to-one, only now the subject is an agent.
OSS Repo: github.com/Prism-Shadow/awes…
Paper: arxiv.org/abs/2610.14625
To better evaluate how different harnesses and methods perform at self-evolution, we built the GDPevo benchmark, spanning 6 real-world enterprise scenarios and 240 tasks. With a train/val split, it fairly measures an agent's self-evolution ability while guarding against overfitting.
OSS Repo: github.com/Prism-Shadow/GDPe…
Paper: arxiv.org/abs/2608.03764
This post isn't just about our work. We're also hoping to invite friends from academia and industry to join our open-source project. If you'd like to see your name on an open-source project and co-author papers with us, DM us and let's talk!


ChatGPT Web 现在可以直接调用和访问本机 Chrome 标签页了!
分析了下原理,就是 ChatGPT Chrome 插件在云端注册一个浏览器会话,作为 MCP 工具连给云端的 ChatGPT,统一由云端下发指令,插件再通过 Chrome 的 CDP 接口控制本机浏览器。
但看起来真的很黑科技了,未来会有更多 Agent 跑在云上

A few big upgrades for Chrome users today! We’re bringing the power of computer use to anyone who uses Chrome.
First up: ChatGPT can now use your tabs in Chrome to make answers more useful and get things done for you.
If you’re in Chat, it can look across your open tabs and gather info.
If you’re in Work, ChatGPT can control your Chrome tabs to get things, like sending messages, filling out forms, or downloading files. It can even help you organize and group that pile of tabs you have open.
现在几乎主要的 Agent 都是用 Electron 方案,Codex、Claude...一旦同时跑的 Session 和工作多了,性能消耗和资源占用都很大,尤其是 Web 渲染的各种动画。
我们在把整个 Maka 重写为 Rust + GPUI。为未来几十/上百/上千个 agent 并行做好准备。
已经几乎可用了:
github.com/apache/maka/tree/…
RC 的新观点依然是遥遥领先,Agent Harness 已经不再适用了,现在的模型不再需要驾驭和引导,不再需要额外的 plan mode、各种复杂的 skills、一些特殊的规则。
未来需要的是针对 Agent 薄薄的 runtime以及各种给 Agent 的各种程序,提供原生接口,或者是通过 Browser use Computer Use 访问。

I've actually stopped using the word "harness." I now think in terms of two things: agent runtimes and agent applications.
Agent runtimes should be very small. Their core job is to connect an LLM API to an execution environment. That environment could be a full OS or a language VM, like a JavaScript runtime. Almost all that matters here is robustness. An agent runtime must be able to keep an agent running forever. Literally forever.
Agent applications are everything else. Yes, literally every piece of software in the world.
If software isn't built for agents, they use it through computer use or browser use. These capabilities can be built into the agent runtime or provided by another agent application.
If software is agent-native, agents should be able to use it directly. The experience of an agent using that software—what we call "agent experience"—needs to be carefully designed, at least for now, to make efficient use of both time and tokens.
Another key piece is agent identity. Agent applications should recognize each agent individually, rather than just the browser or computer it's using. This allows each agent's actions to be recorded in detail and audited in real time or after the fact.
Everything we're building at @botiverse follows from this view.
补充一点,GPT 6.1 Sol 在 Agent Arena(模型匿名打分)的 Code 领域,是表现第一名的模型。
甚至高于 Astra。
也高于 Fable 5.1 和 Opus 5.5。
但 Opus 5.5 依然更全面,整体而言是第一名,在 Chat、Work 等工作也表现的更好,更灵活。

好耶!现在 Codex GPT-6.1-Sol 的默认上下文限制扩大到 500k 了。
我个人认为对于目前几个 1M 上下文模型,500k 左右的上下文基本都是默认最佳选择。
从缓存的角度,超过这个线压缩会变得更加划算。从性能角度,一般 500k 以下,现在的主流模型表现都是稳定的。

Day 7/
We have increased default context length for GPT-6.1 Sol to 500k when used through Codex & Work, up from 272k or an ~ 80% increase.
We will go higher in the future, but it helps reduce occurrence of compactions and with tasks that require keeping a lot of context and nuance over periods of time. It was carefully tested and is the new sweet spot for most of our users. You can still override it if you want to be higher our lower, with maximum context length of GPT-6.1 Sol of 1M.
Grok Bot 产品完善速度有点快的,本身产品就做得很好了,最近又能免费接入 X,又能使用信用卡购物。
持久智能体真的要成为 Coding Agent 之后的下一个产品方向了吗?

To buy stuff, you can just take a picture of your credit card, drop it in the chat and Grok @Bot will scour the Internet for the best deal on the item you want and order it
Readers added context they thought people might want to know
xAI explicitly warns users not to include personal information in prompts, yet credit card photos may contain such information.
Grok Bot's terms state that user data and credentials may be stored in its cloud environment and require human review for financial transactions.
x.ai/legal/privacy-…
x.ai/legal/grok-bot…