

Researcher in deep-learning optimization, LLM training, and reasoning 🧠. Associate professor at UniBasel. Past: EPFL, ETH Zurich (Switzerland) 🇨🇭
Zurich
Joined February 2013
- Tweets364
- Following435
- Followers1.9K
- Likes1.2K




Aurelien Lucchi retweeted

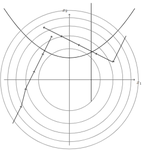
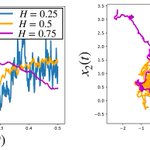
🔥 Diffusion LMs promise what autoregressive models can’t: fixing their mistakes.
But new ones often change the noise and the sampler at once. Which matters?
We tested it on the hypersphere. Noise: 0.8 points. Sampler: 25.
We introduce Spherical Brownian Diffusion 🌐 👇🧵

Aurelien Lucchi retweeted

Another evidence of OpenAI publishing results close to unpublished material from mathematicians who used OpenAI LLMs and app.
After training on copyrighted published material are they training on unpublished material?
What a bad time to be a mathematician. Should be the opposite.

Check out this loser!
>uploads a draft to Chat on Sept. 8th
>gets scooped by Chat on Oct. 6th
"The result released by OpenAI (#311) on October 6, 2026... identical to a preliminary version of the present paper that was uploaded to ChatGPT on September 8, 2026"
LMAO get rekt

Aurelien Lucchi retweeted

🎯 Learning is most effective at the frontier of capability: problems that are too easy or too hard teach nothing.
For LLM reasoners trained with GRPO this is literal: problems the model always or never solves give zero gradient.
We introduce Frontier Learning👇🧵
Aurelien Lucchi retweeted
arXiv has updated our policy on rate limiting for all submitters.
This update was made to fairly distribute moderator time & support the arXiv community of staff, volunteers, readers & authors.
Please read our announcement to learn more: blog.arxiv.org/2026/10/01/up…

ALT arXiv logo in white over a whiteboard with math symbols.
Aurelien Lucchi retweeted

🚨 We turned European train delays into a live league table.
Germany finished last. 🇩🇪
Switzerland isn't even #1. 🇨🇭
Over the last 30 days, DelayBahn tracked 900,000+ train stops across 6 countries.
Welcome to Europe's Rail Leaderboard 🏆🚆
See where your country ranks 👇
delaybahn.com/rangliste
Some of the results are wild 🧵 (1/6)

Aurelien Lucchi retweeted

#AISTATS 2027 Call for Paper is out!
This year's edition is taking place in Montreal on May 3-6th, 2027 🇨🇦
Aymeric Dieuleveut and I are chairing
virtual.aistats.org/Conferen…
New this year: AI review, and more!
Abstract deadline: September 29, 2026
Paper deadline: October 6, 2026
Aurelien Lucchi retweeted
Important points. Note also that users can opt out from use of their (de-identified) data in training. Anthropic has similar policies, though I do not remember such discussions when they announced mathematical results.


Anthropic: “Claude Team plan for Scientists!”
Me: applies
Anthropic: “We were unable to verify that you are a scientist.”


Nice. Didn't know this was an option.


We’re hiring! 🇨🇭
Join the University of Basel as a PhD student or postdoctoral researcher in the field of LLM training.
Work on:
🤖 LLM pre- and post-training
🎯 Reinforcement learning and reasoning
📈 Reliable generalization
⚙️ Large-scale experiments
📍 Basel, Switzerland
🗓 Apply by July 31, 2026
🔗 jobs.unibas.ch/offene-stelle…
#LLM #MachineLearning #PhD #Postdoc #AIJobs #Switzerland
This is a joint position with @ilijabogunovic, so you get two advisors instead of one.
Aurelien Lucchi retweeted

Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

Aurelien Lucchi retweeted

Slides from my ICML tutorial "Is numerical optimization theory irrelevant to machine learning practice in 2026?":
cs.ubc.ca/~schmidtm/Document…
(Updated to fix some typos, incorporate feedback, and add some things I did not have time for. Will link to the video here when posted.)


Aurelien Lucchi retweeted

(1/6) A Warp Drive for Neural PDE Solvers???
Tomorrow in Seoul, Till and Alex are presenting their floral #ICML2026 Spotlight. Don’t miss it if you care about neural surrogates for physics, foundation models, physics world models, …

Aurelien Lucchi retweeted

Judging optimizer gaps by looking only at language modeling with a fixed batch size is dangerous: one gets only 1/2 of the story. @orientino_ and @ruuustem_10 went beyond. Turns out that for every model, task, and data, there is always a setup where Adam > SGD. 🧵

Aurelien Lucchi retweeted

Hiring 2 summer ML research interns at the University of Basel 🇨🇭.
Research topics: RL/diffusion LLM post-training, reasoning, or LLM orchestration. Possible fully funded PhD offers to follow.
I'll be at ICLR this week and happy to chat.
Apply: forms.gle/TeeeNU6e7kDH3jX96
