

20% jokes, 80% alpha. Building an AI team that does real outreach. CM @gatedesi building Block4roots
Joined December 2022
- Tweets43.9K
- Following816
- Followers2K
- Likes34.1K




Pinned Tweet
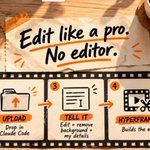
I stopped editing videos by hand.
Now I give Claude Code one prompt:
"Edit + remove background + add captions"
It takes my raw footage and hands back a finished clip.
My take: video editing is a perfect first job for AI agents. It's boring, it repeats every time, and the rules are clear.
In the video:
- Raw footage to a final edit
- Background removed
- Captions added automatically
- The full setup in 9 minutes
Link in the first reply 👇
What would you hand off to Claude first?

Block4Roots retweeted
Android Studio just stopped picking your AI for you.
The new Rabbit 2 release adds "Bring Your Own Agent"
You can run Claude, Codex or 40+ other coding agents right inside the editor, instead of switching between tabs.
If you build Android apps, try this: give the agent you already pay for one small bug from your backlog, and see how it handles a real Android project.
Which agent are you plugging in first?
Block4Roots retweeted
Q: What did GitHub just ship?
A: Agentic Workflows, now out of preview. You write a task in a plain Markdown file, and it turns into a normal GitHub Actions workflow run by a coding agent.
Q: What can it actually do?
A: Sort new issues, explain why CI failed, update docs, write tests.
Q: Is it safe to let an agent loose on my repo?
A: By default it can only read, runs in a sandbox, and its proposed changes get checked before they land.
Q: Where do I start?
A: Pick one boring weekly chore, like labelling issues. Before you switch it on, run gh aw forecast to see roughly what it will cost in AI credits.
GitHub Agentic Workflows announcement: github.blog/changelog/2026-1…
Ready-made workflows: github.com/github/gh-aw

Block4Roots retweeted
Just a little reminder that the world is better with good people in it. I hope today gives you plenty of reasons to smile and something wonderful to remember. Have a lovely day! 💰😃

Block4Roots retweeted
Someone checked where their Claude Code spend was actually going.
The biggest line wasn't their chats with Claude.
It was the little 3-5 word status line next to each background agent.
Every ~30 seconds, Claude Code sends that agent's full transcript back to the model just to write that status. In their one week of data, it took 16.4% of spend. The main conversation took 15.7%.
If you run background agents a lot, check your own setup before blaming the model. Turn on Claude Code's OpenTelemetry export, group requests by query_source, and look for agent_summary.
On a Pro or Max plan it won't show up as a bill. It eats your rate limits instead.
Flamerix AI's write-up: gist.github.com/flamerix-ai/…

Just a little reminder that the world is better with good people in it. I hope today gives you plenty of reasons to smile and something wonderful to remember. Have a lovely day! 💰😃
Block4Roots retweeted
GitHub just shipped Copilot Fusion.
It scored 60 on Artificial Analysis' Coding Agent Index. Claude Code with Opus 5.5 Max scored 62.
Fusion cost $5.59 per task. Claude Code cost $11.42.
The interesting part isn't the score. It's how Fusion picks models, because you can copy it in your own agents 👇
Block4Roots retweeted
ChatGPT Pro users lose half their limits tomorrow, and everyone's asking "which AI should I switch to?"
Wrong question.
Don't pick a model, pick the job. Thumbnail? Resume? Reels? PDF summary? Each one has a different best tool, and often the free one is good enough.
Pehle kaam decide karo, phir tool. Paisa baad mein.
Block4Roots, free AI tool map: block4roots.com
Type your job in English or Hinglish and get 3 picks: the best, the best free and the easiest. 111 tools, 12 jobs.

GitHub just shipped Copilot Fusion.
It scored 60 on Artificial Analysis' Coding Agent Index. Claude Code with Opus 5.5 Max scored 62.
Fusion cost $5.59 per task. Claude Code cost $11.42.
The interesting part isn't the score. It's how Fusion picks models, because you can copy it in your own agents 👇
Fusion runs each task one of 3 ways:
1. Single: one model does the job. Use this for easy tasks.
2. Cascade: a cheap model writes a draft, a check looks at it, and only weak drafts go to the expensive model.
3. Critique: one model drafts, other models review it, then the first model fixes it.
Most of us send every task to the most expensive model. Fusion only pays for a stronger model when the task needs it.
Copilot Fusion announcement: github.blog/changelog/2026-1…
Copilot Fusion docs: docs.github.com/en/copilot/c…
Artificial Analysis benchmark: artificialanalysis.ai/articl…

GM ☀️ My AI agents worked all night. I just woke up and took the credit."
If you'd rather go Hinglish: "GM ☀️ Chai pehle, prompts baad mein."
Block4Roots retweeted
Google shipped two frontier models in two weeks.
Argon, then Carbon. Carbon is now #1 on Artificial Analysis.
If you picked "the best AI model" last month, that pick is already old.
Don't marry a model. Build your workflows so you can swap one out in a minute.


I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!

Google shipped two frontier models in two weeks.
Argon, then Carbon. Carbon is now #1 on Artificial Analysis.
If you picked "the best AI model" last month, that pick is already old.
Don't marry a model. Build your workflows so you can swap one out in a minute.
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!