

RL scaling @thinkymachines | Ph.D. @UCSanDiego
San Diego
Joined November 2021
- Tweets485
- Following788
- Followers1.4K
- Likes2.1K
Pinned Tweet
Pretraining has scaling laws to guide compute allocation. But for RL on LLMs, we lack a practical guide on how to spend compute wisely.
We show the optimal compute allocation in LLM RL scales predictably.
↓ Key takeaways below
Zhoujun (Jorge) Cheng retweeted

Besides Inkling 2 Mini (aka Loopling), we also share a variable-looped model, TML-d24-varloop-research, because Inkling 2 Mini only supports a fixed number of looping passes.
thinkingmachines.ai/model-ca…
Studying the variable-loop model, we saw that performances on long-context benchmarks improve with more passes, such as GraphWalks BFS and MRCR v2; but knowledge-intensive benchmarks doesn’t improve with more passes, such as AA-Omniscience, SimpleQA Verified, SimpleVQA, and WorldVQA.
We shipped Inkling 1.0 on July 15, 2026. Now Inkling 2 Mini outperforms it in almost every way at just 2.7% of the size. That’s how we iterate at Thinky :bufo-ship:
Enjoy Inkling in your pocket!


Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…

Zhoujun (Jorge) Cheng retweeted

Thinking Machines has released Inkling 2 Mini at 20 on the Artificial Analysis Intelligence Index, an open weights looped transformer on the Pareto frontier for Intelligence vs. Active Parameters
Inkling 2 Mini is a 26B total, 5.4B active parameter mixture-of-experts model. The 5.4B active parameter count includes three passes through its looped layers; it uses 3.1B unique weights per text token, and it is small enough to run on a MacBook or DGX Spark.
It is released under an Apache 2.0 license, with text and image input and a 1M token context window.
Congratulations to @thinkymachines on the release! 🧵

Zhoujun (Jorge) Cheng retweeted

Inkling can now run on your laptop!
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

inklinklinkling
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted
mini model is out.
27B looping MoE, 3B active.
fits on a 32GB memory machine.
Been running this on my DGX Spark, Mac Mini.
Evals are roughly as good as Qwen 3.8 27B.
On my DGX Spark, got it to run roughly at 75 tok/s decode so far (my agents are actively trying to make it go faster).
Hopefully r/localLlama will be more happy now ;-)
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

Behind the scenes of plane bench:
Yesterday, @luke_drago_ and I asked @miramurati over lunch if we could catch “the next flight” to record Inkling 2 Mini on a plane to demonstrate its local performance without wifi. She said yes, and plane bench was born.
We were in the airport two hours later with tickets for LA. Unfortunately that flight got delayed until it was dark outside, so we couldn’t get the right lighting to record. We ended up in LA last night with two constraints:
- Our return flight was set to land just before 9am.
- Our model was set to go out around noon.
If we couldn’t get it during the ~30 minutes we were at cruising altitude and turn it around in time for the launch three hours after landing, we wouldn’t be able to land plane bench.
Because we had one chance to get this right in time for launch, we used the night in LA to optimize. We held a late night call with @ChowdhuryNeil, @simonguozirui, and @andyarditi to figure out the fastest demo we could pull off. We also pushed some optimizations including kernel improvements to make it run faster.
The video we used in the blog post was the first take from our flight this morning.


Zhoujun (Jorge) Cheng retweeted

Inkling 2 Mini for Local AI Coding 😉 it's a looped transformer
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

24 layers, middle 12 looped 3x, pruned to 26B total / 5.4B active, natively in NVFP4 🚀
that's Inkling 2 Mini: a small point on our scaling ladder 🪜 logit-distilled from a big one. small enough to run on your own device, strong enough for agentic work
open weights!
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

Time to lose weight
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

Loooop
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

Loop transformer, 26.4B total parameters, 3.4B active. Inkling-2 Mini is a light weight beast that fits on your Macbook.

Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
Zhoujun (Jorge) Cheng retweeted

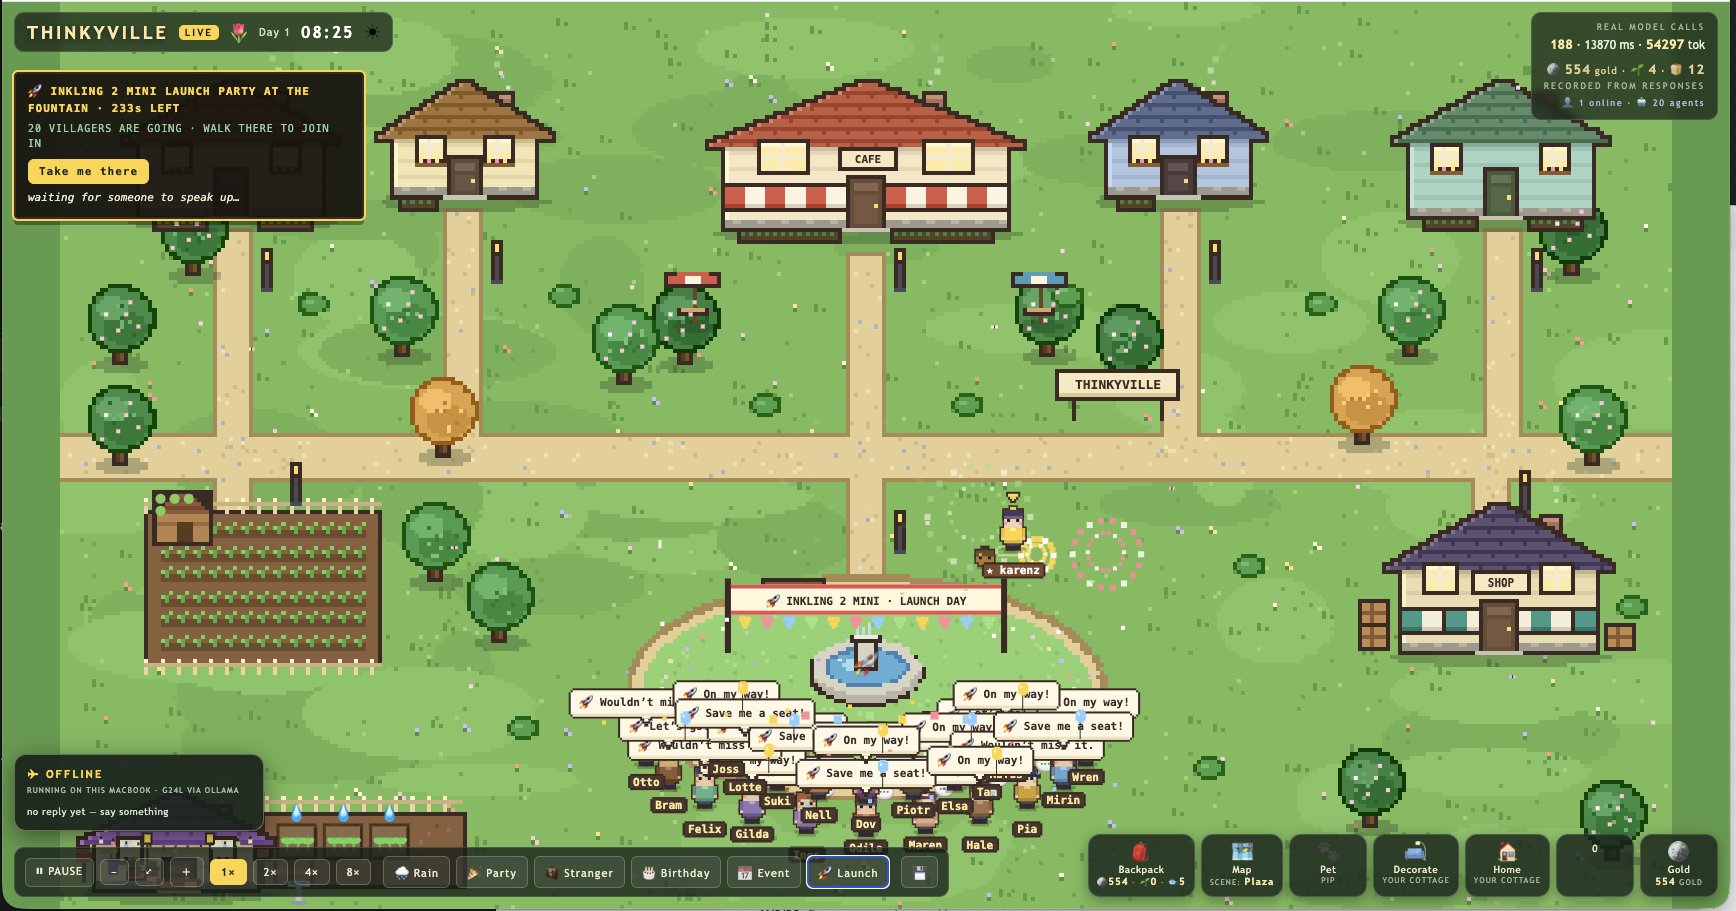
i spent a lot of childhood summers playing the sims. so for our launch i asked inkling 2 mini to build a little nostalgic town Thinkyville, and a few prompts later it had built the whole thing with 20 inkling 2 mini villagers running on my MacBook wifi off. check out the video in the blog post!!
Zhoujun (Jorge) Cheng retweeted

🖥️ Two years after we introduced OSWorld, frontier models have rapidly advanced in computer use, completing real workflows across the digital world.
🖥️ 🔜 🤖: Physical interaction is the next frontier, where foundation models expand into robot-use agents in the physical world while retaining their general intelligence. Agents like Claude Fable 5.2 already score 65% on RoboDojo. Problem already largely solved?
Not even close.
🚀 Today we introduce RoboWild: Can Frontier Models Generalize to Robot Use in the Wild?
🏠 38 furnished realistic scenes, from homes and stores to workshops and labs
🛠️ 4,480 objects, with operable doors, dials, drawers, and more
🤖 341 diverse tasks across four robot embodiments
📊 Best results: Claude Fable 5.2 reaches the highest accuracy at 13.3% on RoboWild, while GPT-6 Astra is far more token-efficient yet plateaus at 11.6%. No model is close to solving real robot use yet!
🏠 Homepage: robowild.xlang.ai
📄 Paper: huggingface.co/datasets/xlan…
📽️ Slides docs.google.com/presentation…
💻 Code: github.com/xlang-ai/RoboWild
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
Zhoujun (Jorge) Cheng retweeted

You asked, we delivered - Inkling 2 Mini! Small enough to run locally or do research on
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
beep boop loop!
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…
1
25
573
Zhoujun (Jorge) Cheng retweeted

Inkling 2 Small’s weights are now available for download on HuggingFace under an Apache 2.0 license.
Make Inkling your own!
huggingface.co/thinkingmachi…

🤗
Training with fewer bits is faster, but quantization error can interfere with learning.
Today on Connectionism, we detail how we trained Inkling 2 Small with a native 4-bit forward pass from the first step of pretraining through the final RL rollout.
thinkingmachines.ai/blog/end…

1
20
1,059
Zhoujun (Jorge) Cheng retweeted
Training with fewer bits is faster, but quantization error can interfere with learning.
Today on Connectionism, we detail how we trained Inkling 2 Small with a native 4-bit forward pass from the first step of pretraining through the final RL rollout.
thinkingmachines.ai/blog/end…
Zhoujun (Jorge) Cheng retweeted

Inkling 2 Small is our first model trained partly in NVFP4, with a mixed-precision recipe that enables a great tradeoff between speed and accuracy. Check out our new post to see how we did it, and the lessons we learned along the way!
Training with fewer bits is faster, but quantization error can interfere with learning.
Today on Connectionism, we detail how we trained Inkling 2 Small with a native 4-bit forward pass from the first step of pretraining through the final RL rollout.
thinkingmachines.ai/blog/end…