
Working on interpretability @MIT_CSAIL CS @MIT, ex HRT intern
Joined October 2025
- Tweets16
- Following182
- Followers128
- Likes40




Chris Ge retweeted

New Paper 📄: LMs just want to explain themselves!
When we SFT an LM on explanations of its own behaviors, do they learn to actually introspect, or do they merely imitate the original training distribution?
We find evidence for the former.
Despite training on a static set of explanations from a base model, the SFT-ed model explains its own current behaviors better than the base model’s behaviors, tracking behavioral drift even when we don’t explicitly train it to.
We call this introspective coupling: self-explanations track a model’s own behavior as that behavior changes, and it shows promise in making introspection training a part of scalable post-training pipelines. 🧵

Chris Ge retweeted

New @fulcrum_inc research: Inverse Rubric Optimization (IRO), a testbed for agent science.
Long-horizon tasks are often noisy, making them hard to study. In IRO, an agent learns a hidden judge's preferences under a label budget. We observe rich agent behavior and smooth scaling.

Chris Ge retweeted

How can we tell whether a brain region causally represents a visual concept, rather than merely correlating with it?
Introducing BrainCause, a framework combining generative and brain models to create controlled stimuli and causally test neural representations.
More below 🧠👇
For more qualitative and quantitative results, check out our paper and project page.
Project: chrisg777.github.io/i2i-inte…
Code: github.com/ChrisG777/i2i-int…
Paper: arxiv.org/abs/2605.24624
This work was done in collaboration with @rohitgandikota, Antonio Torralba, and @TamarRottShaham

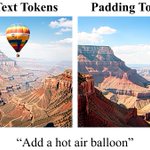
I2I → I2I Patching shows the text-token activations themselves causally carry the reference content. We transplant them from one edit run into another with a different reference image, and the source's reference-specific properties transfer over.


In FLUX.2, text, reference image, and output image tokens are all combined into a single multimodal attention stream. We probe what the text tokens carry through three interventions: T2I Lens (read), Attention Knockout (sever), I2I-to-I2I Patching (transfer).

Come check out our work on better utilizing agentic coding benchmark evaluation data, presented at #ICLR2026 Agents in the Wild Workshop!


