

France
Joined December 2008
- Tweets3.3K
- Following1.2K
- Followers818
- Likes709



CodeWorks retweeted

Anthropic senior engineer just released a 1-hour course on building a team of agents with loops & graphs:
• 00:27 - introduction to CLAUDE.md & Plan mode
• 11:24 - building "skills" & "hooks" for Claude agents
• 37:02 - building agents & subagents with Claude
• 52:47 - self-improving loops & graphs for Claude agents
this 1-hour watch will replace a $500 agentic engineering course
watch today, then read how to build a team of self-improving agents that work together

CodeWorks retweeted

Google Brain founder Andrew Ng:
"Prompting will be dead in 6 months
Agent harnesses built with loops and graphs will replace it"
Agent → Harness → Feedback → Loops → Graphs → Self-Improving Systems
In this 1-hour Stanford lecture, he explains what the best engineers are building instead and how you can start today
Prompt → Run → Verify → Improve
The first 20 minutes teach what most $1,500 courses try to sell you
For free
Bookmark and watch it today
Then read the guide below on building an agent harness that improves itself


CodeWorks retweeted

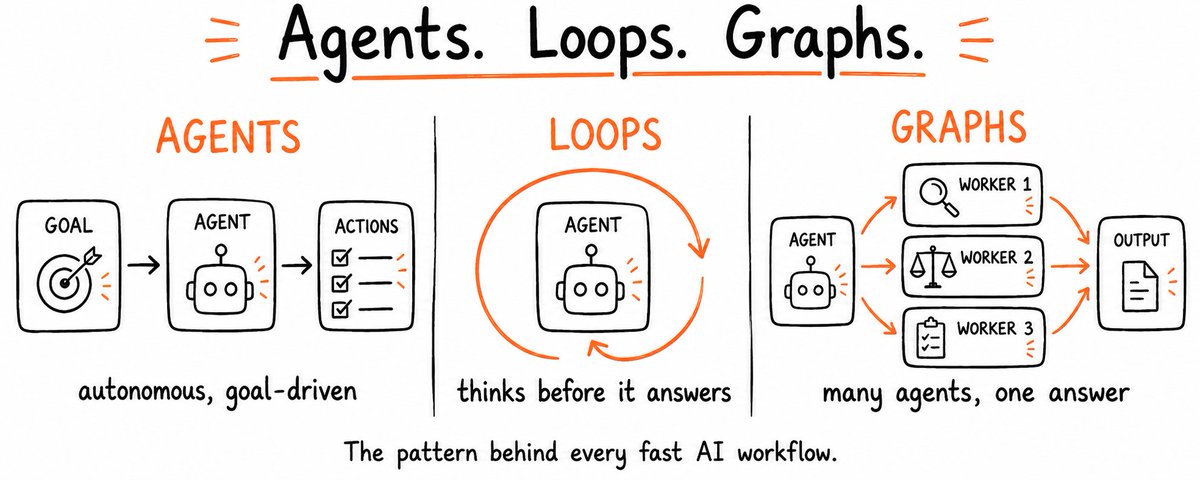
Google just dropped the best 1-hour course on Graph Engineering: from one agent to a full 24/7 system
00:00 - What Graphs are
09:16 - Build an agent
21:15 - Graph engineering explained
41:03 - Graph engineering practice
52:21 - Self improving Graphs
Free, the best thing on Graph engineering I've come across
Watch it, then read the full guide on agents and graphs below.


CodeWorks retweeted
instead of watching 2 hours of Netflix tonight, watch this Stanford lecture given by Anthropic engineers
it's the clearest explanation I've seen of how AI agents actually work
useful whether you've never touched AI in your life or have been building with it every day
i took the key ideas and turned them into a practical guide, with ready-to-copy prompts
watch it, then read the guide below on the easiest way to build your own AI agent team that improves itself over time
CodeWorks retweeted

Anthropic engineer:
"99% of people use Claude Code like Google, and only 1% are running swarms of self-learning Claude agents
I'm running 100+ agents in a loop. I have Chief agent, PM agents - they manage the whole team"
in a 30-minute workshop, an Anthropic engineer revealed how to get max value from Claude Code at min. cost
this is worth more than another $500 vibe-coding course
watch today, then read how to build self-improving agentic systems with Fable in the article below
CodeWorks retweeted

Build your own harness, folks.
This is absolute banger paper from NVIDIA on self-evolving agent harnesses.
(bookmark it)
They introduce SoL-Pi which cuts token traffic by nearly half.
And it matches its baseline harness on GPT-5.6 Sol and Opus 5.
More details below:
Instead of tuning a harness by hand, they run auto-research loops at the harness layer across many repository-derived and verifier-driven environments, keeping only the mechanisms that survive selection.
Four mechanisms survived:
> Action Fusion changes how actions execute
> Online Context Compact handles compaction during a run
> ObservationPack reshapes observation handling
> Evidence-Preserving Reducer covers delegated reading
On the 51-task EdgeBench evaluation, the savings translate to about a third off API cost. In dollars that is an estimated $8.75 to $13.50 per hour against native Codex and Claude Code harnesses, and $4.36 to $5.71 against the baseline harness.
Because the search runs across many environments rather than one, the retained mechanisms keep working outside the setting that produced them. Code is on GitHub under NVlabs.
Paper: arxiv.org/abs/2609.20519
Chat with Paper: academy.dair.ai/papers/sol-p…

CodeWorks retweeted

一个系统化的 Agent 工程学习路线图手册:Agentic Engineering Handbook。
它把散落在 OpenAI 博客、Anthropic 工程文、SDK 文档、cookbook、论文里的 179 个精选资源,整成一份从"手写 Agent Loop"到"生产落地/eval/安全"的结构化学习路径。
学习路径分 7 阶段(Phase 0–6):
Phase 0:从零手写 Agent Loop(基于 shareAI-lab/mini-claude-code,给了 v0–v4 可跑 Python 代码:bash agent → 模型当 agent → 结构化规划 → 子代理 → skills)
Phase 1:Agent 基础(该不该建 agent 的 4 问检查表、Building Effective Agents 等)
Phase 2:MCP & 工具生态
Phase 3:Context / Memory / Skills(含 Agent Skills 规范、上下文工程)
Phase 4:Harness & 长程 Agent(mini coding harness 练习)
Phase 5:Coding / Workspace Agents(Codex / Claude Code 风格工作流)
Phase 6:Evals / Safety / Production(smoke/macro eval 套件练习)
仓库:github.com/keyuchen21/agenti…

CodeWorks retweeted

This is actually insane. This uses @typesafeai Jev model, as a plugin in Claude to review all the un-nesseasary tool calls, and it takes 1s to run!
Like, literally, 1 second to take my Claude session from nearly 1M to ... 86K tokens! 😮
Ask your claude to install it and be amazed
Use this prompt
```
Install, and configure :
github.com/tamaratran/fast-j…
```


found the perfect use case for @typesafeai Jev:
instant compaction
in 2026, why is compaction still a summarization prompt?
Jev can make it instant by scoring every tool call and dropping what’s irrelevant
CodeWorks retweeted

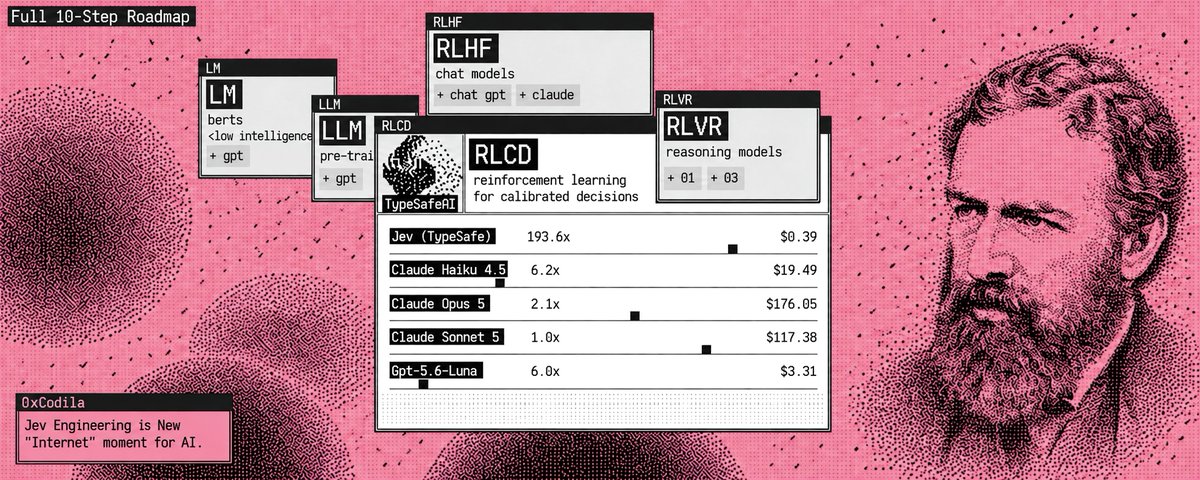
Jev is "Internet" moment for AI: up to 193x faster and 444x cheaper in tests with Claude Fable 5.1 and GPT-6 Astra
Whar is Jev, how to use and unlock its real 100х advantage in my 10-page research:
step 1 → meet Jev: LLM writes, agents act, Jev chooses the next move - split intelligence from execution
step 2 → turn every agent fork into three primitives: Choice selects one route, Score measures a defined scale, Noul returns the probability of yes
step 3 → build before getting access: use TypeSafe’s official adapter with OpenAI, Anthropic or xAI, then swap in Jev without rebuilding the graph
step 4 → setup first Jev: one state, three parallel decisions, risk-based thresholds and a real queue your agents can execute
step 5 → batch decisions instead of serializing them: 13 questions in one call ran 10x faster and 12.2x cheaper than 13 sequential calls
step 6 → place Jev at every bounded fork: choose the agent, model, tool, browser action or human escalation, then read fresh state
step 7 → benchmark the entire loop: Browser Use hit Google Flights in 7.1s, Every ran 777 checks in under 0.7s, Mobile Jev completed 9 actions in 21s
step 8 → rank wide, read narrow: Jev cut wrong Hermes skill loads from 16.8% to 7.3% and pushed legal Top-10 retrieval from 38% to 62%
step 9 → steal a system, not a prompt: Chief of Staff, model router, inbox firewall, research feed, browser controller and safety gate all use State → Questions → Action → Verify
step 10 → keep Jev out of math, writing and irreversible execution: code computes, LLMs create, Jev decides, fresh state proves the result
the result: one slow, expensive agent becomes an always-on decision machine that routes, scores and escalates in milliseconds
Copy the complete 10-page Jev blueprint - then read full 10-step roadmap below ↓


CodeWorks retweeted

Ce gars à regroupé tous les projets avec JEV qu'il a vus passer et les à rassemblés dans un seul site !
Pas mal pour voir les use cases et prendre un peu d inspiration ! Le site c est jevable.com 👇


Looking for inspiration on what you are able to do with Jev (by @typefaceai) this weekend?
Built a website called Jevable (jevable.com) which showcases all the fun demos on X - filterable by a few categories.
Feel free to add your own project by using the + button!
CodeWorks retweeted

Jev doesn’t make the LLM smarter. it makes 193x faster. 444x cheaperand testable
Jev could be the missing decision layer between LLM reasoning and real-world agent execution.
without a decision layer, you usually solve that with:
more prompting
→ more context
→ more retries
→ more tokens
Jev makes the fork explicit.
for every state:
Choice → which route wins?
Score → how good is each option?
Noul → how likely is the condition true?
then execution stays outside the model.
full Jev Engineering breakdown below ↓


CodeWorks retweeted

Google Brain founder, Andrew Ng:
"Prompting will die in 6 months. Loops and graphs are what's replacing it."
In 99 minutes he shows how to build agents that plan, execute and improve without you
Prompts → Agents → Loops → Graphs
skip a layer and it comes back as a failure you blame on the model
by the time you find it the week is already gone
that is the whole difference between using AI and having AI work for you
watch it today, then save the full guide on loops and graphs below ↓


CodeWorks retweeted

Google engineer:
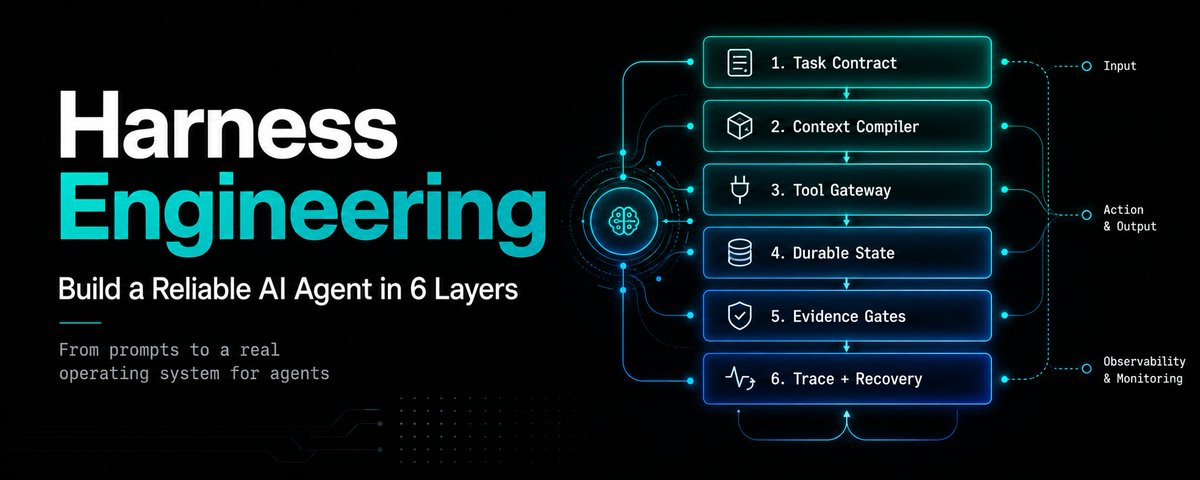
“Build a harness that runs self-improving agentic workflows for you 24/7 with loops and graphs. This is the new job!
At Google, 90% of engineers already run dozens of agentic workflows through their harnesses. This is what the new era of engineering looks like”
In this 1-hour conversation, a Google engineer breaks down what the future of AI engineering will look like
Easily worth more than 10 paid agentic courses
Watch it today, then read the article below

CodeWorks retweeted

My friend makes $1.2 million a year as an Anthropic engineer.
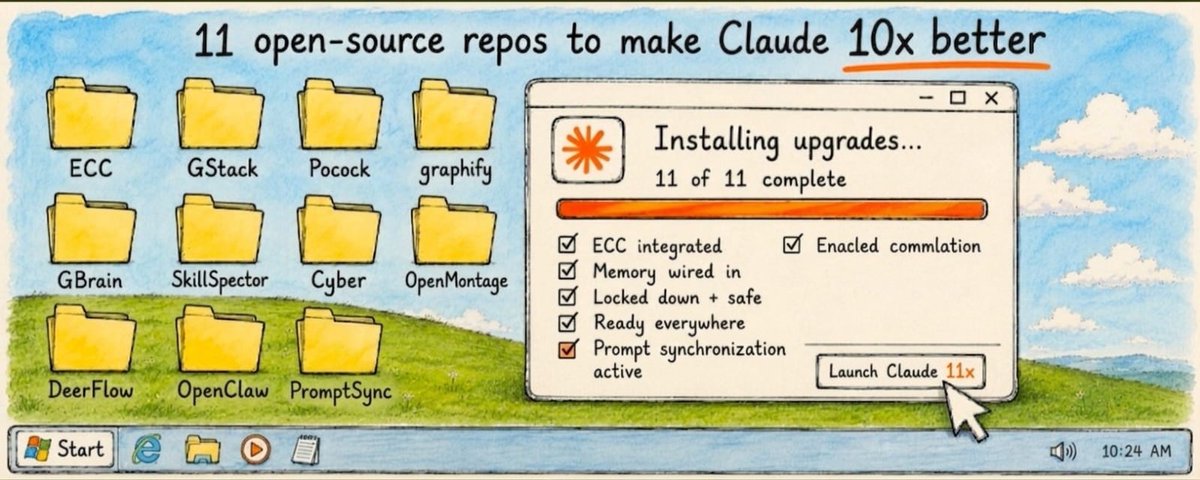
I asked him how he learned prompting so well. He sent me a video that was never supposed to get out. Their core team's prompting playbook.
You won’t find anything better about prompting than this 30 minutes video.
I watched it last night. Halfway through, I realized I've been using Claude completely wrong for two years.
Watch it, then read the article below.

CodeWorks retweeted

📢 Remember to save the date for the next @WomenTechmakers Paris meetup:
May 16th: IWD24 Paris: Crafts-Women Techmakers & Friends (@duchessfr, @LadiesCodeParis) @ncraftsConf Conferences
[Mandatory Registration]: lu.ma/joisxg95

CodeWorks retweeted

🤯 Que faire dans un projet en crise?? 🔥🔥🔥
@ToF_ vous en parle aujourd'hui ! 🧯
@CodeWorksParis #etatdelart #developpement
linkedin.com/feed/update/urn…

CodeWorks retweeted
🌈 Question du vendredi! 🧠
"Quel problème essayons-nous de résoudre ensemble ?" ➡️ @ToF_ nous répond!
#developpement #legacy #problemsolving urlz.fr/kFph
CodeWorks retweeted
⚙️ La dette technique, c'est donc juste une façon de parler. Mais de quoi, au juste ? par @ToF_ @CodeWorksParis
➡️linkedin.com/feed/update/urn…
