

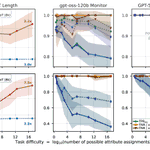
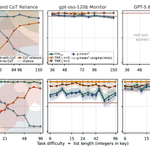
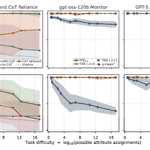
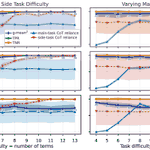


Are models more monitorable on harder tasks?
We study tasks with scalable difficulty to control how much models rely on their CoT, measured by with-CoT accuracy uplift.
Short answer: sometimes!

We should not think of LLM monitors as necessarily more reliable when monitoring hard-to-do tasks.
Increased CoT reliance can improve the narrow class of monitor errors caused by non-verbalization, but monitors still need to handle long CoTs and persuasive task models.
Read the preprint: connordilgren.github.io/asse…
Thanks to @sarahwiegreffe for advising!
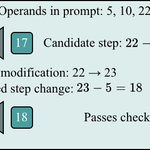
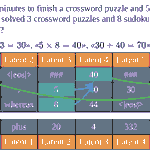
Presenting this paper at COLM tomorrow from 4:30-6:30 PM in the Grand Ballroom, poster location #136.
Come by if you want to chat about latent reasoning model interpretability or anything else!


Connor Dilgren retweeted

Today, Nolla Health became the first organization in the U.S. (and possibly the world) to receive regulatory approval for an AI to issue initial prescriptions.
This makes Nolla the first ever actual end-to-end AI doctor.
Great work by @paahrsa! Training models to predict their confidence makes them less likely to get stuck in unproductive loops.
ConfSFT seems to teach models to internally track their confidence throughout reasoning, and stop once when they're sufficiently confident.


Connor Dilgren retweeted

Is the "better writing" in the room with us?
Fable 5 wrote two novels, and we had readers find out
The good ✅: coherent 100K+ word plots and readers didn’t immediately stop
The bad 🚩: pacing, voice, and self-editing still break (+ see who swore at Claude 167 times 🤬)
👇🧵

New blog post with @sarahwiegreffe on OpenAI's Monitorability Evals!
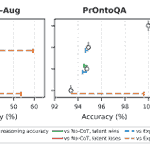
We hope to make others working with these evals aware of some weaknesses we came across, and encourage more work on chain-of-thought monitorability evals.

It would be easier to study CoT monitorability if we had a dataset of real trajectories where an agent showed some undesirable behavior on a real task. This could be created by the frontier companies (probably too much to ask), or submitted by users as they come across them.
Thanks to my advisor @sarahwiegreffe and to @IvanArcus for reviewing an earlier draft of this blog post.
We released the code and models for our preprint!
Code: github.com/connordilgren/are…
Models: huggingface.co/collections/c…
