

AI Security | AI Agents | ML Robustness | PhD @UniofOxford and @OxfordTVG | ex RS @Wise
Oxford
Joined September 2020
- Tweets78
- Following728
- Followers170
- Likes473






With 60k submissions to ICLR, the peer review system being broken already before, and agentic research flooding the field even more in the years to come, now is the time to abandon the whole system and rethink from scratch how communities can share and verify research.


Check out our work on how fine-tuning breaks contextual privacy in LLMs. Very important for the security of fine-tuned agents!
Monday 9am Great Hall at #ACL2026 in San Diego. Lead by @anmgoel.
#LLM #AI #AISafety

I'll be at #ACL2026 in San Diego, presenting our recent works spanning AI safety!
📍 Poster (Jul 6) Privacy Collapse: Benign Fine-Tuning Can Break Contextual Privacy in Language Models arxiv.org/abs/2601.15220
(1/2)
Today at #ACL2026, we are presenting out MASEval library for multi-agent system evaluation. @anmgoel is in San Diego to present poster and live demo!
📍Grand Hall | Session 3: Oral/Posters/Demos B
🕑Sunday 2pm-3.30pm
#MultiAgentSystem #AI #AIAgents #ACL #Evaluation


Stop by if you are interested in Multi-Agent Systems or AI evaluation. MASEval is a feature-rich library and our paper shows just how important multi-agent harnesses are for performance!
4. is the reason why we built github.com/parameterlab/MASE…


It's interesting how the usage of LLMs has been quickly progressing to higher levels of abstraction:
1. prompt engineering
2. context engineering
3. agent scaffold engineering (we are here now)
4. multi-agent architecture engineering
5. ???
It's also curious how people don't discuss the previous stages that much anymore. Like, no one discusses prompt engineering now, and discussions around context engineering are becoming less frequent.
8/ 🔗
Website: parameterlab.github.io/MASEv…
GitHub: github.com/parameterlab/MASE…
Docs: maseval.readthedocs.io/en/st…
arXiv: arxiv.org/abs/2603.08835
9/ Work done at @parameterlab with Alexander Rubinstein @a_rubique, Anmol Goel @anmgoel, Ahmed Heakl, Sangdoo Yun @oodgnas, Seong Joon Oh @coallaoh, and Martin Gubri @framart1
Great work lead by @anmgoel on how fragile contextual integrity can be in LLMs.
This work shows that contextual privacy degrades easily during fine-tuning on benign data and common safety benchmarks don't pick this up.
#AISecurity #AIAgents

Come see our poster today.
🗓️ Poster session 1 @ 10am
📍 Hall 3 + Hall 2B #239
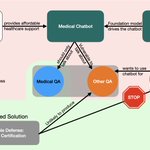
🚨 New paper alert: Our recent work on LLM safety has been accepted to ICLR 2025 🇸🇬
We propose a new framework for LLMs safety. 🧵
(1/7)
#LLM #AISafety #ICLR2025 #Certification #AdversarialRobustness #NLP #Shhhhhh #DomainCertification #AI
🚨 New paper alert: Our recent work on LLM safety has been accepted to ICLR 2025 🇸🇬
We propose a new framework for LLMs safety. 🧵
(1/7)
#LLM #AISafety #ICLR2025 #Certification #AdversarialRobustness #NLP #Shhhhhh #DomainCertification #AI
To obtain such certificates, we present a simple, scalable and powerful algorithm: VALID. Remarkably, for each unwanted response it provides a global bound in prompt space 🚀
(6/7)

Read more: cemde.github.io/Domain-Certi…
Thanks to my amazing collaborators:
- Alasdair Paren, @trojantiger88 (P. Arvind), @maximek3 (M Kayser), @tom_rainforth, @philiptorr, @Adel_Bibi at @UniofOxford
- @BernardSGhanem at @KAUST
- Thomas Lukasiewicz at @tu_wien
(7/7)
