

Cѳɳรtɑɳtiɳɛ retweeted

The chance that I install a new desktop app in 2026 is zero. It does not matter how good the app is.
Distribution through installation is over. What works instead:
> An API with docs written for models. My agent reads them and calls you. Nothing lands on my machine.
> A skill. It is a text file with instructions, and I can read it before the agent does.
> A link. Everything that can live in the browser should stay there.
If you ship a product, check which of these you have.
Cѳɳรtɑɳtiɳɛ retweeted
Lauren Tan on formal verification: "How do you know what it's proving?" "It could be proving false is true."
Cѳɳรtɑɳtiɳɛ retweeted
Software engineering is evolving, but AI doesn't make engineers obsolete.
SEs should become more like product managers, driving the product forward without waiting to be told what to do.
There is no ceiling on the potential for innovation. There's always more work to be done.
Cѳɳรtɑɳtiɳɛ retweeted

Introducing SubQ Snap, the first long-context decision model for real enterprise work.
Snap is the only decision model or LLM where compute per token stays constant as context grows.
• 384K tokens of multimodal context, 12x larger than Jev.
• 61.7 on Decision Index v0.2.1 vs Jev’s 57.9, outperforming on 13 of 16 enterprise benchmarks.
•Processes 100K tokens and returns a decision in under one second.
•$0.05/MM input tokens. Output is free.
Available today to anyone.
The first 10,000 sign-ups get 100M free input tokens.
We’ll likely hit capacity fast and will add users as we add compute. Compute offers welcome 🙂.
Latency will be variable as we tune the platform to this new model and category of users.
Model speeds are 80ms for minimal context, 250ms for 32k, 660ms for 100k, and 2.5 seconds for 384k.
Visit: subq.ai/
Cѳɳรtɑɳtiɳɛ retweeted

This for me is both extremely impressive as a technical feat and extremely misguided as a moral one / ethical one.
AI should not be allowed to be presented as human in any way. Not given human names, not given human appearance as UI. That illusion carries societal risk

The whole point of building Tavus has been simple: talking to a machine should feel as natural as talking to a friend or coworker.
It’s hard to describe all the tiny nuances that make a conversation feel human. The little expressions. Moving around in your chair. Knowing when to speak and when to listen. The dance of it all.
Griffin is by far the closest anyone has come to a model that can capture those nuances. The first time I saw it being used, I had no idea I was watching our model rather than just a normal video call.
I’m so incredibly proud of this team and what they’ve built.
Cѳɳรtɑɳtiɳɛ retweeted

“Study hard what interests you the most in the most undisciplined, irreverent, and original manner possible.”
- Richard Feynman
Richard Feynman’s quote emphasizes learning through genuine curiosity rather than following the rigid structure of traditional education. He believed the most meaningful learning happens when people pursue what interests them instead of depending on fixed syllabi or a predetermined order.
To be irreverent is to challenge accepted ideas rather than automatically treating them as true. By questioning assumptions and authority, people can develop their own understanding of the world and create an independent path toward mastering difficult or complex subjects.

Cѳɳรtɑɳtiɳɛ retweeted

Ben Thompson says the real money in AI is being made by Meta, not OpenAI or Anthropic
"The biggest impact of the models, the biggest monetization right now is probably not in Anthropic or OpenAI. It's the incremental gain that is happening for Google and Meta."
"They can actually validate their image creation and their text creation in a way no one else can. Their validation is the ad marketplace, like running a gazillion A/B tests to see what works. Most ads don't convert.”
"What do LLMs do? LLMs predict. We're going to move to this world where Meta is going to look at people and say, this person probably wants to see this next. And they're going to go find that thing and show it to them."
"The potential upside in terms of just showing people better ads that are more relevant to them, they only need to increase like a few percentage points for the returns to be billions and billions of dollars. This alone is worth them investing in being on the leading edge."
"This is why advertising is great. And Meta's advertising in particular is awesome. I get frustrated that Meta doesn't talk about that. Mark Zuckerberg has never really talked about the societal benefits of advertising except in passing in 20 years."
Cѳɳรtɑɳtiɳɛ retweeted

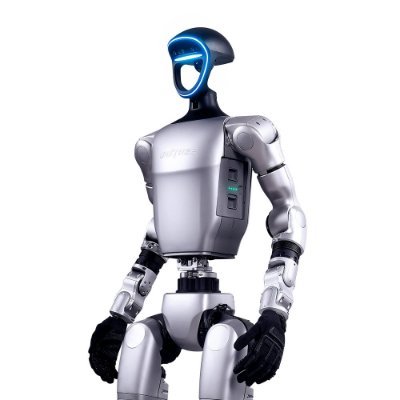
Bro casually walks and explains 5 GPU performance optimization methods for LLMs.
one of the most simple and intuitive explanations for beginners.
Cѳɳรtɑɳtiɳɛ retweeted

One pattern I find useful for working with LLMs is a nice long ramble session. Sometimes the LLM needs more bits to understand what you're trying to achieve, but you're too lazy to type them. In these cases I like to lean back, switch to /voice and just ramble for like 10 minutes, total mess, anything goes, full stream of consciousness. Sometimes I declare it up top, something like "switching to speech recognition sorry for any typos...". Sometimes I turn it into a small interview of a few turns. But I find that the LLMs are somehow very good at reconstructing long incoherent rambles and often their echo of your own tangle of thoughts comes out quite a bit cleaner than what you started with. The result is that you improve the mind meld and have to correct things less from that point on.

Cѳɳรtɑɳtiɳɛ retweeted

We're opening the waitlist for our Monetization Gateway, which will allow you to charge for any web page, dataset, API, or MCP tool behind Cloudflare. The charges will settle in stablecoins over the x402 open protocol. cfl.re/4eUFdt6

Cѳɳรtɑɳtiɳɛ retweeted

Many people think any given ML project is 99% training.
In reality, it’s 50% evaluation, 40% data cleaning, 8% integration, and 2% training.
The first two set the noise floor for learning. No ML magic matters; the model cannot lower the noise floor, as that’s the optimal bound of Shannon encoding of your data.
Thus, not a single day goes by without me thinking about ontology. Even the old labels have to be constantly reviewed.


Cѳɳรtɑɳtiɳɛ retweeted

Over the past 2 weeks, RWA trading on Hyperliquid has repeatedly broken records, surpassing $1.3B in open interest and $1.4B in weekend volume.
When traditional markets are closed, Hyperliquid is the premier venue for 24/7 price discovery on oil, metals, indices, and other essential assets. This is an important step towards housing all of finance.
Cѳɳรtɑɳtiɳɛ retweeted

There’s a fundamental problem with global wealth creation:
- Capital markets overwhelming benefit the rich
- Working income growth is massively outpaced by capital income
- Most people are unable to or priced out from participating in the best financial markets
Everyone should have the same opportunities. It shouldn’t be determined by where you're from or how much money you have.
The solution: tokenization, to unlock truly global markets for everyone.


Cѳɳรtɑɳtiɳɛ retweeted
It's very likely that LLM-assisted coding will increase productivity for several years, but in the long term, the quality of software engineers will decrease while the quantity of the slop code will become huge, so productivity will return to where it was before ChatGPT or even below it.