

Salt life | Florida Fishing | Still have no idea what twitters for...
Florida, USA
Joined July 2016
- Tweets1K
- Following283
- Followers75
- Likes21.5K
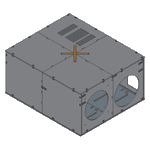




had an AI model a whole PC case for me…
410 x 350 x 200mm, room for a board + 4 GPUs + PSU
cut into 22 parts so every piece fits my AD5X's 220mm bed
zero screws. 16 snap forks in the floor, 16 in the lid, all printed flat
FreeCAD model + STEP + STLs, checked for collisions against the hardware
not printed yet. snap fit test in PETG first before i trust it with 4 GPUs 😂
model was GPT 6.1 Terra Max. would you print a case an AI designed?

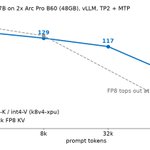
how fast my Intel box stays as the context fills up…
Qwen3.8 27B, 2x Arc Pro B60 48GB, vLLM TP2 + MTP
custom int8-K / int4-V KV cache
2k: 138 tok/s
32k: 117
128k: 77
200k: 62
stock FP8 KV: 35 tok/s at 128k and thats where it tops out
same cards, same model, just a better cache
repo + recipe: github.com/Wrapzii/k8v4-xpu
what context do you actually run your agents at?

same video gen job on both my rigs…
RTX 5070 Ti 16GB: 57s per clip
Arc Pro B60 24GB: 181s per clip
MiniMax H3 ref2video turbo, Q4_K_M GGUF, 4 steps
640x384, 124 frames (5s), ComfyUI
cold: 117s vs 292s
so video lives on the 5070 Ti now
the 2x B60s stay on LLMs where they do 60+ tok/s at 200k context
Yea CUDA still wins diffusion. anyone getting H3 fast on Arc?

Daniel retweeted

I'm launching a site for free shader assets (CC0-licensed) for use in multiple engines: currently Unity, Godot, and Unreal Engine, with more effects and platforms planned in the future. cc0shaders.com/

Daniel retweeted

Is the Intel Arc Pro B70 slow for local LLMs? Plain decode, yeah. Turn speculative decoding on and it's a different card.
People keep asking me this since I ordered four of them for my own agents. Fair question, the raw numbers are rough.
One B70 running Qwen3.8 27B Q4_K_S in llama.cpp does 26.5 tok/s generating one token at a time. Two B70s on vLLM with no MTP did 26 tok/s on a 27B INT4. That's the number people screenshot and dunk on.
One token at a time is memory bandwidth bound, and the card's matrix engines mostly sit idle. Checking 4 to 8 drafted tokens in one step costs barely more than checking one, if the kernels are written for it.
Two receipts from this week.
budiony's llama.cpp PR moved the B70's multi-token path onto the XMX engines. Same card, same 27B, MTP drafting on:
Q4_K_S 38.7 to 51.0 tok/s
Q2_K 30.2 to 63.9 tok/s
A batch of 8 tokens on Q6_K went from 79 to 159.
That PR is closed without a merge right now, so don't look for it in a release yet.
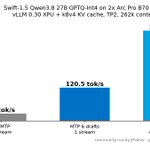
@Daniel00Higgins shared a community run (credit JP-devv) of his Swift 27B on 2x B70, vLLM 0.30 XPU, TP2, MTP with 6 draft tokens:
120.5 tok/s single stream
328 tok/s across 4 streams
262K context, 1.28M token KV pool
about 500W for the pair
Same two cards, 26 tok/s without MTP and 120 with it.
Caveat, that run was a code prompt at temperature 0, which is the best case for drafting. Prose at a higher temp accepts fewer drafts and lands lower.
The B70 is a 32GB card with a lot of compute the software is only now learning to use. If you're judging it off a single-token llama-bench number you're judging the wrong thing.
Price is moving too. @zbian73 watched an ASRock B70 go from $1,400 to $1,945 on Newegg in a few days.
I haven't put numbers on my own four yet. When I do they go up here, MTP on and off.

ALT Table of Intel Arc Pro B70 tokens per second on Qwen3.8 27B. 1x B70 llama.cpp Q4_K_S: 26.5 no drafting, 38.7 MTP old kernels, 51.0 MTP best run. 1x B70 Q2_K: 37.6, 30.2, 63.9. 2x B70 vLLM 0.30 XPU TP2 INT4: 26 without MTP, 120.5 with MTP. Sources: llama.cpp PR 29864 by budiony; community run of @Daniel00Higgins' Swift 27B.
open source video WITH lip synced audio that has a 16GB preset?
Kandinsky 6.0 Video. 3B Lite + 29B Pro, MIT license
block offload takes Pro from ~73GB peak down to ~22GB… so the 16GB preset is the one my RTX 5070 Ti gets
Yea I'm trying it tonight. anyone already got clips out of it?
aicoder.com/news/news-202610…
Someone ran my Swift 27B bake on 2x Arc Pro B70 and sent the recipe back 😂
Qwen3.8 27B GPTQ-Int4, vLLM 0.30 XPU + k8v4 cache, TP2
262k context, KV pool 1.28M tokens
120.5 tok/s single stream
328 tok/s total at 4 streams
~500W for the pair
no MTP: 26 tok/s. MTP with 6 draft tokens is literally the whole thing
full docker + vllm args in the repo, credit JP-devv
github.com/Wrapzii/k8v4-xpu/…

If ComfyUI keeps dying with "access violation" when it swaps GGUF models… try --disable-smart-memory
crashed on me 3 times in one night on my 5070 Ti 16GB
every time right when the next prompt swapped models (GGUF loader partially unloading)
with the flag models fully unload instead
zero crashes the rest of the run
slower swaps, but a queue that doesnt freeze at 2am is worth it
ComfyUI + ComfyUI-GGUF, MiniMax H3 turbo Q4_K_M
github.com/city96/ComfyUI-GG…

Said last week i couldnt tell Qwen-Image turbo from full… so i actually scored it
same refs + seeds, prompts with stuff you can check (facing direction, pose, props, 2 characters)
turbo 8-step: 98% of checks, 24.8s an image
full 25-step: 100%, 67.2s
1 partial miss for almost 3x the speed. im keeping turbo
int8 DiT, int8 ref cache on GPU, 1024x1024, 2x Arc Pro B60, ComfyUI XPU

Qwen-Image 2.1 with 6 reference images was taking 73s an image on my B60s
turned on the int8 ref cache on the GPU
31s first run
25s warm
same job. almost 3x faster
Qwen-Image 2.1 turbo int8, 8 steps, 1024x1024
Qwen3-VL-8B int8 encoder
QwenImage21Cache device=gpu dtype=int8
2x Arc Pro B60 24GB, ComfyUI XPU, ~12.7GB peak per card
github.com/comfyanonymous/Co…

Yea you dont need a BF16 MTP head
swapped my int4 draft head for the original BF16 weights
acceptance at 8k: 51.7% int4 vs 49.5% BF16
at 200k: 62.1% vs 60.1%
and BF16 was 4-6% slower
rerunning the same int4 head moves it ~2.5 points, so its a wash. keep it int4
Qwen3.8 27B GPTQ int4 (Swift 1.5), MTP 6 drafts, 4 users
2x Arc Pro B60, vLLM 0.30 XPU + k8v4 cache
BF16 MTP weights from greglechin on HF
github.com/Wrapzii/k8v4-xpu

Spent last night trying to beat my own attention kernel on the B60s
fancy idea: pass partial results through L2 in a ring instead of writing them to VRAM
result: 2.3x SLOWER 😩
boring idea: just stop writing the dead rows
21MB less VRAM writes per request, a little faster, still bit-exact
Qwen3.8 27B int4, 200k ctx, 4 users, 2x Arc Pro B60
vLLM XPU + my k8v4 cache
github.com/Wrapzii/k8v4-xpu


Anyone try the open source rust based Adobe replacements?
github.com/storytold


Daniel retweeted

Today we release 𝙻𝙵𝙼𝟸.𝟻-𝟸𝟺𝙱-𝙰𝟸𝙱, the largest 𝙻𝙵𝙼𝟸.𝟻 family member. It is an efficient local model for laptops and PCs to work through multi-step tasks inside popular agent harnesses.
> 24B total parameters, 2B active per token
> Context expanded to 131K tokens
> A 128K-token vocabulary
> 33T pretraining tokens
> It is a reasoning model
> Very easy to fine-tune and customize
> Performs competitively with Qwen3.6-35B-A3B, a model with ~50% more total and active parameters, on agentic and tool-use tasks.
> Open base and post-trained weights on @huggingface 🤗
1/

Liquid dropped d1-3B. a decision model that returns ZERO tokens
you give it a state + questions, one forward pass, typed yes/no / choice / score
vendor says 8ms on a 4090. BF16 is ~6GB so it fits a 5070 Ti with room to spare
llama.cpp support already. this is the thing you stick in front of a 27B as a router
am i the only one more excited about tiny judges than another chat model?
huggingface.co/LiquidAI/d1-3…

first community PR on k8v4-xpu just merged 🙌
davetha made one library serve both layouts, so my int8-K / int4-V cache runs on a single GPU now too
Qwen3.8 27B GPTQ int4 on ONE Arc B60 (24GB): 133k ctx, vision on
2x B60: 262k ctx, 4 sequences, text + images at once
96/96 tests passed on both cards
github.com/Wrapzii/k8v4-xpu

new benchmarks run Qwen3.8-27B as the "what people run on a 24GB card" baseline now
Yea. 16GB is starting to feel like the new 8GB
my 5070 Ti is still great for small models but 27B is where it gets tight
is 16GB still enough for local AI in 2026 or nah?
computingforgeeks.com/ollama…
