

AI Engineer · Dev Advocate @GMI_Cloud · I post what actually works when shipping AI into production · https://xitter.cf/t.co/rVLcwwCJy0
Joined August 2023
- Tweets1.4K
- Following778
- Followers176
- Likes213




Pinned Tweet
Your first AI prototype doesn't need to start with a GPU rental.
For supported models, @gmi_cloud serverless endpoints let you start without managing the serving infrastructure. Already using the OpenAI Python client? Configure GMI's endpoint, your GMI key, and an available GMI model.
Official Quick Start:
docs.gmicloud.ai/quickstart
Keep the key server-side, loaded from an environment variable or secret manager. Never ship it in browser code. Check model availability, supported parameters and current billing before sending requests—serverless does NOT mean free.
Pick a model from the current catalog rather than blindly copying an old example ID:
docs.gmicloud.ai/model-quick…
Have custom model weights or need dedicated capacity? Compare the dedicated option:
docs.gmicloud.ai/inference-e…
What AI feature would you build first? Tell me in the comments.

DeepSeek-V4.1-Flash-1017 uses a Causal Encoder-Decoder design that cuts active parameters to ~8B on prefill and 16B on decode, plus aggressive KV cache compression. This keeps the 1M context cheap for long agent runs while still improving coding benchmarks.
The architecture focus is clearly on cost efficiency rather than raw scale. Do you see encoder-decoder MoE becoming the default for agentic models?

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


A call that sounds exactly like your family member, in trouble, needing money right now — that urgency is the product.
Free defense: hang up, call back on a number you know, and keep one family safe word.
The voice can be copied. The memories can’t.
Vibe coding is real and it's still your name on every line.
AI writes the code. You review it, test it, own it when it breaks.
let's give @bot a try. First impression, the UI/UX looks amazing. its less cluttered and messy as compared to other bots.

A quick tip:
AI works best when you provide it with an example. The example should include both the input and the expected output!

AI won't take your job, a dev who uses it might.
It writes code fast, but you own what ships: review, security, taste.
Comment TASK for the one thing AI can't do from your job.
Video powered by @gmi_cloud
FYI, An AI answer with a link still needs a check.
Open the source, find the passage behind the claim, and check its date and scope.
A real page can be quoted out of context. If you can't find support, don't forward the claim as fact.
Qwen 3.8 is crazy. Using it as the base model for my personal agent. Thanks @gmi_cloud for making it free

Qwen 3.8 Max, Qwen 3.8 Flash, and Wan 3.0 are FREE on GMI Cloud for the next 12 hours
Access via your GMI API key and use in OpenCode, Hermes Agent, and more!
Running Qwen at scale? Apply for up to $10K in credits per org 👇
When you ask AI to turn notes into tasks, add:
"Use only these notes. Give each task's owner, deadline and supporting quote. If something is missing, write 'Not stated'."
Then check the quotes yourself. A tidy table can still invent a deadline.
This is huge. $668M and that kind of ARR growth doesn’t happen by accident.
Congrats to the GMI Cloud team — well earned. Still early, and that’s the exciting part.
Announcing our $668M Series B!
Led by ARCHIV with participation from @nvidia.
This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform.
Our contracted ARR has reached more than 9x since the end of 2025.
Thanks to everyone who is building with us 🙏
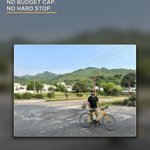
I took the bicycle out.
Leaving the desk is when an unattended agent needs a finish line.
Claude's Agent SDK defaults max_turns and max_budget_usd to no limit.
The loop keeps calling tools until the model returns text with no more tool calls. Fine when you are watching. Not fine when the prompt is "improve this codebase" and nobody is.
max_turns counts tool-use round trips only. Their own walkthrough is a four-turn test fix. Set max_turns=2 and the loop stops before the edit that made the tests pass.
When the cap hits, ResultMessage.subtype is error_max_turns. The result field is not there. If your wrapper only checks that the process ended, you will file an unfnished run as a success.
Same for max_budget_usd. Subagent spend counts. You get error_max_budget_usd, not a quiet completion.
The error result still carries session_id, so you can resume. A stop condition is not a quality setting. It pauses the work without lying that it finished.
Set both before you walk away. Then branch on subtype. success means it finished. The error subtypes mean it did not.
#AgentHarness #AIAgents #Claude #ClaudeCode #OpenAI #Codex

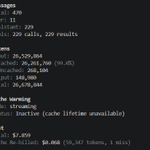
99% cache hit. 😯
229 assistant turns.
229 tool calls.
26.5 million input tokens.
$7.86.
That’s not a chat.
That’s a machine that woke up, looked at a repo, and refused to stop thinking.
Anybody want to guess the harness?👀


The open question is still the meter.
Faster and cheaper only helps if usage is visible, stable, and split by product instead of moving around inside one opaque pool.

OpenAI just shipped something that feels like a real shift from “chat with a model” to “hire an agent.”
Tibo (ChatGPT & Codex) announced dots,always-on AI agents powered by Astra.
What stands out:
• They work 24/7
• They learn from your feedback
• Each one gets its own computer and browser
• They can connect to 4,000+ apps
• Included in Pro, and they don’t burn your usage limits
• You can still talk to a dot while it’s already working
Rollout starts today with a primary dot. Next: full teams of them.
This is the product shape a lot of companies have been waiting for: not another chatbot, but persistent workers that can stay in motion while you stay in the conversation.
The open question now isn’t “can agents do tasks?”
It’s “how do we manage permissions, review, and accountability when the agent never clocks out?”
Source : @thsottiaux
#AI #OpenAI #Astra #AIAgents #FutureOfWork #Product #Automation
🤖 Made with AI
