




Pinned Tweet
🎉 Announcing our $20M Series-A funding. Excited to have @davidhornik of @lobby_vc lead this round, with participation from @SignalFire, @OpCo_VC & @SalesforceVC. Details in this post by our CEO & Co-Founder @vitalygordon: ow.ly/jSQF50OXE5K
#SeriesA #News #EngOps #FarosAI

AI has your engineers writing code faster. So why does it feel like everything else slowed down?
Join Faros on November 4 for a fireside chat on what our latest research data shows and where to intervene.
Register here: faros.ai/events/your-ai-bott…

If you are running AI coding on Amazon Bedrock, the usage data is easy to get. What it doesn’t answer is whether the spend changed how much your team ships.
We discuss AI outcomes with Jeff Grimes, Head of Global Startup Program at @awscloud: faros.ai/events/optimize-ai-…

Back in April, Faros released a research report tracking the work of 22,000 developers that shed light on how AI was absolutely transforming software engineering.
The shifts were sudden and massive.
Those findings caught everyone’s attention. Our research was shared by @FT, @TechCrunch, and @Forbes.
Today, we're releasing our follow-on report on how AI and agents are reshaping software development, and the story has moved on from where we left it in April: some of the damage is easing, but new risks are appearing further downstream.
This new 39-page report with our findings and recommendations for engineering org leaders is free to download (links below)

Download The Speed Trap report: faros.ai/research/speed-trap
See the top report takeaways: faros.ai/blog/ai-speed-trap-…

One blanket cap for every team and model means a token that ships a deployed feature looks the same as one that goes nowhere.
At ELC Annual next week, we'll show how to tell the difference: invest where AI works, reroute where it doesn't.
Grab time with us: pages.faros.ai/meet-with-far…

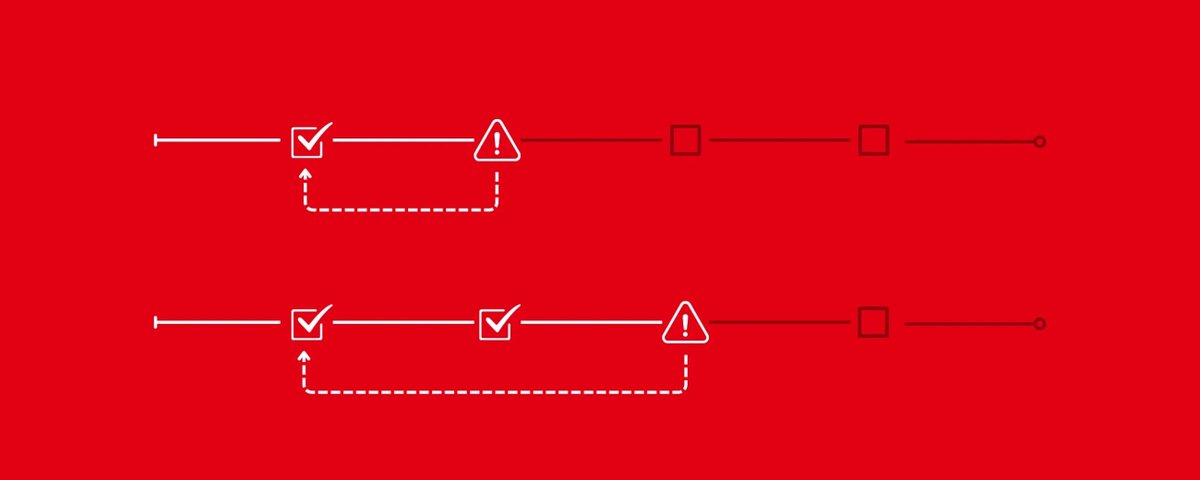
Engineering teams that lean harder on AI are seeing more of their work come back.
Find out where your work restarts come from and how to cut them with our latest research blog:


Why does your AI bill keep growing, even with cheaper models?
Why do top-benchmark models underperform on your work?
Both miss your org's context.
See why cost per outcome beats cost per token 👉 faros.ai/blog/ai-route-optim…

"I think it's evil that the industry came up with the word token because I have flashbacks of going to an arcade with no idea how much I was spending."
Usage data shows spend. Observability connects it to outcomes.
Read "Inside Faros Token Engineering": faros.ai/blog/ai-spend-obser…

Your team's AI bill probably isn't high enough.
Join our CEO @vitalygordon and Head of AI @TheChaseNorton live as they discuss token spend, and why nobody is tracking it right.
Today at 10:00am PT.
Register here: bit.ly/3Tc4yYM
Faros retweeted
So, your engineer spent $20K on AI tokens last month. Should you stop them — or promote them? Most companies still don’t know how to answer this.
As software teams adopt AI coding agents, organizations are struggling to manage token spend and engineer it into a real advantage.
Tech industry leaders I’ve spoken with who signed onto the “token maxxing” approach this spring have had some tough conversations with their CFOs this summer after burning through multi-million-dollar token budgets in a few weeks. And with no clear strategy to track the real work accomplished and features shipped from their teams’ token usage, executives are pushing knee-jerk policies across their companies like hard token caps that limit the potential of their most productive builders.
The teams most committed to realizing the huge potential gains ahead despite these growing pains are struggling to string together enough internal dashboards, approved model routers, coding harnesses, and internal policies to build their own patchwork systems for managing token spend.
These session-focused fixes may lower next month’s token bill sticker shock, but they still don’t help your organization think smarter about tying your overall token spend to the concrete work that makes your business succeed: features shipped, incidents resolved, customer issues closed, and engineering velocity improved.
You need to know whether your team's token spend is too high — or not high enough. Getting that judgment right isn't just about tracking dollars spent; it depends on model choice, the context agents are given, and how humans and agents work together on the task at hand. Each of those variables shapes what a given investment actually produces, and none of them show up in a token bill.
That discipline has a name: Token Engineering.
It treats tokens as a managed resource: measuring consumption across coding agents, attributing that consumption to shipped outcomes, and tuning model choice, context, and policy to improve the return on every token.
What does it actually take to run this day-to-day? That's where Faros comes in.
Today, we're launching the Faros Token Engineering platform to connect AI spending to the work it produces — and give teams the evidence and controls to improve that return.
Our platform connects to the business systems where AI coding work already lives — builder desktops and agents, gateways, source control, tickets, CI/CD pipelines, and incidents. From these sources, we build a live model of how your organization's AI-assisted work actually happens, tracing token spend from task to pull request, through CI, to shipped outcome. Powering this is the Time Machine, Faros's evaluation engine that finds which models, harnesses, and context produce the best outcomes for your organization.
On top of this live model, the Token Engineering platform observes the entire token flow, tracing consumption to the work it produced across every agent, builder, team, and shipped change, so leaders see what their spend delivered and builders see what's working in their own usage. We optimize how AI works on your systems, putting the right model on the right task using your own code history to prove which routes and skills actually perform, not generic benchmarks. And the platform governs AI execution, enforcing policy against real session activity and tying every shipped change back to the spend, model, and context behind it, so every decision is traceable and defensible.
Together, these capabilities turn token spend into a measurable input to the outcomes that matter: features shipped, incidents resolved, customer problems solved. The question changes from "How much did we spend?" to "What did that spend produce?"
Remember that engineer who spent $20K on tokens last month?
Imagine being able to explain what that investment accomplished — and whether another $20K would be money well spent. Sometimes the answer will be to invest more. Sometimes it will be to change how the work gets done. That’s the judgment Token Engineering should make possible.
Stop token maxxing. Start outcome maxxing.
Introducing Token Engineering.
Builders are burning huge token budgets, and leadership has no way to see what it delivered.
Faros shows what each dollar of token spend actually bought — features shipped, incidents resolved, customer issues closed — at the team and individual level.
Is your team's token spend too high, or not high enough? Faros proves which models and context perform best on your own code history, and enforces policy against it — so you can answer that, and make every dollar count.
Stop token maxxing. Start outcome maxxing.
faros.ai

Which of your AI coding investments have earned the right to scale up?
Most engineering leaders can't answer that.
We'll show you how.
Book time with our team: pages.faros.ai/meet-with-far…

Stop by booth #173 to see how engineering leaders are using intelligent tokens to trace AI coding spend to the work it produces, optimize model routes and workflows, and govern it at scale.
Book time with our team: pages.faros.ai/meet-with-far…
