

Blockchain Security Researcher https://xitter.cf/t.co/50fQBJT24o for private audits
Barcelona
Joined June 2020
- Tweets2.1K
- Following700
- Followers1.1K
- Likes6.3K





Pinned Tweet
Thanks to @flipkeygg for trusting me to audit your project. It was a pleasure working with you.
Always focused on delivering the highest-quality security service and helping clients build more secure projects.

Sometimes, as SR, we focus only on on-chain verification, but the most interesting issues can be hidden in the off-chain components.
That's why it's crucial to trace the entire transaction flow, from beginning to end, and understand how all the components interact.
Otherwise, exploits like the Kelp DAO incident can happen.
$292M lost. Zero bugs in the smart contracts.
Kelp DAO's rsETH bridge trusted 1 verifier.
The attacker poisoned 2 RPC nodes it relied on, DDoSed the rest, and the DVN attested a message that was never sent.
Great breakdown by @OpenZeppelin 👇
openzeppelin.com/news/lesson…

An important thing to remember:
Your skills and knowledge aren't defined by one bad result in a bug bounty or audit. Sometimes things don't go your way, and you can't be perfect every time.
The most important thing is to keep learning, improving, and growing. The results will come.
Web3 security is incredibly challenging. Remember, your value isn't determined by one bad result, but by your progress, the lessons you learn, and the successes you achieve over time.
Keep going. You're playing the long game.
Solidity security lesson: the same address on two chains is NOT the same account.
A CREATE address = deployer + nonce. Reach that deployer and nonce on another chain, and you own the address.
Optimism, 2022:
-20M OP sent to Wintermute's mainnet Safe address on Optimism.
-No Safe existed there yet.
-Attacker replayed the old Safe deployer txs (signed before EIP-155, no chainId).
-Then deployed Safes in batches until the nonce hit Wintermute's address, owned by him, 20M OP gone.
What I check in multichain deployments:
-Is the contract really deployed on the target chain before funds move?
-CREATE2 with the owner/config bound into the salt or initcode.
-Every signature and deploy tx includes chainId.
Some people ask me if I know of any internships.
This is one of the best programs out there, let's see which future stars this next edition brings.🫡

🚀 Kann Audits Internship Program 2.0 is here!
We're back with our second paid internship program for Security Researchers!
Looking for motivated hustlers across:
• Solidity
• Rust
• TypeScript / Off-chain
• ZK
We're giving emerging talent the opportunity to work on real security audits, build strong portfolios, collaborate with other researchers, and level up their skills.
Ready to prove yourself?
Apply here: kannaudits.com/internship
Once you've applied, comment "Applied!" below 👇

Solidity security lesson: an empty market turns 1 wei of rounding into millions.
Hundred Finance lost ~$7M on Optimism (Apr 2023) with code copied from Compound v2.
How cTokens are priced:
exchangeRate = (cash + borrows − reserves) / totalSupply
In a normal market, totalSupply is big, so rounding loses dust.
In an EMPTY market: totalSupply is tiny.
Anyone can donate tokens → cash goes up → the exchange rate explodes.
Now 1 cToken is worth a huge amount of WBTC
and every "round down" in redeem is no longer dust.
The attack:
1. Flash loan WBTC, mint, redeem almost all → hold only 2 wei of hWBTC.
2. Donate ~500 WBTC → those 2 wei are "worth" ~500 WBTC.
3. Use 2 wei hWBTC as collateral → borrow every other market dry.
4. Redeem the WBTC back: the cTokens to burn round DOWN → burn 1 wei instead of 2.
5. Repay the flash loan, keep the borrowed funds.
The attacker walks away with the loans and their collateral back.
What I check in every Compound/ERC-4626-style fork:
Can a market or vault ever reach totalSupply ≈ 0?
Does the price come from balanceOf (donation-sensitive)?
Shares burned on withdraw must round UP, shares minted on deposit round DOWN.
Seed new markets with dead shares before enabling them as collateral.
EVMbench from @OpenAI reports the following results for agents:
Detect: ~46%
Patch: ~42%
Exploit: ~72%
This is very interesting. It suggests that agents are significantly better at exploiting vulnerabilities than detecting them in the first place.
You might ask: Isn't the real challenge detecting the vulnerability, rather than exploiting it?
But what if we took a different approach?
What if we pointed agents toward acknowledged vulnerabilities and asked them to exploit them?
Since agents perform better at exploitation than detection in this benchmark, it could be worth testing whether this approach helps uncover deeper issues in real world codebases.
Instead of asking agents to find a needle in a haystack, give them a known weakness and see how far they can go.
Good morning, guys.
This weekend, I spent a lot of time reading past exploits and new EIPs, and I realized something: the more I learn, the less I feel I know.
Web3 is one of the fastest moving industries, and staying up to date requires constant learning. It's also highly technical, with an enormous amount of information to absorb.
So don't get discouraged. You're working in one of the most challenging industries, and mastering it takes time.
Keep learning, keep working, and trust the process. The results will come.
Have a happy Monday.🫡
I really like Sundays. It's the day when I work less, recharge my batteries, and prepare my goals for the next week.
And today, it's raining, which makes it even more relaxing. 🌧️
What do you usually do on Sundays?
KyberSwap Elastic lost ~$48M in 2023 because one tick crossing was skipped.
To get it, you need 1 idea from Uniswap V3 style pools:
Each LP position adds liquidity L only inside its range.
The pool marks the edges:
+L at the lower tick
−L at the upper tick
When a swap moves the price across a tick, the pool applies that marker.
That's how it knows how much liquidity is active right now.
The attack:
1. Add liquidity L in a very narrow range.
2. Swap so the price lands just past the upper tick.
3. A rounding issue in the swap math → the pool does NOT register the crossing → L should be removed, but stays active.
4. Swap back down across the same tick
→ the pool applies the marker again → active liquidity = 2L
Now the pool prices swaps as if it had 2L.
But only L is backed by real tokens.
More liquidity = more tokens out per swap.
The extra came from the other LPs.
Auditor lesson for concentrated liquidity forks:
Check every place the price can end exactly on or just past a tick boundary.
"Price moved past the tick" and "tick was crossed" must always agree.
Solidity security lesson: never pay users with send() or transfer().
One of Ethereum's first "funds stuck" bugs came from exactly this.
King of the Ether Throne, February 2016:
1. A new king paid ETH to take the throne.
2. The contract sent compensation to the previous king with send().
3. send() forwards only 2,300 gas.
4. Some kings used Mist contract wallets, which needed more than 2,300 gas to receive ETH.
5. send() failed and returned false.
6. The contract never checked the return value.
7. The king lost the throne and his payout. The ETH stayed in the contract.
Two bugs in one line:
- a hard-coded gas limit
- an unchecked return value
Why it still matters in 2026:
- a Safe needs more than 2,300 gas to receive ETH (proxy + delegatecall)
- EIP-7702 EOAs can run code on receive
- gas costs change with forks (EIP-1884 broke 2,300-gas receivers in 2019)
The fix:
Use call, check the returned value, and always follow the CEI pattern.
Or better: let users withdraw (pull) instead of pushing payments to them.
Solidity security tip: never give a transient storage slot two jobs.
SIR trading lost its entire $355K TVL to exactly this.
How the Vault worked:
1. mint() does a Uniswap V3 swap.
2. Uniswap calls back uniswapV3SwapCallback() on the Vault.
3. Anyone can call that function, so the Vault must check the caller.
The check:
mint() stores the pool address in transient slot 1
the callback runs: require(msg.sender == tload(1)).
The bug:
At the end of the callback, the Vault wrote the minted amount into the same slot 1.
Transient storage lives for the entire tx, not for a single call. So after mint(), slot 1 no longer held the pool. It held a number the user controls.
The attack, in one tx:
1. Brute-force a CREATE2 salt until the contract address, read as a number, is an amount you can mint.
2. Call mint() with inputs that mint exactly that amount → slot 1 = your address.
3. From that address, call uniswapV3SwapCallback() directly.
4. msg.sender == tload(1) passes.
5. The callback trusts you and pays out the Vault.
An address is just a 20-byte number.
If a user can write a number into the slot you use for auth, they can become "the pool".
What I check now in every audit with tstore/tload:
- one slot = one meaning.
- clear the slot right after use.
- never auth with a value the user can influence later in the same tx.
- treat everything in transient storage as alive until the tx ends.
EIP-1153 saves gas. Used wrong, it loses the bag.
Big news for Web3 security today: OpenAI is reportedly in early talks with @trailofbits about a potential acquisition.
This highlights the growing importance of security across the tech industry, especially in Web3, where security is fundamental to building trust and protecting users.
That’s one small step for man, one giant leap for Web3 security.
Yesterday, we had a talk with @BowTiedDravee at the @yAuditDAO fellowship.
You need to check this out. He shared a ton of alpha, explaining how attackers think and covering different techniques for finding the most valuable bugs.

yBorg - Week 3 Day 2
Today’s speaker: @BowTiedDravee on “Thinking Like an Attacker.”
Use attack trees: start with the goal, work backward, and challenge assumptions until attacker control reaches something breakable.
🌶️ Hot take: AI is a gun. You still need to aim.
Watch 👇
The key to finding issues in BB is to start from the end.
Identify the impact you want to achieve, then work backward to find the paths that could lead to it and figure out how they can be exploited.
I've watched interviews, joined calls, and spoken with some of the best bug hunters. One thing that consistently stands out in their methodologies is that they start from the end and work backward.
Impact → Attack path → Root cause.
Instead of asking, "What can go wrong?", ask yourself, "How can I achieve this impact?"
I'm trying different strategies to find issues using only LLMs and manually verifying their outputs.
So far, the best approach for finding deeper issues is to take the valid impacts accepted by the BB/Contest and use them as goals for an agent, asking it to break the system using the /goal command.
At @yAuditDAO fellowship, shadow audits are being conducted to evaluate how LLMs perform in real world audits. These are the results from Sentinel's first run.
What can we learn from them?
Sentinel's precision looks promising, but recall remains the main challenge.
When Sentinel reports an issue, its findings appear reliable. However, it's still missing too many issues.
Recall could improve significantly in the second run by reviewing the leads, guiding the system with the auditor's knowledge and experience to uncover deeper issues, and adding these insights to the system's knowledge base.
The goal is to combine AI's capabilities with the auditor's expertise to find what AI would otherwise miss.


This week, I found a valid High severity issue by simply guiding the AI and asking the right questions.
I wanted to run an experiment: could AI find a valid issue with me only guiding it, reviewing its output, and asking the right questions?
The answer is yes. It found a valid High severity issue that was confirmed.
What workflow did I follow?
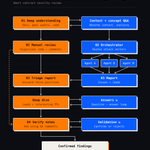
1. Build the context
I ran x-ray from @pashov’s skills to understand the protocol.
2. Spawn a swarm of agents
I used one agent per invariant, each with the goal of breaking its assigned invariant. An orchestrator coordinated the entire swarm.
3. Judge the findings
I validated the final findings using two independent judges.
4. Report the issue
The issue that survived validation was manually reviewed, confirmed to be valid, and reported.
I’m genuinely surprised by how capable AI is at finding a valid issue when you focus on guiding it rather than controlling every step.
Remember: It’s not the arrow, it’s the Indian.
Module 3 of @asen_sec’s series on building your own agent is here.
The judging phase is one of the most important steps. If it’s not done correctly, you can lose a true positive, which can be catastrophic.
Your judge needs to be strong enough to filter out false positives without missing true positives.
