FlagOS Community (@FlagOSCommunity) header
FlagOS Community (@FlagOSCommunity) profile picture

Open-source AI system software: build once, run across diverse hardware. https://teapaw.org/t.co/HTCSIytqUb

Joined August 2026
Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)
Must-Know Tips: Slow Kernels? Wrong Results? FlagPrism Finds Operator Bugs Across Chips Swap the chip and your whole debugging toolkit breaks? In this episode, meet FlagPrism — one tool for cross-chip operator debugging AND performance analysis. What's inside: 🔍 Debugger — values & addresses: pinpoints numerical anomalies like NaN/Inf down to the exact operator and memory address ⏱ Profiler — time & performance: exposes compute / synchronisation / data-movement bottlenecks on one timeline 📦 Buffered recording: traces land in a record buffer and are exported for analysis after the kernel finishes — minimal runtime overhead 📊 Unified observation: aggregate multi-chip data in one view to assist manual tuning — and future AI-driven auto-tuning
3
10
1,522
What’s actually inside the FlagOS Developer Starter Kit? 📦 It’s designed to help developers move from “new model, new hardware” to a working deployment faster: • Deployment guides • Model & hardware matrix • Cross-chip recipes • Ready-to-run demos • Benchmark templates • Troubleshooting guide Connect with FlagOS on any one of our global channels, then DM @FlagOSCommunity with your screenshot and email to unlock the kit. #FlagOSPerksWeek #FlagOS #AI #aiinfrastructure
1
8
721
🎁 FlagOS Global Developer Perks Week starts today! Connect with FlagOS across our global developer channels and unlock more resources as you go: 1️⃣ Join any 1 channel Unlock the FlagOS Developer Resource Kit. 3️⃣ Join any 3 channels Unlock the Resource Kit + GLM API credits. Limited to 500 verified participants. 5️⃣ Join all 5 channels Unlock the previous rewards + a GPU cloud compute voucher. Choose from: 𝕏 Follow @FlagOSCommunity ▶️ Subscribe on YouTube ✍️ Follow us on Medium 💬 Join our Slack 🎮 Join our Discord How to participate🤔 Complete your chosen tier DM @FlagOSCommunity with: The channels you joined Your usernames or screenshots as proof A valid email address We’ll verify your submission Eligible rewards will be delivered to the email address you provide Benefits are cumulative. Limited resources will be distributed in the order that DM submissions are verified. Please never send passwords, verification codes, private keys, or other login credentials. 📅 Nov 14–20, 2026 Build more. Spend less. #FlagOSPerksWeek #FlagOS #OpenSourceAI
1
2
16
678
Something useful for AI developers is coming tomorrow. 🎁 The FlagOS Global Developer Perks Week will bring together: 📘 A practical FlagOS Developer Starter Kit ⚡ Limited GLM API credits 🖥️ Limited GPU cloud compute vouchers Full details and the application will be announced tomorrow. 📅 Nov 14–20, 2026 Build more. Spend less. #FlagOSPerksWeek #FlagOS #OpenSourceAI
1
1
1
7
763
What slows you down most when running a mode on new hardware? Vote below.👇 #FlagOSPerksWeek #FlagOS #OpenSourceAI
0%Missing ops
100%kernelsRuntime
0%compatibilityAccuracy
0%Precision & performance
1 votes • Final results
3
167
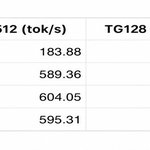
Can a 1B multimodal model run efficiently on an Arm CPU—without a GPU❓ On the 8-core CIX P1, FlagOS deploys MiniCPM-V-4.7-1B with BF16 vision and W8A8 language layers, raising total throughput from 47.57 to 95.41 tok/s versus a minimally adapted baseline.
1
1
7
380
How it’s measured: PP512 = 512 ÷ (first-token time − dispatch time); TG128 = 127 ÷ (last-token time − first-token time); Total = 640 ÷ (last-token time − dispatch time). Each test is warmed up once, run 5 times, and reported by median.
1
20
The gains are cumulative. From 47.57 tok/s, core FlagOS optimization reaches 74.34; adding a W8A8 output head reaches 82.30; using 4 Decode threads reaches 95.41. PP512 ends at 595.31 tok/s and TG128 at 21.91—showing that more Decode threads aren’t always better.
16
A full room, 100+ developers, and a day spent turning open-source energy into real technical work. 🎉Really glad to see FlagOS operators alongside PyTorch, TorchNPU, vLLM, MiniCPM/OpenBMB and the wider community—from multi-backend integration and inference to contribution workshops and hands-on building. Thanks to everyone who made it happen ❤️
You don't measure an open source ecosystem in GitHub stars. You measure it by who still shows up on the day Beijing gets its first snow. On Nov 7, Ascend for PyTorch Meetup brought maintainers from across the stack — PyTorch core and TorchNPU, @vllm_project and vLLM-Omni, MiniCPM / OpenBMB, LLaMA-Factory, PenguinHarness, FlagOS — together with more than a hundred developers in Beijing for a full day of talks, roundtables and hands-on work. Morning: multi-backend integration, TorchNPU distributed training, vLLM-Omni inference, MiniCPM on-device models, FlagOS operators, Agent tooling. Afternoon: an AI Infra roundtable, a contribution workshop walking through PR review to merge, an Agent build session — and 30+ community tasks opened on site. At #PyTorchCon China this September, the Foundation shared what that energy is turning into: more than 250 organizations across China now contribute to Foundation projects including vLLM; Chinese developers now rank among the leading contributor groups on vLLM; and Chinese open-weight models went from 2% to 45% of OpenRouter token traffic between late 2024 and April 2026. Enthusiasm is the starting point. Upstream commits are the proof. That's why a vendor-neutral home matters: ANY MODEL · ANY CHIP · ANY CLOUD · ANY AGENT — so local energy feeds the global mainline instead of fragmenting into separate regional stacks. We also want to recognize @Huawei for years of work growing this ecosystem. We're looking forward to more days like this, and to reaching even more developers who care this much. To every maintainer and developer who gave up a cold, sleety Saturday for open source: thank you. What should we build together next? Tell us in the comments.
4
492
Could AI data centers really move into orbit?❓ @elonmusk says space-based compute may cost less than infrastructure on Earth. At MICRO 2026, researchers tested that claim against launch capacity, power, cooling, servicing, networks and the economics of useful compute.
3
1
6
950
Bigger is not always cheaper. Small satellites carry too much fixed overhead; megastructures add assembly and collision-avoidance costs. Under the paper’s assumptions, the TCO minimum is ~512 GPUs per satellite with modular servicing: about $28,000 per GPU-kW-year.
1
22
Useful compute is the real test. After cost, utilization and training losses compound, the paper estimates compute per dollar for large-scale training could be ~90× lower than on Earth at the optimum. This is not 90× slower GPUs; independent inference may fit orbit better.
18
One PyTorch model runs on 8 AI chips with zero rewrites. Torch-FL gives one device entry, ~40 HAL functions light up each chip with a CPU fallback, and FlagGems / FlagTree / FlagCX pick per-kernel backends and move data. Run first, optimise later. #flagos #PyTorch #ai
1
1
6
366
Real-model shapes make Triton AutoTune expensive: a wider config space creates more optimization opportunities, but far more candidates to measure. FlagOSTune uses offline learning, targeted online search and cache reuse to find strong configurations faster. 🚀 #flagos #ai
1
1
1
6
391
Model-guided search cut average MM tuning time by 298.14× on NVIDIA H20, 15.19× on MetaX C550 and 37.74× on THead ZW810E. For MUL, average tuning-time speedups ranged from 1.13× to 3.94× across five platforms. Shortlisted configs are still benchmarked on-device.
1
17
💻Faster search still has to produce fast kernels. Against native PyTorch, selected MM configs averaged 1.1018× on H20, 0.8715× on C550 and 1.247× on PPU-ZW810E; MUL reached 1.278×–2.026× across five platforms. Tuning cost and runtime performance are reported separately.
13