

Home lab + self-host enjoyer · inference · virtualisation, networking · hardware enthusiast · building and breaking my own infrastructure. Retired Smite Pro.
United Kingdom
Joined April 2013
- Tweets8.5K
- Following1K
- Followers7.1K
- Likes12.5K





Pinned Tweet
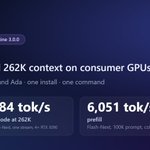
Merlin 3.0.0 is out. My Flash-Next kit is now a proper vLLM fork for RTX 30/40-series & More: ready-made recipes for seven checkpoints, one install, one command.
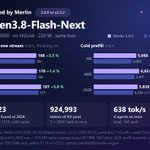
Flash-Next on 4× RTX 3090, no NVLink, 220 W:
• 184 tok/s decode at the full 262K context
• 6,051 tok/s prefill on a 100K prompt (+12 %)
• 925K-token KV pool, 3 full 262K sessions resident
• Token embedding tables in host RAM
• 8 agents at once: 638 tok/s


./setup.sh checks your specs, picks a checkpoint + layout for your GPUs and installs a prebuilt wheel within 5 mins (plus the model download), no compiling. Then merlin serve <checkpoint>.
Profiles for RTX 3090 (with or without P2P), 4090 (24/48 GB), A6000/A40, A100, A30 and CMP 170HX.

Measured, not brochure: median of 3 runs, same methodology as the v2 cards, full bench cards in the repo.
Repo: github.com/halt95/merlin-eng…
Models: huggingface.co/halt95

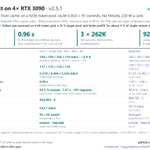
Flash-Next v2.5.1 is out: Qwen3.8-Flash-Next (125B MoE) on 4× RTX 3090, no NVLink.
• Agent follow-ups resume from cache: 0.96 s to first token
• 8 agents at once: 92.5 % cache reuse
• 925K-token KV pool (+15 %), 3 full 262K sessions resident
Swift 1.5 build updated too 👇

Engine + Merlin checkpoint: github.com/halt95/qwen38-fla… · huggingface.co/halt95/Qwen3.…
Swift 1.5: github.com/halt95/Swift1.5-q…
Genuinely surprised at how much traction my Qwen3.8 Flash-Next recipe/kit has gotten before i even tweeted, I put it on github originally to have another location to store proper production candidates. Almost 1.2k downloads on huggingface already 😅

🇬🇧HUGE: UK government publishes official rules on AI usage as part of its advice on reducing environmental impact -
- Use AI only when necessary, check if a spreadsheet/ search engine can do the job before using AI.
- Choose the smallest model capable of handling the job, such as Gemini Flash instead of Pro or GPT Instant instead of Thinking.
- Prompts should be kept short, with as few as possible used.
- Any AI-assisted work should be personally checked for accuracy.
The guidance also says it should be disclosed when AI helped create or edit content.


Further improved Running Qwen3.8 Flash-Next:
Updated to vllm 0.30
Opt-in Repeatable greedy output
Still 3 x 262k sessions running at once in the kv pool
Opt-in GPU/NUMA auto-select for other box configs
Same 160-175 tok/s decode
This one is a stability focused release/update.

Usually tweet once in a blue moon to complain at a company. Deciding to shift gears.
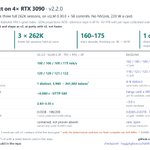
Finally managed to get Qwen3.8-Flash-Next running on 4x RTX 3090s:
807K KV pool, three full 262,144-token sessions at once
162-176 tok/s single stream
Prefill flat 10K to 261K
No NVLink, 220 W

ALT Benchmark table: Qwen3.8-Flash-Next on four RTX 3090s. 806,792-token KV pool, three 262K sessions resident, 162 to 176 tok/s decode, 5,122 tok/s prefill at 261K. Compared against v1 row by row, with one row published as a FAIL.

Usually tweet once in a blue moon to complain at a company. Deciding to shift gears.
Finally managed to get Qwen3.8-Flash-Next running on 4x RTX 3090s:
807K KV pool, three full 262,144-token sessions at once
162-176 tok/s single stream
Prefill flat 10K to 261K
No NVLink, 220 W
ALT Benchmark table: Qwen3.8-Flash-Next on four RTX 3090s. 806,792-token KV pool, three 262K sessions resident, 162 to 176 tok/s decode, 5,122 tok/s prefill at 261K. Compared against v1 row by row, with one row published as a FAIL.
TP2 x PP2 + expert parallel, both token-embedding tables out of VRAM into pinned host RAM, read inside the cudagraph. MTP K=3.
Preregistered gate, 5 boots per arm. Full bench card in the repo & fails included.
Repo: github.com/halt95/qwen38-fla…
Checkpoint: huggingface.co/halt95/Qwen3.…