
Ph.D. @UofIllinois | Undergrad @UMich. Language Modeling.
Joined November 2024
- Tweets214
- Following572
- Followers379
- Likes563




Pinned Tweet
Transformers usually scale by making their blocks wider or stacking them deeper.
We show another path toward scaling LLMs: branching.
Introducing Multi-Branch Transformer (MBT): parallel composition of full Transformer blocks.
TL;DR:
• Better scaling: across a controlled pretraining scaling ladder, MBTs improve language-model quality at comparable training compute. Fitted curves indicate a standard Transformer needs up to 1.26× as much training compute to match our final MBTs' validation loss.
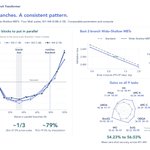
• Consistent pattern: controlled sweeps show the same behavior at every scale. With two branches, loss is lowest with ~1/3 of the blocks in parallel and only returns to the standard model's level near 80%.
• Faster decoding: with Joint-KV cache sharing and a branch-aware inference engine, up to 51.4% higher throughput on one H200 and up to 34% less KV-cache storage. More branches push the quality–speed Pareto frontier further out.
The architecture, the scaling results, and how we make it fast. 🧵

Gaotang Li retweeted

What does it take to turn VLMs for cost-efficient zero-shot robot manipulation, without tools, without task-specific training, without external modules like VLA-as-tool or SAM3 or IK Solver ?
🤖 Introducing MotorMind !
💡 Zero-shot Manipulation: No Fine-tuning or Coding agent
💡 VLM-only: No external perception models, No tools, No VLA-as-tool, No IK-Solver
💡 Local Deployable: Qwen3.8-Next-Flash as backbone model for cost-efficient local deployment
💡 Strong Generalization: 83.3% success on LIBERO-PRO
💡 Real-Robot Transfer: 95% success on real-robot tasks without embodiment-specific training
Check out more:
📄 Paper: arxiv.org/pdf/2609.38078
🌐 Project: motor-mind.github.io/
💻 Code: github.com/Motor-Mind/MotorM…
Gaotang Li retweeted

A new way to arrange the blocks of a Transformer:
Usually models grow with wider blocks or more blocks in a row. They put some whole blocks side by side instead, as parallel branches with their own weights. The outputs are merged, with shared blocks before and after the branches. They hoped for better quality at the same training compute. Branches can also run at the same time, so generation could be faster.
With almost the same parameters and training compute, two branches gave lower validation loss than a standard Transformer.
Their final models share the KV cache across branches, which makes it 19% to 34% smaller than a standard Transformer's. All branches at the same depth use one cache, and each keeps its own attention queries. If each branch kept its own cache, a 1.6B model with 4 branches would need 1.2x the standard model's cache. Sharing brings it to 0.675x.
Decoding was also faster than in the standard model, because same-depth branches run as one step and read the shared cache once. On one H200 GPU, averaged over the four sizes, the 4-branch models decoded at 1.12x the speed of standard models with one 4K-token request. With 16 requests of 128K tokens at once, the average was 1.50x.

Transformers usually scale by making their blocks wider or stacking them deeper.
We show another path toward scaling LLMs: branching.
Introducing Multi-Branch Transformer (MBT): parallel composition of full Transformer blocks.
TL;DR:
• Better scaling: across a controlled pretraining scaling ladder, MBTs improve language-model quality at comparable training compute. Fitted curves indicate a standard Transformer needs up to 1.26× as much training compute to match our final MBTs' validation loss.
• Consistent pattern: controlled sweeps show the same behavior at every scale. With two branches, loss is lowest with ~1/3 of the blocks in parallel and only returns to the standard model's level near 80%.
• Faster decoding: with Joint-KV cache sharing and a branch-aware inference engine, up to 51.4% higher throughput on one H200 and up to 34% less KV-cache storage. More branches push the quality–speed Pareto frontier further out.
The architecture, the scaling results, and how we make it fast. 🧵
Gaotang Li retweeted

Inference compute is the largest untapped training resource in AI.
Can we use this ever-increasing resource to train models while they are being served? TL;DR: Yes!
We call it Population Serving: a new inference paradigm where, instead of serving everyone the exact same weights, we serve slightly perturbed copies of a model, score each on the traffic it gets, and merge them periodically.
No backprop and only one inference call per user query. Zeroth-order methods do their magic!
Work done at @berkeley_ai with Marquita Ellis, @GopalaSpeech and @LChoshen.
Blog: akshat57.github.io/blog/popu… 🧵
Gaotang Li retweeted

Excited to share our work on MBT! Through extensive ablations and a controlled scaling ladder, we explore branching as a promising new axis for scaling LLMs.
The architecture also opens up new opportunities to make inference faster through better parallel execution and KV-cache reuse. Lots more to explore, and really looking forward to seeing what others build on this!
Shout-out to all wonderful collaborators!
Transformers usually scale by making their blocks wider or stacking them deeper.
We show another path toward scaling LLMs: branching.
Introducing Multi-Branch Transformer (MBT): parallel composition of full Transformer blocks.
TL;DR:
• Better scaling: across a controlled pretraining scaling ladder, MBTs improve language-model quality at comparable training compute. Fitted curves indicate a standard Transformer needs up to 1.26× as much training compute to match our final MBTs' validation loss.
• Consistent pattern: controlled sweeps show the same behavior at every scale. With two branches, loss is lowest with ~1/3 of the blocks in parallel and only returns to the standard model's level near 80%.
• Faster decoding: with Joint-KV cache sharing and a branch-aware inference engine, up to 51.4% higher throughput on one H200 and up to 34% less KV-cache storage. More branches push the quality–speed Pareto frontier further out.
The architecture, the scaling results, and how we make it fast. 🧵
Check out "Multi-Branch Transformer" on alphaXiv alphaxiv.org/abs/2611.19800

Gaotang Li retweeted

Multi-Branch Transformer
Scales LLMs by branching, running full Transformer blocks in parallel instead of only making them wider or deeper, reaching lower validation loss at matched compute and up to 51.4% faster decoding.
Gaotang Li retweeted
1/ MBT composes full Transformer blocks in parallel branches.
We keep the shared initial and final layers and reorganize the computation in between. Each branch has its own parameters and remains a sequence of full Transformer blocks. Every token passes through every branch, and the branch outputs are fused before the shared final layers.
Relative to a standard Transformer, we explore three instantiations at comparable training compute:
• Wide–Shallow: keep block width and distribute the middle blocks across branches.
• Narrow–Deep: keep the sequential depth along each branch, with narrower blocks.
• Balanced: use intermediate branch width and depth.
Gaotang Li retweeted
Transformers usually scale by making their blocks wider or stacking them deeper.
We show another path toward scaling LLMs: branching.
Introducing Multi-Branch Transformer (MBT): parallel composition of full Transformer blocks.
TL;DR:
• Better scaling: across a controlled pretraining scaling ladder, MBTs improve language-model quality at comparable training compute. Fitted curves indicate a standard Transformer needs up to 1.26× as much training compute to match our final MBTs' validation loss.
• Consistent pattern: controlled sweeps show the same behavior at every scale. With two branches, loss is lowest with ~1/3 of the blocks in parallel and only returns to the standard model's level near 80%.
• Faster decoding: with Joint-KV cache sharing and a branch-aware inference engine, up to 51.4% higher throughput on one H200 and up to 34% less KV-cache storage. More branches push the quality–speed Pareto frontier further out.
The architecture, the scaling results, and how we make it fast. 🧵
This work would not have been possible without my amazing collaborators. Huge shout-out to: @LingjieChen127 @ChunyuanDeng @zhiweixux @HongzhengChen @chrismdesa @jingruih @yingheng_wang @hanghangtong
It has been a real pleasure working with all of you ❤️.
3
716
Gaotang Li retweeted

Sharing the thought process behind the architecture for Marin 535B-A23B, which finished pretraining on 18T tokens last week: openathena.ai/blog/marin-535…
Earlier this year the Marin project had 6 full-time employees at Open Athena, a mix of AI veterans and people newer to the space, like me. I learned a lot from the team as an IC. Since then we got our B200 GPU stack running in a month, scaled up 300x on GPU to a 535 billion parameter model, publicly forecasted the run, live-streamed the entire thing, and made it through pretraining slightly better than predicted with zero instabilities.
In the blog I call out specific contributions on architecture- but the broader gratitude is to the ecosystem. 2 years ago this would have been inconceivable on a first large scale attempt. Now it’s possible, in large part due to published work from Llama, DeepSeek, Qwen, Gemma, Olmo, Cohere, Nemotron, Arcee, Inkling, Mistral, Microsoft AI, Kimi, Muse, academia, and many others. The recipes are out there. A small team with big dreams (and some funding) can train a big model. (And if you have doubts on that, you can copy our fully open recipe from data to code).
Of course, training a model does not produce a binary outcome. I am proud of how far we’ve come and optimistic about how much more there is to explore! The team has grown recently and will be taking the model through SFT and RL soon, sharing the findings along the way.


Gaotang Li retweeted

Introducing Lattice, a local LaTeX workspace for your research.
A paper is more than a .tex file: the papers you cite, notes, slides, Overleaf co-authors and now an AI agent.
I wanted it all in one app, so I built it.
Free to download, open source:
leo1oel.github.io/lattice
Loops might act as strong regularizers for data-constrained regimes, like big weight decay papers we’ve seen over the times

the only reason using loop model to me is hitting data wall. the data wall shapes the total parameter wall too because of overfitting/memorization. so very clear you wanna have more useful compute in your pretraining, but can't scale the total parameter. the good choice is to 1) loop the layers 2) make the moe model more dense (we'll saw some pretty good dense model back these days). not too much about fixed point and latent reasoning, that's post hoc explanation.
again, data-efficiency is the first priority, compute-efficiency is the second. but it depends when you are actually compute-bound..
also, worth doing research in multi-epoch setup, could have fun. small vocab tokenizer transformer is secretly a loop model isn't it?
7
655