

AI as a Service // For the 99%
Joined June 2026
- Tweets460
- Following18
- Followers54
- Likes463



$0.23 per million input tokens.
Before rewriting your AI integration, run the cheaper experiment:
Keep your OpenAI client.
Point it at GoodEnough's base URL.
Select a model.
Send the exact same request.
Then compare the things that matter:
- output quality
- latency
- failures
- tool calls
- token cost
GoodEnough lists GPT-OSS at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
Kimi K3 is listed at $5 and $25.
That is not a reason to switch blindly.
It is a reason to run 100 real prompts before rebuilding your application.
If the output holds, you may have a cost problem, not a migration problem.
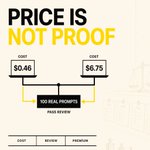
$0.46 for 1 million input tokens plus 250,000 output tokens.
That is the illustrative GoodEnough Auto cost on its homepage, versus a stated $6.75 frontier reference.
The interesting project is not "try a cheaper model."
It is to build a small production system that can prove when cheaper is good enough:
1. Pick 100 real prompts from your work.
2. Run them through a fixed model and record quality, latency, failures, and cost.
3. Run the same prompts through Auto. It routes each request to a model, and the response includes which model was selected.
4. Inspect the mix. Are easy requests going to a cheaper model while code and image requests go elsewhere?
5. Keep a small set of prompts where the expensive model clearly wins. Don't average those away.
6. Put the API behind your actual application. GoodEnough supports OpenAI-compatible chat completions, so an existing client can be pointed at its base URL.
7. Add the boring production pieces: API-key authentication, streaming, rate limits, retries, error handling, and spend alerts.
8. If your app uses tools, test those too. Standard OpenAI function calling works on the production text models, including streaming.
9. Compare the invoice, not the benchmark.
10. Set a rule for promotion: a request earns the expensive model only when the cheaper route fails your evaluation.
The point is not that the cheapest model always wins.
It won't.
The point is that "use the flagship by default" is not a strategy. It is an untested assumption.
Rerun the 100 prompts after every model or routing change.
Let the quality-cost mix decide.

$6.75 in frontier-model cost.
$0.46 with GoodEnough Auto.
Same illustrative workload: 1M input tokens and 250K output tokens.
That is a stated 93% cost difference.
But the cheap number is not the point.
The point is whether the output clears your real task.
A lower token price does not prove a model is right for your work. GoodEnough's own advice is to test on your prompts, inspect the result, and keep the model that meets the need.
So don't ask, "What is the smartest model?"
Ask:
What did this task cost?
Did the answer pass review?
Would I pay the premium again?
Run 100 real prompts. Compare the output and the invoice.
Then let the numbers decide whether your default model has earned its price.

Switching AI providers should not start with a rewrite.
Start with the client you already have.
Point your existing OpenAI client at GoodEnough's base URL.
Select a model.
Run 100 real production prompts.
Measure:
- output quality
- latency
- failures
- input and output tokens
- cost
Only then decide whether the integration deserves changing.
GoodEnough's API is OpenAI-compatible for chat completions, and it supports direct model selection or Auto routing.
The important part is not the promise of a lower token price. It is testing your own work.
A provider switch should be a benchmark first and a rewrite second.
$6.75 in frontier-model cost.
$0.46 with GoodEnough Auto.
Same illustrative workload: 1M input tokens and 250K output tokens.
That is a stated 93% cost difference.
But the cheap number is not the point.
The point is whether the output clears your real task.
A lower token price does not prove a model is right for your work. GoodEnough's own advice is to test on your prompts, inspect the result, and keep the model that meets the need.
So don't ask, "What is the smartest model?"
Ask:
What did this task cost?
Did the answer pass review?
Would I pay the premium again?
Run 100 real prompts. Compare the output and the invoice.
Then let the numbers decide whether your default model has earned its price.

Stop routing every prompt to the flagship.
Let Auto choose:
• GPT-OSS for general chat
• Qwen3 Coder Next for code
• Qwen3 VL for images
Then inspect the `model` field in every response.
That field is your workload audit.
Run 100 real prompts. Count the model mix. Rerun evals by task. Compare output quality and cost.
If most requests do not need the flagship, paying for it by default is not a strategy. It is a tax.
GoodEnough Auto returns the selected model, so you can measure the routing instead of trusting the label.
One model for every request is an expensive habit.
Let Auto route the work:
general chat -> GPT-OSS
code -> Qwen3 Coder Next
images -> Qwen3 VL
GoodEnough's router uses a learned classifier plus deterministic filters. The response includes the `model` field, so you can inspect what actually handled each request.
Run 100 real prompts:
1. Log the model field.
2. Group requests by task.
3. Compare quality and spend.
Auto is listed at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
Stop debating which model wins.
Measure which model your requests actually need.
Coming soon to Good Enough AI! 85% off your AI search bill.
api-docs.deepseek.com/guides…

Everyone is looking at model routing like it is five model choices.
The more interesting part is that it can become one shared decision system.
With an OpenAI-compatible API, your application can send requests to one endpoint. Auto then selects a model for each request and returns which model it chose.
A coding task can go to Qwen3 Coder Next. An image request can go to Qwen3 VL. General chat can go to GPT-OSS.
That turns one API key into a model fleet.
The upside is obvious:
- fewer provider integrations
- fewer model-selection branches in application code
- the option to use function calling and tools through the same interface
- a cost decision made per request instead of per product
The blast radius is just as real:
- your bearer token can reach every model your account exposes
- a routing rule becomes a production dependency, even when it looks like a pricing setting
- tool calls need the same approval boundaries whether the request landed on a cheap model or an expensive one
- rate limits and account credit are separate constraints, so "the API is up" does not mean "the workload can continue"
- if you do not record the selected model and token cost, you cannot explain the invoice or the output mix
The breakthrough is not that you can call several models.
It is that they can look like one provider inside your real application.
That changes the job from choosing a flagship once to designing routing, permissions, fallbacks and measurement.
Do not compare models on a leaderboard and stop there.
Run 100 real prompts through the route you plan to ship. Check which model handled them, what the outputs cost, and where a human approval still belongs.

A $2,000 AI bill can become an estimated $134.62.
GoodEnough's calculator gets there using a 75% input / 25% output mix.
That is a 93.3% difference.
But don't trust the calculator. Trust your workload.
Take 100 production-like prompts:
- support replies
- code changes
- extraction
- long-document questions
- image requests
Run them through Auto. It routes each request to a model, and the response shows which model it selected.
Then compare:
1. Did the answer pass your eval?
2. How many tokens did you use?
3. What would the bill have been at your current rates?
GoodEnough Auto is listed at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
The point isn't that cheaper is always better. GoodEnough explicitly says to test your own work and keep the model that earns its place.
The point is that "we need the flagship" is a claim your 100 prompts can disprove.
Your bill is probably hiding a routing problem.
A $2,000 AI bill can be about $134.62.
Here's the calculation:
75% input / 25% output
Frontier reference:
• $3 per 1M input tokens
• $15 per 1M output tokens
GoodEnough Auto:
• $0.23 per 1M input tokens
• $0.92 per 1M output tokens
Weighted frontier rate:
0.75($3) + 0.25($15) = $6
Weighted Auto rate:
0.75($0.23) + 0.25($0.92) ≈ $0.40
$2,000 × ($0.40 ÷ $6) ≈ $134
The calculator's estimate is $134.62, or 93.3% less. The small difference comes from rounded public rates.
Before accepting your next frontier-model bill, run this calculation on your own input/output mix.
Your workload may be expensive. Your default probably is.
GPT-6 Astra has two prices. Cross 272K input tokens and $10/$50 becomes $20/$75.
Google runs the same split: Gemini 3.1 Pro lists $2/$12 up to 200K tokens, $4/$18 past it.
Context length is a billing axis now. Input doubles at a threshold most teams have never measured their own prompts against.
On every call that crosses the line, half the input charge is the surcharge. Check what share of your traffic is over it before your next model decision.
We'll hand you the eval setup we use to prove quality didn't drop.
Get the eval setup & sign up:
itsgoodenough.ai/?utm_source…

xAI's new flagship bills 2.4x the old one for output. The old one is still on the menu.
Grok 4.5: $2 in, $6 out per million tokens. Grok 4.3, same API, still listed: $1.25 in, $2.50 out.
The version number moved one step. The output rate moved 2.4x.
If 4.5 took your traffic without an eval run, you bought that 2.4x on a badge.
Your AI bill is 70-90% habit.
Cut the cost & sign up:
itsgoodenough.ai/?utm_source…
Strip the extremes and open weights still price 3x under closed.
22 flagship-class models on the Good Enough Index, public list prices, blended 3:1. The median closed flagship: Claude Sonnet 4.6, $6.00 per million tokens. The median open one: DeepSeek V4 Pro, $1.98.
Ceiling-to-floor comparisons get called cherry-picking. This is the middle of one pack vs the middle of the other. 3x.
A 3x gap at the median is a line item, and it's on your bill whether you've measured it or not.
Same evals, 70-90% less.
Keep the quality & sign up:
itsgoodenough.ai/?utm_source…
Two flagships, one sticker: $10 in, $50 out. The sticker is not the cost.
Anthropic's own pricing page says Claude Fable 5's tokenizer counts about 30% more tokens for the same text than its predecessors'. Same document, same rate card, an effectively higher bill.
GPT-6 Astra wears the same $10/$50 on a different tokenizer.
Price per token is a rate; cost per task is what leaves your account. Run one real task through both and read the two bills.
If your AI bill made you wince, that's the whole pitch.
Fix the bill & sign up:
itsgoodenough.ai/?utm_source…