

Live in minutes, Herald investigates novel incidents without runbooks, runs securely from a CLI and is free. Formerly RunLLM. Try now: https://teapaw.org/t.co/jeLOKlB3mX
San Mateo, CA
Joined April 2022
- Tweets576
- Following14
- Followers804
- Likes330




Herald retweeted

Teams want AI to help debug the flood of AI-written code hitting prod.
That demands an always-current understanding across all infra and code.
To make sure those memories aren't lost like tears in rain, they need to rebuild new tribal knowledge.
👉 tinyurl.com/4dwswjf8

Herald retweeted

"We're spending about five figures a month on coding agents. I think it's making the team more productive. I'm not sure. But I think."
That's from a VP of engineering running a team of ~100. It's obvious that coding agents are faster than human engineers, but it's not obvious how you manage your spend.
For decades, the constraint on shipping software was headcount. You had N engineers, you pointed them at the highest-priority work, and you shipped what you shipped.
Today you can spend 2-3x the cost to produce the same software in a tenth of the time. The recent port of Bun from Zig to Rust took 11 days and $165k in API costs. That's obviously a net improvement over what it would have cost to have engineers do it by hand, but choosing to do that requires a new calculus.
Because faster production is not the same as better economics.
The fact that you can generate more code, faster, doesn't mean you should. Every task is now a choice: which model, how much speed, how much accuracy, how much human guidance. Get those parameters wrong and you pay a lot of money to build the wrong thing very fast.
The challenge for engineering teams has always been picking the right things to build. Agents didn't fix that problem — it's faster but just as expensive: open.substack.com/pub/fronti…
Herald retweeted
Despite the fact that no one pays attention to benchmarks anymore, models are improving at a breakneck pace.
As models get better, they will likely dominate the most obvious applications, which means that startups need to focus on problems that are harder to solve or harder to adopt.
Earlier this year, we wrote about how both hard technical problems and hard adoption problems ultimately create the same moat: data.
When you solve hard technical problems, you get more feedback on how those problems should be solved and where the models fail. This is what's made coding agents better so quickly, but the same process can be applied to other, less obvious problems.
When you solve hard adoption problems, you learn how humans fail with your agent. This might be a less obvious moat, but making your product easier to use and adopt in difficult circumstances has huge value.
This 2x2 — technical depth and adoption complexity — helps us understand how businesses drive their growth: open.substack.com/pub/fronti…
Herald retweeted
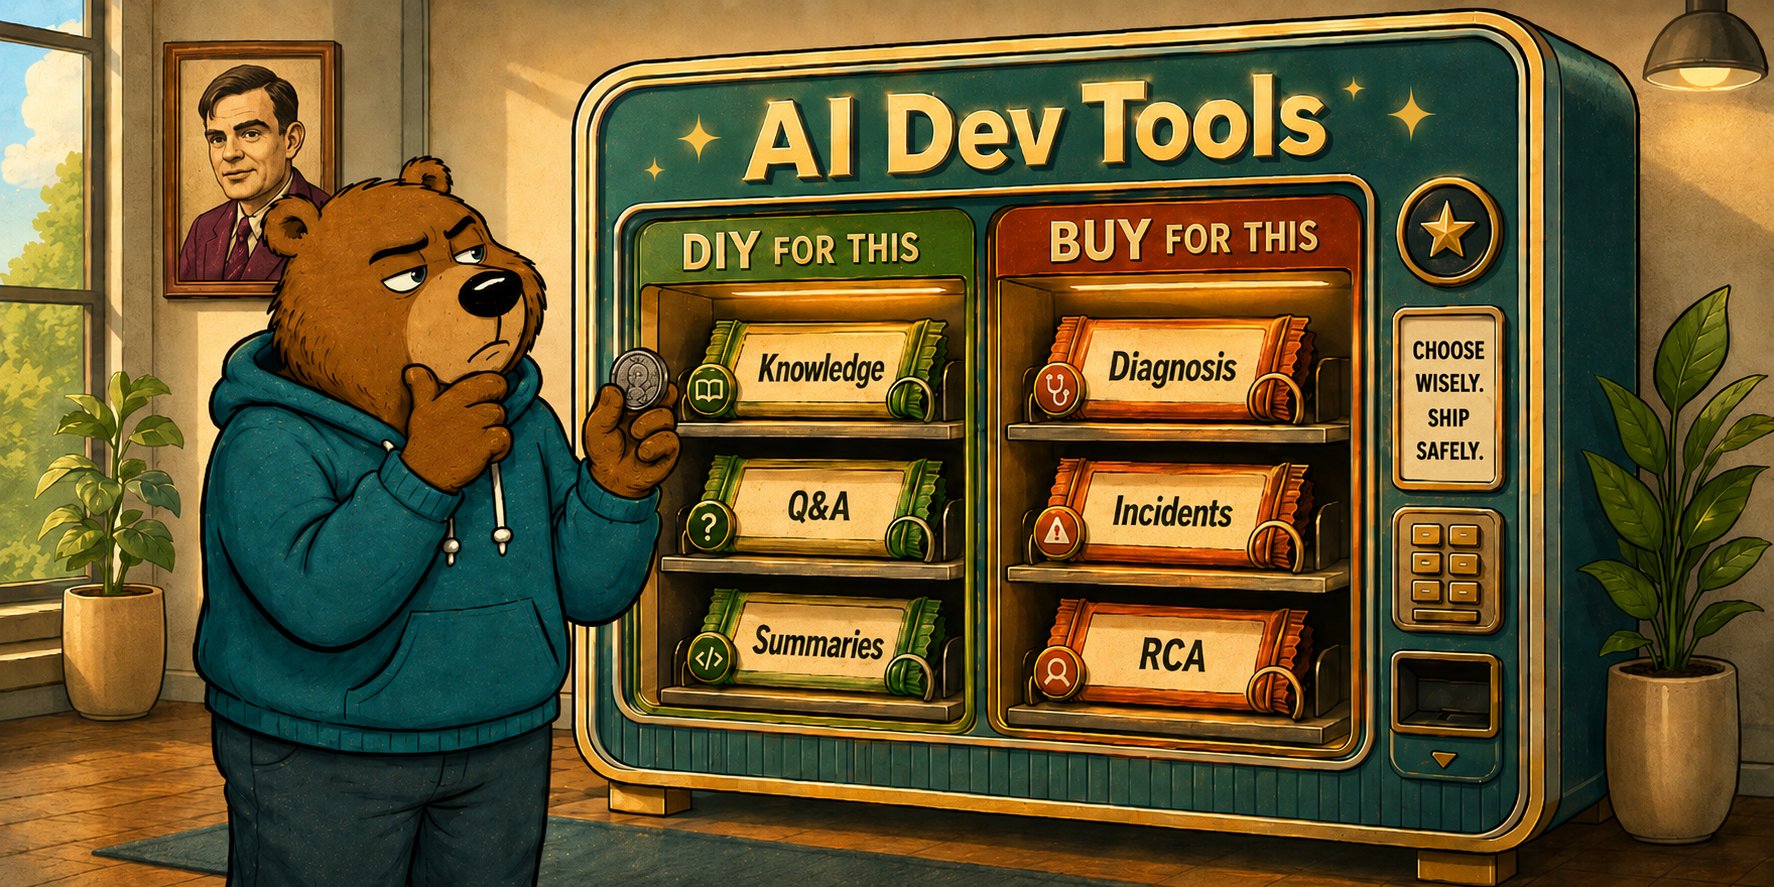
Build vs. Buy is a tension all engineering teams face, and now AI makes it easier than ever to DIY.
So when is building your own dev tool with AI a good use of the team's time, and when is it not?
👉 My thoughts: tinyurl.com/nvt8djzx
🤖 Made with AI
Herald retweeted
Token leaderboards are not a great idea.
Now we're hearing about budget freezes and per-employee token limits.
Both are the same mistake.
Treating AI as one number on the budget is like treating all your salary spend as one number. Nobody does that. A staff engineer and a contractor aren't the same line, and you'd never set one headcount budget and call it strategy.
But that's exactly how most teams are handling AI right now. One bucket. One number to either brag about or panic over.
The value AI adds to shipping a feature that moves your top line is nothing like the value it adds writing cold email copy — or the value it adds when you're burning tokens recreating a tool you could have bought.
Lumping all of that together as "AI spend" is how you end up making bad decisions in both directions: tokenmaxxing to inflate the number, then slamming on the brakes when the bill scares you.
We've watched this play out. We've talked to teams blocked from spending on a tool that would solve a real problem for 1-2 orders of magnitude less than the salaries they're already paying to solve it by hand — because the "AI budget" was frozen.
The worst part is what the freeze kills: experimentation. When you cut that, you're betting the technology around you isn't changing. It is.
AI isn't a line item. It's a set of very different bets, each tied to a different part of your business. Start budgeting it that way: open.substack.com/pub/fronti…
Herald retweeted
Last week, a VP of Engineering told us his team had already built most of what we do.
We'd spent four meetings with the engineers who actually run reliability for him. We knew where their data lived, what systems they used, how they triaged incidents. So we knew the team was working almost entirely by hand — getting paged, spinning up channels, linking tickets manually.
He thought they were further along than they were. We knew more about the state of his org than he did.
This isn't new. Leaders have always been a few steps removed from the work. Enterprises have grown for decades despite that gap. But AI makes the gap expensive in a way it never was before.
Here's why: an agent only creates value when it conforms to how your team actually works. That requires a clear picture of the current state and a real definition of what "good" looks like. If you don't know what good is, an LLM won't tell you — it'll just help you get to the wrong place faster.
The VP was anchored on a demo built on hard-coded workflows and runbooks. It looked impressive. It also wouldn't survive contact with the complexity of his actual stack — a stack he'd partly lost track of. So the risk wasn't that he'd buy nothing. It's that he'd buy something that amplified the disorganization already there.
The fix isn't more diligence from the top. It's trusting the people doing the work to make the call. They're the ones living with the pain. They know what's worth automating and what good looks like, because they're standing in the ground truth every day.
The further you sit from that ground truth, the more likely you are to believe your team is light-years ahead — or behind — where it actually is.
That's the part AI doesn't fix for you: open.substack.com/pub/fronti…
Herald retweeted
Lots of exciting news to share today!
1. @RunLLM is now @Herald_Dev. The new name reflects the fact that our AI SRE is the only product on the market that operates autonomously — teaching itself about your product & infra, detecting early warning signs of incidents, and investigating without runbooks. Read more: herald.dev/blog/heralding-th…
2. Herald was named to the InfraRed 100, an annual list recognizing the most promising private companies defining the future of cloud infrastructure. Thanks to Redpoint for the recognition!
3. We're releasing the beta of the Herald CLI — an agent that runs securely on your laptop and gets up and running in minutes. Sign up for early access here: herald.dev/cli

The Redpoint InfraRed 100 is now live.
These are the companies building the infrastructure that powers everything happening in AI right now, from world models and agent runtimes to the sandboxes, databases, and security tools agents depend on.
Congratulations to this year's honorees!
Read the full 2026 InfraRed Report: our state of the union on AI and cloud infrastructure 👉 redpoint.com/reports/the-inf…

Herald retweeted
Why do on-call engineers often ignore expensive AI tools during incidents? I wrote about what's broken and what it takes to fix it: tinyurl.com/y9e3k93n

Herald retweeted
Finding product-market fit has always been the holy grail for every startup.
In AI, it might not be the "we've made it" moment it once was.
The traditional advice once you find PMF is to operationalize. Codify the ICP. Build the playbooks. Deepen the product. The point is consistency — $N in, $M out.
In AI, consistency is a liability.
Customer preferences are being rebuilt every week. The demo they saw last night is the new benchmark. If that signal takes three weeks to travel from a sales call back to a roadmap decision, you're already behind.
The companies that win aren't going to be the ones that find PMF first.
They're going to be the ones that keep replacing their own product while the market is still figuring itself out: open.substack.com/pub/fronti…
Herald retweeted
If customers had been willing to write us $250K checks on day one, we would have built the wrong product.
With RunLLM, we set out to build the same AI SRE agent everyone else was building: an RCA agent triggered by alerts, driven by customer-maintained runbooks. It was the obvious answer. Humans use runbooks, so the agent should too.
Except alert thresholds are noisy. Nobody actually maintains their runbooks. And the agent inherits every gap.
We didn't figure that out because we were smarter than anyone else. We figured it out because the market gave us time. Enterprise SRE buyers don't move fast. They have committees. They want weeks to evaluate. They ask hard questions about what happens when something breaks at 3am.
That slowness is put us on the right track.
In a fast market, the competitive pressure forces you to ship the obvious solution and iterate from there. You don't get time to ask whether you're solving the right problem — you just have to start solving something. In a slow market, you're forced to keep asking. And for hard problems, the obvious solution is rarely the right one.
The interesting question in AI SRE isn't "how do we automate the runbook." It's "how do we detect early warning signs, validate them, and find root cause before any threshold alert fires?" We didn't get to that question by moving fast.
We got to it because the market wouldn't let us.
I see a lot of founders right now benchmarking themselves against Cursor's growth curve and feeling like something is wrong. For most infrastructure problems worth solving, that curve was never going to apply. And the slowness you're frustrated by is probably the thing that's going to make your product impossible to copy in three years.
Friction is information. Don't optimize it away too early: open.substack.com/pub/fronti…
Herald retweeted
We spent $63 on a single investigation last month.
That number stuck with me, because it's the cleanest illustration I've seen of where AI economics are actually heading.
Per-token costs are plateauing. But per-request token consumption is going up — fast. Every time we add another LLM call to pre-read data, rerank results, or evaluate relevance, the bill goes up. And we keep adding them, because that's how you actually get good answers.
The honest truth: we have a dozen more places we'd love to throw an LLM at the problem. We're held back by cost, latency, and evals — not by ideas.
Most teams are reaching for fine-tuning or RL to fix this. I'd push back. The hard part of post-training isn't the algorithm. It's having the right data in the right shape, and most teams don't.
The boring lever almost no one pulls hard enough: matching model size to task difficulty.
Gating questions, filtering documents, synthesizing logs — none of these need a frontier model. A smaller model handles them fine, at a fraction of the cost. We default to GPT-4.1 Mini for a lot of these, and it's been one of the highest-leverage decisions we've made.
There's no clean rule for when to use what. It's still more art than science. But if you're not actively making that call, you're paying for it.
Wrote more about how we think about managing token demand here: open.substack.com/pub/fronti…
Herald retweeted
Agents can't choose between structure and flexibility.
We learned this the hard way. In the early days of RunLLM, we built the way most AI SRE vendors still build: have customers write runbooks, encode them as workflows, let the agent execute them in response to alerts.
It worked in demos. It fell apart in production.
The moment an alert looked different from anything we'd seen before, the agent was useless. The moment a customer's architecture changed, the runbook was stale. We were shipping a glorified lookup table and calling it an agent.
The instinct is to flip the other way. Let the model figure it out. Give it good context, a capable loop, and get out of the way.
That works until you try to run it at scale. Context windows fill up and something has to decide what to keep. Costs balloon and something has to route cheaper tasks to cheaper models. Multiple agents need to coordinate and something has to orchestrate them. Each of those is an engineering decision that can't be solved by asking the model nicely.
The teams building serious agents have all landed in the same place, independently: structure where it has to be enforced, flexibility where reasoning matters, and a deliberate architecture deciding which is which.
Picking a side is how you avoid doing that work.
New post on the AI Frontier this week on why the Python vs. Markdown debate is the wrong debate: open.substack.com/pub/fronti…
Herald retweeted
A VP of Construction Engineering. That's who our AI-powered SDR was emailing last week.
We're a developer tools company. Construction engineering is not in our ICP. But the agent saw "VP of Construction Engineering" and decided it was close enough to "VP of Engineering."
A human would catch that instantly. The agent couldn't, because it was built the way most agents are built today: take a human workflow, write down the steps, and hand each one to an LLM.
That works when everything fits the expected pattern. It falls apart the moment anything requires judgment.
I keep seeing the same mistake across the industry. Agents that try to generate a finished slide deck from a prompt. Agents that try to write and send entire email sequences autonomously. Agents that present themselves as replacements for the human rather than tools that make the human better.
The best agent products I've used don't work that way. They keep the scope narrow, the feedback loops fast, and the human in the loop on the decisions that require taste.
When the cost of generating work is zero, taste is what stands out. The agents that win are the ones designed to let humans apply it.
We wrote about this — and what we think "agent-native" actually means — in the first post of our new series: frontierai.substack.com/p/bu…
Herald retweeted
Ask Claude to build you a financial model in Excel.
You'll get back reasonable structure, plausible assumptions, formulas that link together correctly.
Now you have to check it.
Do you open every cell and inspect every formula? If you do that, you might as well have built it yourself. If you don't, you're trusting a junior employee who works at superhuman speed but might have encoded some very strange assumptions that didn't stand out at first glance.
Validating agent-generated work is the problem nobody is talking about.
Agents have made creation cheap. They haven't made it any easier to know whether what was created is actually right.
The bottleneck used to be writing the code, building the model, drafting the document. Now it's checking the output. And our tools — spreadsheets, code review, document editors — were all designed for a world where humans did the creating. None of them are built for the volume or the speed agents produce at.
@profjoeyg and I wrote about this, and what we think validation actually has to look like going forward: open.substack.com/pub/fronti…
Herald retweeted
AI agents shouldn't have a job title.
The entire AI industry is racing to build "AI SDRs," "AI SREs," and "AI SOC analysts." You can't walk through SF without seeing a billboard for one.
We get why — customers search for these terms, and if your site doesn't speak their language, you lose the SEO battle before you make your pitch.
But here's the problem: when you name your agent after a job title, you're promising it can do everything that person does. Including the stuff that never made it into the job description.
The result is mismatched expectations, eroded trust, and products that underdeliver on their own marketing.
Meanwhile, the agent category with the deepest adoption, the strongest data flywheels, and the most widespread quality? Coding agents. And none of them called themselves an "AI software engineer."
That's not a coincidence.
The full post explains why job title thinking constrains what an agent can actually do: open.substack.com/pub/fronti…
Herald retweeted
We all know we live in the AI bubble, but the bubble is smaller than you might think.
Even at some of the most innovative companies in the world, AI adoption is a big hurdle.
Right now, you might be tempted to focus on the people who are excited to adopt — but that might not be a sustainable long-term strategy.
Here's why you're going to have to break out of the bubble 👇
Herald retweeted
The idea that a startup will build an agent to help understand all your enterprise data is really appealing — unfortunately, it's incredibly difficult to defend.
Enterprises have data everywhere, and a single front door that helps you find and analyze what you need at the right time is the holy grail. With LLMs, many startups are promising this future.
The reality, however, is that these products are indefensible. The frontier model labs are desperately competing for enterprise attention, and they have all the advantages.
The full post breaks down why 👇
Herald retweeted
Predicting the doom of SaaS companies is all the rage right now, but... are they actually going to die? Maybe!
Some SaaS companies are very likely to be disrupted. Others have more defensibility.
Where do you fall on the spectrum? @profjoeyg and I put together a SaaS extinction test 👇
Herald retweeted
Engineering leaders are staring at spreadsheets of AI agents, each claiming a 90% score on a different benchmark. But if they’re so good on paper, why do they fail in your actual codebase?
Benchmarks measure SAT scores — but agents require on-the-job competency. A sterile, zero-shot score tells you nothing about how an AI handles your specific legacy debt or infrastructure quirks.
Next time a vendor shows you a leaderboard, ignore it. Hand them your last outage report instead and ask: How would your agent have helped us here?
Hire the specialist for your stack, not the smartest generalist.
Herald retweeted
Your agents should be doing lots of useless work because it maximizes the chances that one of the things that it does is the right thing.
This is the opposite of how people work today, but we're already seeing coding agents let people try lots of things and pick what works.
That changes the economics of work — a single task is no longer that expensive or valuable — and those economics are going to extend into the way agent work.
@profjoeyg and I break it down 👇