

3rd-year PhD Candidate @sjtu1896 AI for Sports
Shanghai
Joined July 2017
- Tweets56
- Following117
- Followers35
- Likes143







Pinned Tweet
MatchMate⚽️
An AI football companion product for live game watching: ask questions, check data, and get personalized commentary and interactions in real time.
Born from our AI sports research, now in beta!
Try here👉matchmate.tv
#FootballAI #SportsTech #WorldCup2026
🤖 Made with AI


How it compared with SoccerMaster+MatchMate 🤔

between today and yesterday, we launched two amazing new capabilities: Gemini 3.8 Flash and Agentic Video Understanding and they have been so much fun to build with.
to test their limits, I built a retro Windows 98-themed workstation where you can drop in any YouTube URL of full 2-hour soccer matches 💾 ⚽(or any sports broadcast) & ask super detailed questions like "show me all the 🟨 yellow cards & bookings"
⚡ Agentic Video Understanding autonomously navigates across the 120-minute video timeline (no giant downloads or blind frame sampling)
🔍 dynamically zooms into candidate segments to detect referee whistles, tackles & card gestures
📍 isolates every card with exact sub-second timestamps & 2D pitch coordinates
🎬 pops out a tactical ledger where clicking any row instantly seeks and plays live!
no manual scrubbing. pure interactive video intelligence.
1
48
🏀 Can AI truly understand who did what, and when in a basketball game?
Introducing BasketEvent+PlayNet: player-centric basketball understanding of real NBA broadcasts, a new work with @WeidiXie.
🎥 Demo attached. Paper, code&data are now open-source.
🌐 zhangyu2003.github.io/Basket…
Jiayuan Rao retweeted
🌎🇨🇻 OFFICIAL: Vozinha wins FIFA Man of the Match Award for Spain-Cape Verde. 👏🏼

Come and see our work with @WeidiXie !!! As FIFA World Cup is coming, our SoccerMaster meets the CVPR award candidate🎉

⚽️ Introducing the first vision foundation model for this beautiful game.
🌟 CVPR 2026 Oral & Award Candidate (with @WeidiXie )
⏰ Oral: June 6, 14:00 (Four Seasons Ballroom)
📍 Poster: June 6, 16:45 (#11)
📑 SoccerMaster: A Vision Foundation Model for Soccer Understanding

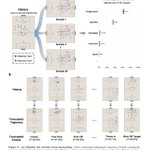
Football tactics are not with a single future, In GenTac, we treat open-play as a generative multi-agent process, unifying:
⚽ multi-player trajectory forecasting
📍 tactical event recognition
Project Page: jyrao.github.io/GenTac/
Github: github.com/jyrao/GenTac
@WeidiXie


Fig. 4 | trajectories carry semantics
On TacBench-Event with 5 event types and 15 subtypes, GenTac can recover tactical semantics directly from multi-player trajectories.
Event grounding reaches:
71.2% top-1 for event type
53.7% top-1 for event subtype
with strong top-3/5 Acc.

2
33
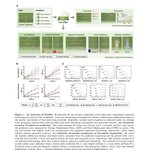
Fig. 3 | beyond soccer
We also retrain GenTac on basketball, American football, and ice hockey. Across all three, opponent-conditioned forecasting consistently outperforms unconditioned rollout.

2
40
Fig. 2 | conditioned forecasting
GenTac is also about generating futures under different conditions: team /league style and objectives.
Team conditioning improves collective structure at 5s. Objective guidance also makes the rollout steerable toward offense or defense.


2
48
Welcome to join our Challenges at CVPR 2026!!! See all the details here and I'm hosting VQA challenges with $1000 prize for No.1 candidate sponsored by KNQ technology.

The SoccerNet 2026 Challenges are in full swing⚽️🔥
Our presentation video is now live : meet the task leaders and don't miss any details before the April 24, 2026 deadline.
▶️Watch it here: youtu.be/TjX789boQGM
Time to climb the leaderboard 🚀
@_CVsports #CVPR2026
Jiayuan Rao retweeted

(1/n) 🚨 BERTs that chat: turn any BERT into a chatbot with diffusion
hi @karpathy, we just trained a few BERTs to chat with diffusion — we are releasing all the model checkpoints, training curves, and recipes! Hopefully this spares you the side quest into training nanochat with diffusion for now 🙂. It’s both a hands-on tutorial for beginners and an example showing how to use our complete toolkit (dLLM) for deeper projects.
Code: github.com/ZHZisZZ/dllm
Report: api.wandb.ai/links/asap-zzho…
Checkpoints: huggingface.co/collections/d…
Motivation: I couldn’t find a good “Hello World” example for training a minimally working yet useful diffusion language models, a class of bidirectional language models capable of parallel token generation in arbitrary order. So I tried finetuning BERTs to make it chat with discrete diffusion—and it turned out more fun than I expected.
TLDR: With a small amount of open-source instruction-following data, a standard BERT can gain conversational ability with diffusion. Specifically, a finetuned ModernBERT-large, with a similar number of parameters, performs close to Qwen1.5-0.5B.

Nice, short post illustrating how simple text (discrete) diffusion can be.
Diffusion (i.e. parallel, iterated denoising, top) is the pervasive generative paradigm in image/video, but autoregression (i.e. go left to right bottom) is the dominant paradigm in text. For audio I've seen a bit of both.
A lot of diffusion papers look a bit dense but if you strip the mathematical formalism, you end up with simple baseline algorithms, e.g. something a lot closer to flow matching in continuous, or something like this in discrete. It's your vanilla transformer but with bi-directional attention, where you iteratively re-sample and re-mask all tokens in your "tokens canvas" based on a noise schedule until you get the final sample at the last step. (Bi-directional attention is a lot more powerful, and you get a lot stronger autoregressive language models if you train with it, unfortunately it makes training a lot more expensive because now you can't parallelize across sequence dim).
So autoregression is doing an `.append(token)` to the tokens canvas while only attending backwards, while diffusion is refreshing the entire token canvas with a `.setitem(idx, token)` while attending bidirectionally. Human thought naively feels a bit more like autoregression but it's hard to say that there aren't more diffusion-like components in some latent space of thought. It feels quite possible that you can further interpolate between them, or generalize them further. And it's a component of the LLM stack that still feels a bit fungible.
Now I must resist the urge to side quest into training nanochat with diffusion.
“Multi-agent System for Comprehensive Soccer Understanding” done with @WeidiXie will be oral presented #ACMMM2025 in Dublin at GoldSmith3, RDCC from around 14:20 tommorrow (10.30).
Come and chat if you are interested!⚽️🏆Also, join our challenge on CVPR 2026 based on this work!


Join our challenge @CVPR 2026! ⚽️⚽️🏆🏆 For $1,000 Prize with Soccer VQA task!
🚀🌟We're excited to kick off the third official task of #SoccerNet Challenges 2026!
⚽️3⃣ VQA Visual Question Answering
Details of this task are available at soccer-net.org/challenges/20…

In ACM MM 2025, we introduced "Multi-Agent System for Comprehensive Soccer Understanding" with @WeidiXie
⚽️AI with external knowledge to analyze on/off-field dynamics! 🧐
📄: arxiv.org/abs/2505.03735
🌐: jyrao.github.io/SoccerAgent/
See details below! #AI4Sports #MultiAgent #ACMMM25


ii) Also, we designed a multi-agent system, SoccerAgent, to decompose the the given multi-modal soccer-related questions with tool chains and then execute the tools step by step with the help of a distributed toolbox.


31
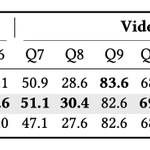
i) We proposed a multi-modal soccer understanding QA benchmark with multiple choices based on WikiPedia and other existing datasets. Some representative examples for each task are presented for reference.


37

