
PhD candidate @ Tel Aviv University. AI research scientist @ ibm research. Interested in deep learning and algorithms.
Joined January 2017
- Tweets168
- Following561
- Followers783
- Likes3.2K




Pinned Tweet
📄🚨 New!
Tired of waiting minutes for LLMs to "think"?
Test-time scaling (O3, DeepSeek-R1) lets LLMs reason before answering — but users are left clueless, with no progress or control.
Not anymore!
We expose the LLM’s internal 🕰️, and show how to monitor 📊 & overclock it⚡
🧵👇

Itamar Zimerman retweeted

Give a VLM a few demos as text: ~100% accuracy.
As images, with no task hint: 45%.
VLMs don’t learn from what they see in context. We teach them to watch and learn 🧵
Paper: arxiv.org/abs/2610.30913
Dataset: huggingface.co/datasets/Nimr…

A really clever architecture for diffusion-based speculative decoding!
Huge kudos to @roy_eisenstadt and @IlanNaiman for driving this from start to finish with remarkable initiative and ownership - Impressive work!
Proud to be part of this team! 👏

Itamar Zimerman retweeted

1/7 🥥 New speculative decoding method!
Introducing DCOCO: Contextual Correction of Parallel Drafts.
Parallel drafters are fast, but lose context between predicted tokens.
DCOCO restores it without giving up parallelism.
Up to 6.6× faster than vanilla decoding. 🧵
Itamar Zimerman retweeted

(1/9) 🐍 Mamba Recall Scaling Laws: accepted to #NeurIPS2026! 🎉
How many facts can Mamba actually store and recall?
By reverse-engineering Mamba models, we reveal an interpretable hash-based recall mechanism, and theoretically derive precise scaling laws - predicting recall accuracy directly from model dimensions. Here's the story. 🧵👇
📄 Paper: arxiv.org/abs/2609.07681
💻 Code: github.com/yuvalko1/mamba-re…

Itamar Zimerman retweeted

Information flow in auto regressive LLMs is mostly bottom-up - except for a single decoded token.
Allowing information from deep layers to propagate to the next step as a latent state is attractive, but hard to train due to the implied recurrence.
In our recent preprint @TiroshDor does so efficiently! by finding that existing LLMs can be used to teacher-force the latent state, allowing parallel training and a stationary distribution for the states.
The result is LIFT, a Transformer LLM that carries a states from deep-to-shallow layers. LIFT outperform the baselines in all settings considered under a token-matched budget and is on-par or ahead under matched compute.
Happy to be part of this project with the great @megamor2 and @TiroshDor !
Paper: arxiv.org/abs/2609.38149


New preprint: 🔥 Latent Information Feedback Transformers (LIFT) 🔥
Information in LM generation propagates downward (high to low layers) only through the decoded token, creating a bottleneck. Removing it via state propagation makes the model recurrent, which is not scalable for training.
Can we teach LMs to propagate state while keeping pretraining fully parallel? YES!
LIFT is a Transformer-based architecture + teacher-supervised training approach that enables Transformer LMs to exploit deep-to-shallow feedback, while keeping training parallel.
LIFT models consistently outperform standard Transformers and baselines on language modeling, downstream reasoning tasks, and procedural tasks under a token-matched budget, while being on par with or ahead of compute-matched Transformers. LIFT also outperforms Transformers trained on 8x more data on a state-tracking task, even when trained with the states of a Transformer that fails it!
Work by the amazing @TiroshDor and @AmosaurusRex
Paper: arxiv.org/abs/2609.38149
Detailed post + visualizations + code + models coming soon!

Itamar Zimerman retweeted

(1/7) Humans can acquire many capabilities without (catastrophically) forgetting previous ones. Why can't neural networks do the same?
Local Support Learning (LSL) takes us a step closer towards this goal.
In LLMs of up to 7B parameters, LSL augments gradient-based training to retain prior capabilities while learning new tasks at full capacity. Notably, it does so without access to prior data.
Key idea: casting forgetting as a geometric problem, and optimizing for the worst case.
Paper: arxiv.org/abs/2610.02126
Website and code: assafbk.github.io/lsl
SwitchSD improves LLM speculative decoding by using a lightweight signal from the LLM’s internal representations to predict when to copy from context vs. when to use a drafter 🚀
A fun intersection of interpretability and acceleration!
Congrats to @roy_eisenstadt and the team! 🎊
1/10 Accepted to #NeurIPS2026! 🎉
Can an LLM tell us when to copy instead of running a neural drafter?
We introduce SwitchSD: speculative decoding that uses the target model’s hidden states to switch between neural drafting and context copying. Here’s the story.

Itamar Zimerman retweeted
1/10 Accepted to #NeurIPS2026! 🎉
Can an LLM tell us when to copy instead of running a neural drafter?
We introduce SwitchSD: speculative decoding that uses the target model’s hidden states to switch between neural drafting and context copying. Here’s the story.
Itamar Zimerman retweeted
I'll present CLIMP - The first fully mamba based CLIP on #ECCV2026 Friday, Sep 11, 10:30 AM – 12:30 PM, poster session 3, ExHall - poster # 65.
Come and check out how switching CLIP towers to mamba can do magic!
@RGiryes @Eli_Schwartz @ItamarZimerman

Happy to share CLIMP was accepted to ECCV 2026!
@eccvconf #ECCV2026
Check out our work if you want to see how Mamba models meet CLIP!
@ItamarZimerman @Eli_Schwartz @RGiryes
teapaw.org/NimrodShabtay/status/2…
Itamar Zimerman retweeted
Happy to share CLIMP was accepted to ECCV 2026!
@eccvconf #ECCV2026
Check out our work if you want to see how Mamba models meet CLIP!
@ItamarZimerman @Eli_Schwartz @RGiryes
teapaw.org/NimrodShabtay/status/2…
Excited to share CLIMP - the first fully Mamba-based contrastive vision-language model. Unlike CLIP's ViTs, Mamba's state-space formulation favors locality & smoothness—better retrieval and OOD robustness.
with @ItamarZimerman, @Eli_Schwartz and @RGiryes
arxiv.org/abs/2601.06891
Itamar Zimerman retweeted

🎉 Happy to share our latest work: Bootstrap Your Generator: Unpaired Visual Editing with Flow Matching (accepted to #ICML2026)!
TL;DR: We train image and video editing models without any paired data.
No ground-truth edit data, no external reward models.
Do LLM explanations truly reflect their internal rationale?
In our recent ACL paper, we introduce a framework to measure explanation reliability using counterfactuals, and propose Faithfulness Serum💉- a method that enables LLMs to produce faithful explanations!
Details in 🧵👇

📄 🚨
You ask an LLM why it generated an answer.
It gives you a clean, confident explanation.
The problem is
it’s often not the real reason.
We measure this gap, then close it with Faithfulness Serum.
Accepted to the #ACL2026 main conference
📄 arxiv.org/abs/2604.14325
1/6 🧵

Thrilled to share that two interpretability papers were accepted to the main track of ACL! 🔍🚀
Grateful to work with such a great team!
#ACL2026

Wow! An AI system that robustly accelerates NVIDIA's cuGraph is impressive. The combination of low-level GPU engineering and complex graph algorithms is uniquely hard and irregular, which is exactly the kind of setting where most current AI systems still don't generalize well.

An amazing achievement by our team at doubleAI.
GPU kernel optimization is profoundly impactful but notoriously hard, only a handful of human experts can actually do it well. Existing AI systems are not there – the reasoning required to optimize GPU kernels is too deep.
Our AI system WarpSpeed – built on our techniques for deep search and verification – is at a different league, solving one of the hardest GPU optimization domains. This is not “yet another AI winning a toy benchmark”, but an AI comprehensively surpassing human experts on a task that top experts worked and refined for a decade.
Take a look at our blog about it:
doubleai.com/research/double…
More is coming soon...

Itamar Zimerman retweeted
Can LLMs reason internally while processing their inputs, similar to how humans can think ahead as we process information? Our latest work introduces Thinking States, a novel architectural adaptation that transforms reasoning into a internal recurrent process.
By training models to maintain a dynamic thinking state, we achieve significant inference speedups over Chain-of-Thought while substantially outperforming existing latent reasoning methods.
Paper: arxiv.org/abs/2602.08332

Itamar Zimerman retweeted

Still using SAEs?
It's time to move on from dictionary learning to✨local geometry✨
teapaw.org/OrShafran/status/20194…
@OrShafran Shaked Ronen @OmriFahn @ravfogel @atticus_geiger

Thanks for sharing @_akhaliq!
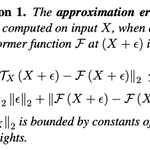
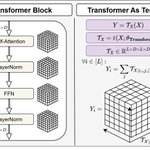
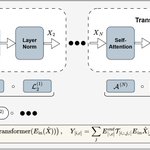
TensorLens provides a theoretically grounded aggregation of attention maps and Transformer components, lifting fragmented matrices to high-order attention tensors that capture end-to-end behavior.
Excited to see what the community does with it!

TensorLens
End-to-End Transformer Analysis via High-Order Attention Tensors
huggingface.co/papers/2601.1…

22
2,269
📜🚨
Introducing TensorLens! 🔎
Our new tool for Transformer & LLM interpretability.
The problem: attention matrices are (i) a shallow view that ignores embeddings, FFNs, and values, and (ii) there are too numerous (per head & layer), which quickly becomes overwhelming.
🧵 1/6

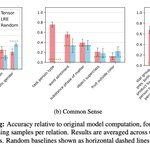
As a concrete application, TensorLens achieves SoTA in linear relation decoding! 📊
We obtain an operator by simply averaging the input-dependent tensors across prompts of the same relation. We think this is just the start! More opportunities for interpretability ahead! 🔎🚀
5/6

Really fun work led by Ido Atad, with Shahar Katz @KatzShachar and Lior Wolf @liorwolf.
📰 Paper: arxiv.org/pdf/2601.17958
💻 Code: github.com/idoatad/TensorLen…
6/6