

Dad. Husband. Founder. Developer. Building @MuraTalkApp and some other things. TensorFold contributor. DGX Spark + 48GB M5 Pro. Ngunnawal land 🌏 Views my own.
Canberra, Australia
Joined October 2026
- Tweets1.5K
- Following385
- Followers315
- Likes1.5K




Pinned Tweet
Told you there was more to it 👀
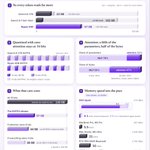
Ripple 65B on TensorFold: from 4.1 tok/s to 124 tok/s on a single DGX Spark
Reading the weights is the expensive part. Every token reads about 56 GB, about 0.24 s a read, so a single stream gets one token per read: 4.1 tok/s. But anything that rides on that same read is nearly free. Checking 16 positions takes 253 ms against 244 ms for 1.
So a small drafter guesses ahead and Ripple checks every guess in one read, giving several tokens a round instead of 1. That took it to 24 tok/s.
Running 8 streams in the same read, with one drafting block shared between them, each stream got about 2 tokens a round: 49 tok/s.
Then I gave each stream its own drafting block. Reading 8 streams × 16 positions takes only 415 ms, and each stream now gets about 7 tokens a round instead of 2. That's 124 tok/s across 8 streams (15.5 each), greedy code, 32k context each.
Submitted as two TensorFold PRs, pending merge 🙌


Ripple-65B Preview is a big dense model. No experts to skip, so every token reads the whole thing.
80 layers, 12T training tokens, 1M context, and 80.5 on Terminal-Bench 2.1 (publisher's score).
In my evaluations it outscored Qwen3.8 27B and Flash-Next, 58/75 vs 48 and 47, with the biggest gap on the coding tasks: 8/15 vs 0/15 for both Qwen models.
The NVFP4 release is conservatively quantised. The MLPs drop to 4 bits but attention stays at 16, so it's 57 GB and fits on one DGX Spark with room to run.
Against the publisher's model code run in float64, it gets 98.7% top-1 agreement and a mean KL of 0.0007.
At the Spark's memory bandwidth of 273 GB/s, reading roughly 56 GB a token caps you near 4.9 tok/s. I measured 4.1.
Not so long ago, that was the end of the story. But there's more to it 👀

3
5
587


Qwen 4 Max preview is out!
It’s actually happening!
What will you build first?

Qwen4 is coming.
Deeper knowledge. Richer world understanding. Stronger coding and agentic capabilities.
Built for real-world tasks — from complex coding and knowledge work to front-end builds and professional software workflows.
Qwen4-Max is now in preview on Alibaba’s Token Plan. You can also get early access to the new model on QwenWork, Qoder, Qwen APP, and QwenStudio.
Put it to the test on a real problem. Show us what you build. 👀
Token Plan: qwencloud.com/pricing/token-…

1
141
Is local AI X going to be super quiet next week because everyone is playing GTA6?
What if Qwen 4 drops on the same day? 👀

156
BREAKING
Anthropic announces ALL Claude users get one banked reset.
This is in addition to the fable resets announced yesterday.
Good stuff from the New Reset Company. @ClaudeDevs

We've given all Pro, Max, Ultra, and Team users one free full reset, across all models and limits. Use it anytime before December 10 at 2:00PM PT.
We recently fixed a few small issues that used more limits than intended, and the Fable resets didn't do much for those of you who'd already hit your weekly limits for all models. While these issues didn't affect everyone, we want to make up for the trouble.
You'll find it in Settings > Usage, or at clau.de/reset.
66
Good morning from beautiful Canberra, Australia.
What are you building today?
#BuildInPublic
3
3
211
Ripple-65B Preview is a big dense model. No experts to skip, so every token reads the whole thing.
80 layers, 12T training tokens, 1M context, and 80.5 on Terminal-Bench 2.1 (publisher's score).
In my evaluations it outscored Qwen3.8 27B and Flash-Next, 58/75 vs 48 and 47, with the biggest gap on the coding tasks: 8/15 vs 0/15 for both Qwen models.
The NVFP4 release is conservatively quantised. The MLPs drop to 4 bits but attention stays at 16, so it's 57 GB and fits on one DGX Spark with room to run.
Against the publisher's model code run in float64, it gets 98.7% top-1 agreement and a mean KL of 0.0007.
At the Spark's memory bandwidth of 273 GB/s, reading roughly 56 GB a token caps you near 4.9 tok/s. I measured 4.1.
Not so long ago, that was the end of the story. But there's more to it 👀

Omg thank you everyone we made it!! 😍😍😍

Can you help me reach 300 followers?
Just over two weeks ago I started posting into the void on this account. In that short time, I'm feeling incredibly humbled to have been followed by nearly 300 amazing humans on this platform. I hope my contributions have been valuable too.
I'm inspired and want to keep the momentum going.
If you're building with:
- Local AI on a DGX Spark
- Open models
- Fast LLM inference on CUDA
- Swift and SwiftUI
- On-device AI for iPhone
- Python
Let's connect 🤝 What are you working on?

2
98
The iPhone Duo starts to make a lot more sense when you realise the real device is the inner display.


2
3
209
Can you help me reach 300 followers?
Just over two weeks ago I started posting into the void on this account. In that short time, I'm feeling incredibly humbled to have been followed by nearly 300 amazing humans on this platform. I hope my contributions have been valuable too.
I'm inspired and want to keep the momentum going.
If you're building with:
- Local AI on a DGX Spark
- Open models
- Fast LLM inference on CUDA
- Swift and SwiftUI
- On-device AI for iPhone
- Python
Let's connect 🤝 What are you working on?
Claude Fable 5.2 is officially the strongest model ever released on the Artificial Analysis Intelligence Index, with a score of 65 at max effort.

84
BREAKING
Along with today’s announcement of Fable 5.2, Anthropic has given select Claude users one or more “Fable resets”.
Here’s how they work👇
• Max, Ultra and Team Premium plans get at least one Fable Reset each
• For those who have subscribed for more than 6 months, it increases to two.
• For those who have subscribed for at least 12 months, it increases to three.
Fable resets do two things:
• Removes all FABLE usage from your weekly usage meter.
• Resets your 5 hour usage, INCLUDING non-Fable usage.
Fable resets do NOT:
•Reset non-Fable usage for the weekly meter.
• Change the day or time of your regular weekly reset.
The Fable Resets are available to use until 9 March.
Use them wisely, and enjoy!
What are you going to build with Fable 5.2? 🚀🚀🚀

1
1
141

Claude Fable 5.2 is out!
A huge step forward in frontier intelligence!
Have you tried it out yet?!
🚀🚀🚀

Fable 5.2 and Mythos 5.2 are a step above Opus 5.5 in almost all the capabilities we evaluated.
Testers have found that they communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Fable 5.1 and Mythos 5.1.

1
2
97