
Member of Technical Staff, MAI. MAI Image generation model 2.5/2.6. Ex research scientist @ Bytedance, Amazon AGI.
Mountain View, CA
Joined April 2018
- Tweets372
- Following959
- Followers459
- Likes1.4K



Pinned Tweet
Over the past few months at Microsoft, I've had the opportunity to work with an incredible team on bringing this image generation model to life. Grateful to everyone involved. Looking forward to what's next. 🚀

MAI-Image-2.6 by @MicrosoftAI has landed in the Text-to-Image Arena at #2 (1336 pts)!
This release is just 45 pts behind GPT Image 2 (Medium) at #1, and ahead of #3 Grok Imagine Image 2.0 (Low) by 20 pts.
MAI-Image-2.6 is a significant improvement from MAI-Image-2.5 overall at #10 with (1256 pts), and across all categories. MAI will also be making it available on Playground with early API access on Foundry next week. See post below for more details.
Congrats to the @MicrosoftAI team on this release!

1
19
32,332
Jacob Fang retweeted

MAI-Image-2.6 by @MicrosoftAI has landed in the Text-to-Image Arena at #2 (1336 pts)!
This release is just 45 pts behind GPT Image 2 (Medium) at #1, and ahead of #3 Grok Imagine Image 2.0 (Low) by 20 pts.
MAI-Image-2.6 is a significant improvement from MAI-Image-2.5 overall at #10 with (1256 pts), and across all categories. MAI will also be making it available on Playground with early API access on Foundry next week. See post below for more details.
Congrats to the @MicrosoftAI team on this release!
Jacob Fang retweeted
As @satyanadella says, we're making great progress on shipping MAI models that are higher quality, faster and cheaper across MSFT.
In PowerPoint, our image model cut costs 84% compared with GPT-Image-2.
In OneDrive, it lifted save rates 26% and cut latency by ~25%. It's also the default model in Bing delivering great quality and performance.
In Dragon Copilot, our transcription model now covers 58 languages and halves the error rate on multilingual clinical transcription.
And of course the flights we have in motion on GitHub and Excel will no doubt be huge too!
More details in the blog here: microsoft.ai/news/introducin…


Jacob Fang retweeted

Congratulations and thank you to the team! This is our first image editing model developed from scratch in only a couple of months with very few people! Great work!!
MAI-Image-2.5 has officially released from @MicrosoftAI landing at #2 in the Image Edit Arena (Single-Image-Edit) with a score of 1401 and advances the Pareto frontier!
This puts the model +10 pts over Nano Banana 2, Grok Imagine Image Quality and ChatGPT-Image-Latest-High Fidelity.
Congrats to the @MicrosoftAI team on this big accomplishment!

Jacob Fang retweeted

🚨🚨We are hosting "Frontier Topics in Generative AI" Seminar Series at @ASU .
This series delves into the cutting-edge of GenAI, exploring key areas like large-language models, text-to-image, video generation, and more.
We have our first speaker this week.
Jacob Fang retweeted

ByteDance announces Diffusion Model with Perceptual Loss
paper page: huggingface.co/papers/2401.0…
Diffusion models trained with mean squared error loss tend to generate unrealistic samples. Current state-of-the-art models rely on classifier-free guidance to improve sample quality, yet its surprising effectiveness is not fully understood. In this paper, We show that the effectiveness of classifier-free guidance partly originates from it being a form of implicit perceptual guidance. As a result, we can directly incorporate perceptual loss in diffusion training to improve sample quality. Since the score matching objective used in diffusion training strongly resembles the denoising autoencoder objective used in unsupervised training of perceptual networks, the diffusion model itself is a perceptual network and can be used to generate meaningful perceptual loss. We propose a novel self-perceptual objective that results in diffusion models capable of generating more realistic samples. For conditional generation, our method only improves sample quality without entanglement with the conditional input and therefore does not sacrifice sample diversity. Our method can also improve sample quality for unconditional generation, which was not possible with classifier-free guidance before.

Jacob Fang retweeted

Adversarial learning
+ Bayesian CNNs = ⬆️single-source domain generalization tasks.
Joint work with Sheng Cheng, @trgokhale, and from @ApgAsu
ArXiv: arxiv.org/abs/2307.09520
To 📢 @ICCVConference
PS: I still think this paper could be with just three sentences... 🤠

Jacob Fang retweeted

🎓 Defended my thesis today!
🌟 Big shout out to my advisor Dr. Hanghang Tong, and my thesis committee: Dr. Jiawei Han, Dr. Ross Maciejewski and Dr. Han Zhao (@hanzhao_ml)!
🙌 Thank you all to my friends, collaborators and family who supported me in this journey.

Jacob Fang retweeted

1. arxiv.org/abs/2306.00424. We introduce a new multimodal-query retrieval benchmark with an end-to-end multimodal retriever, ReMuQ dataset is available online: github.com/luomancs/ReMuQ. It is a collaboration with @Jacob292020 @trgokhale @Yezhou_Yang @chittabaral
Jacob Fang retweeted

🎉Thrilled to share that our paper "World-to-Words: Grounded Open Vocabulary Acquisition through Fast Mapping in Vision-Language Models" was selected for the outstanding paper award at #ACL2023NLP! Thanks @aclmeeting :-)
Let's take grounding seriously in VLMs because...
🧵[1/n]

Jacob Fang retweeted
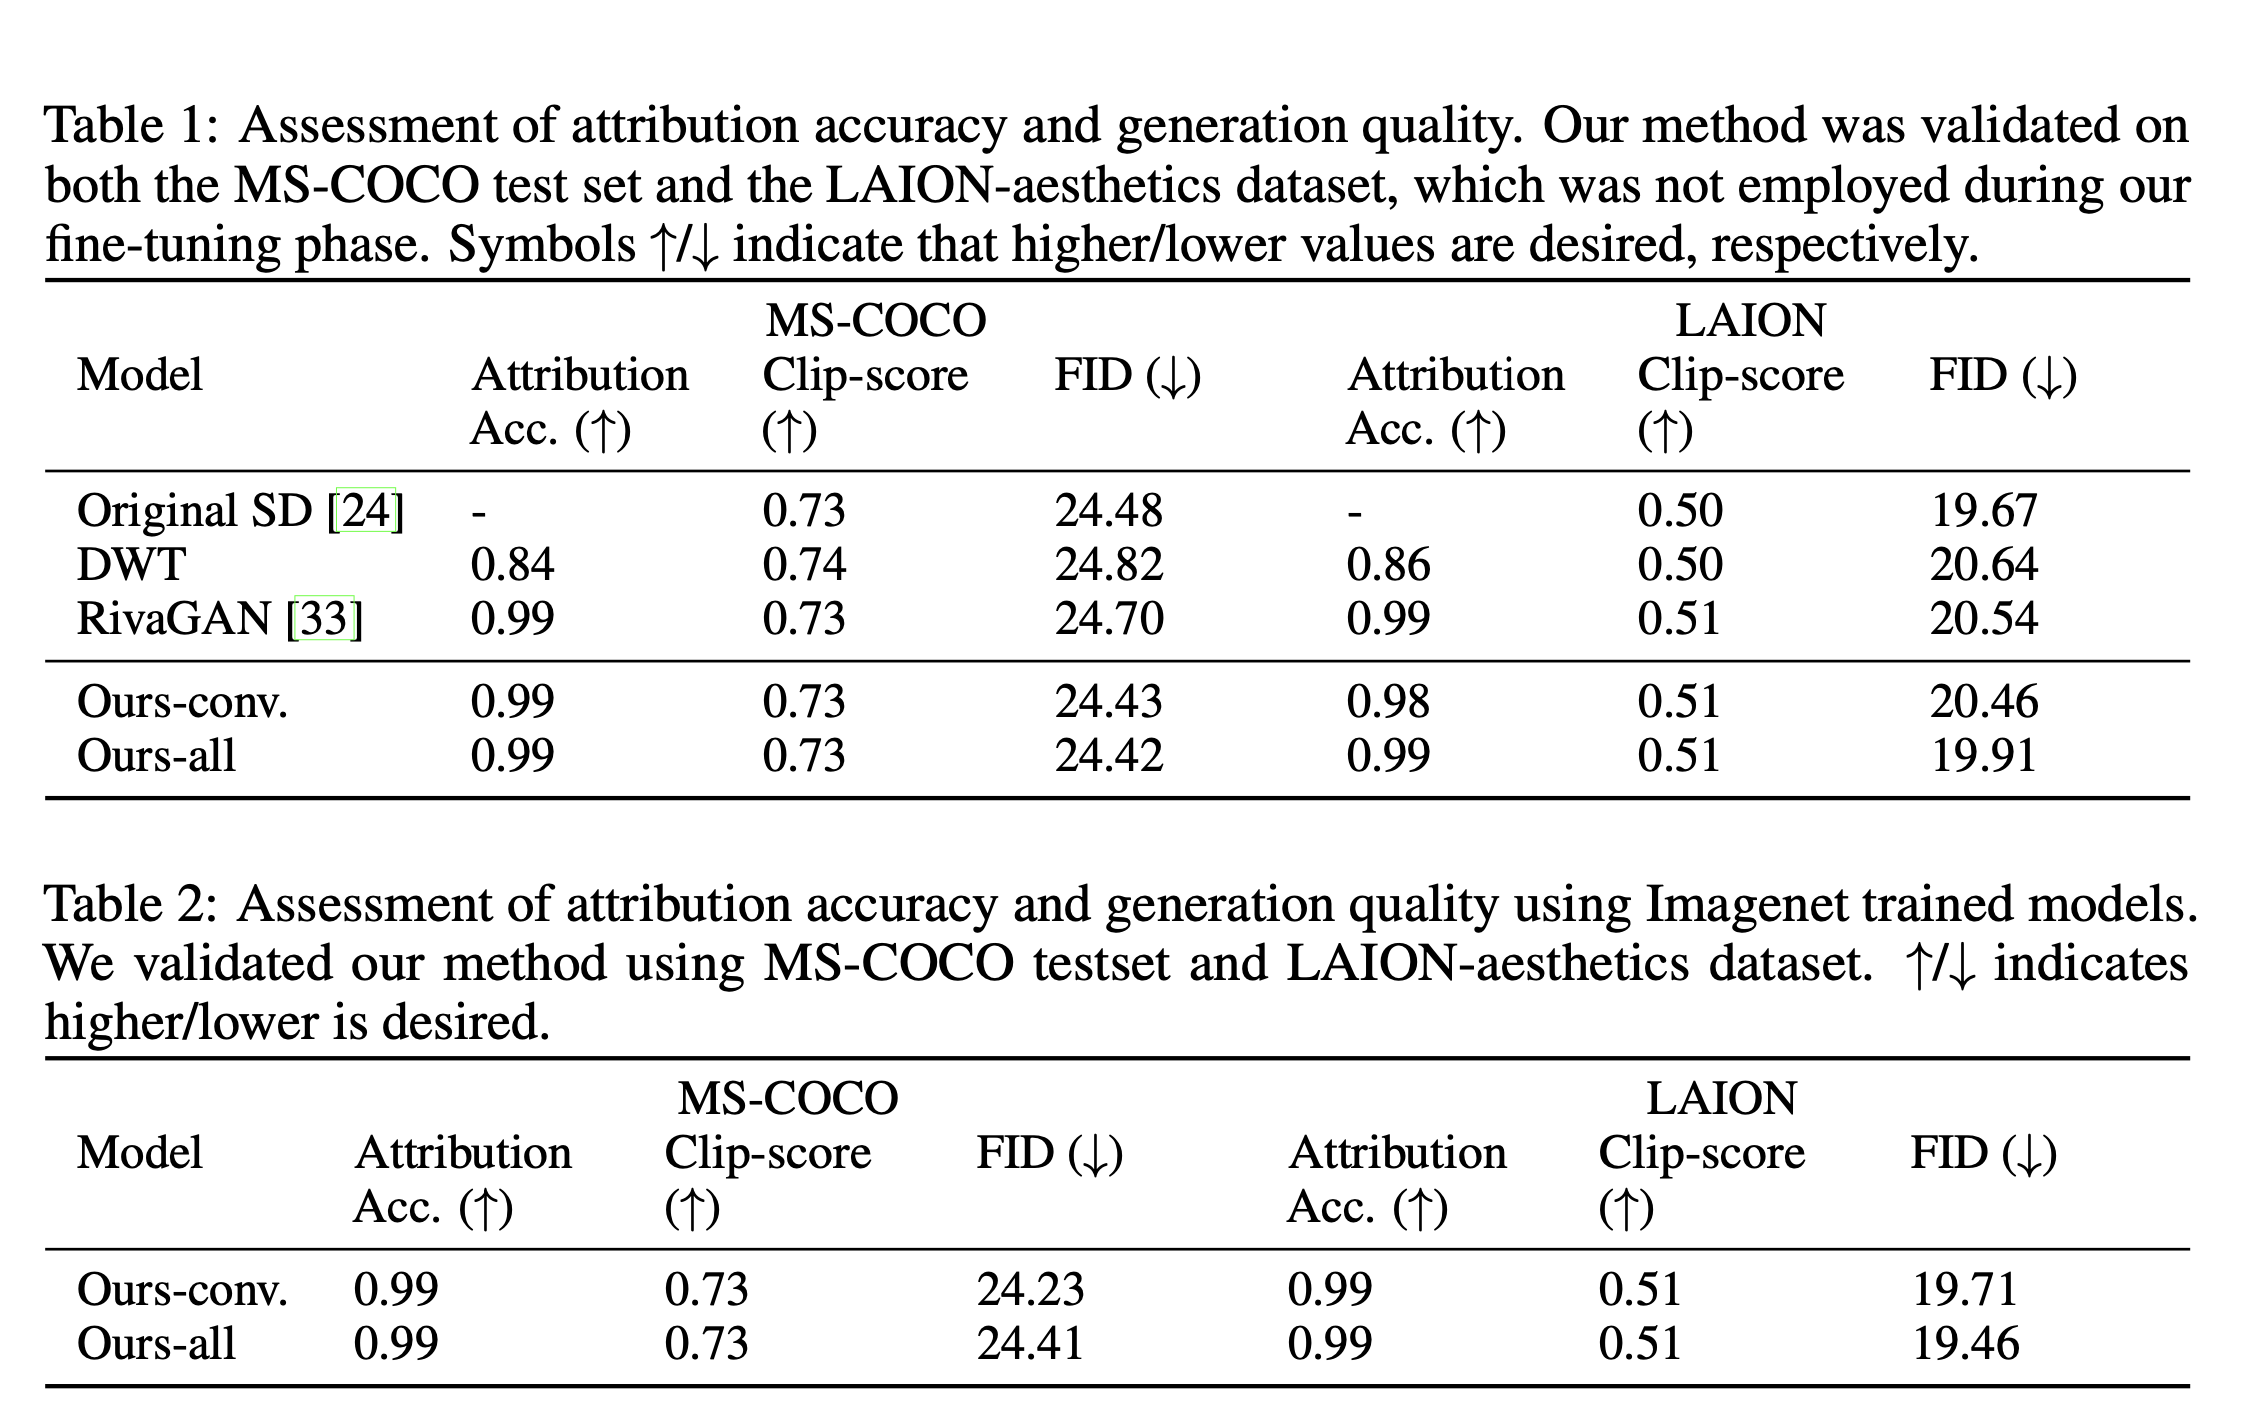
"WOUAF"🐺modifies generative models by each user's unique digital fingerprint, imprinting an identifier onto the resultant content.
🐺incorporates fine-tuning into T2I (Stable Diffusion Model) and demonstrates near-perfect attribution accuracy with a minimal impact on quality.


WOUAF: Weight Modulation for User Attribution and Fingerprinting in Text-to-Image Diffusion Models
@ChanghoonKim3, Kyle Min, @patelmaitreya, Sheng Cheng, @Yezhou_Yang
tl;dr: augmentation-robust user signature to SD results
#kornia used for data aug.
arxiv.org/abs/2306.04744



Jacob Fang retweeted

Tired of fine-tuning image generation models on each subject you care to generate? Today, we release SuTI, a zero-shot subject-driven text-to-image generator that operates fully in-context without tuning. One SuTI model is all you need!
Website: open-vision-language.github.…

Jacob Fang retweeted
Anti-DreamBooth: Protecting users from personalized text-to-image synthesis
abs: arxiv.org/abs/2303.15433
project page: anti-dreambooth.github.io/
github: github.com/VinAIResearch/Ant…

Jacob Fang retweeted

For anyone who isn't already aware of it, Tiled VAE is a way to create giant (4k+) images in automatic1111 without any kind of visible seams or lots of complicated steps. Info in comments. #AIArt
#StableDiffusion2 / #StableDiffusion

Jacob Fang retweeted
📽️Text-to-Video?
It could revolutionize entertainment as we know it.
Here's Phenaki, a model that can synthesize realistic videos from text prompt sequences.
More examples below ↓
Jacob Fang retweeted
OpenAI just dropped a prototype of 3D DALLE (called “Point-E”) 👀. It isn’t as good as Google’s DreamFusion, but blazing fast! Like ~600x faster to generate 😮. 2D DALLE has already turned the creative world upside down. How will 3D DALLE disrupt games, VR, metaverse, …? 🤯

Jacob Fang retweeted

Objaverse: A Universe of Annotated 3D Objects
800K+ 3D models with descriptive captions
arxiv: arxiv.org/abs/2212.08051
website: objaverse.allenai.org/

Jacob Fang retweeted
✨ Introducing Imagine 3D: a new way to create 3D with text!
Our mission is to build the next generation of 3D and Imagine will be a big part of it. Today Imagine is in early access and as we improve we will bring it to everyone captures.lumalabs.ai/imagine
Jacob Fang retweeted
I am on the academic job market this year. I study data mining, machine learning and trustworthy AI, especially for graphs and multimedia with applications to network science, healthcare, cybersecurity and social good. Please find out more information at jiank2.web.illinois.edu/