
Final year ML PhD student at UW CSE
Joined June 2020
- Tweets35
- Following159
- Followers247
- Likes292

Motif 3 is using a SuperBPE tokenizer! Very happy to see that superwords are boosting encoding efficiency (=> inference speed) in Korean as well as important domains like math and code!

Motif 3 is officially here.
Today, we’re releasing Motif 3 Base and Motif 3.
Motif 3 Base is our pretrained foundation model, while Motif 3 is built on top of it with post-training using NVIDIA NeMo-RL.
Both models were developed with the support of Korea's Ministry of Science and trained on NVIDIA B200 GPUs.
With Motif 3, we’re taking our first step into the frontier LLM race.
There’s still a long way to go, but we believe we’ve built a model that deserves to be in the race.
We’ve shared the details in our technical report and blog post.
In collaboration with NVIDIA, we’re also releasing an NVFP4 version of Motif 3.
All models will be available on Hugging Face.
Links are in the comments.
Jonathan Hayase retweeted

Super excited to see @LG_AI_Research’s newest model K-EXAONE-236B-A23B use SuperBPE. Their tech report shows using SuperBPE reduced their sequence lengths significantly, compared to their older model EXAONE 4.0.

Jonathan Hayase retweeted
SuperBPE (superbpe.github.io) featured in Jurafsky and Martin's new book in Computational Linguistics (web.stanford.edu/~jurafsky/s…). Amazing work by @alisawuffles and @jonathanhayase. Stay tuned for the follow-ups: arxiv.org/abs/2506.14123 and more...

Jonathan Hayase retweeted

Super happy to be at COLM!!🦙 It's been so fun to see familiar faces & make new friends.
@JonathanHayase and I will be presenting SuperBPE TODAY (Wednesday) in the 🕓11AM poster session, come say hi!
📎 superbpe.github.io/

Jonathan Hayase retweeted
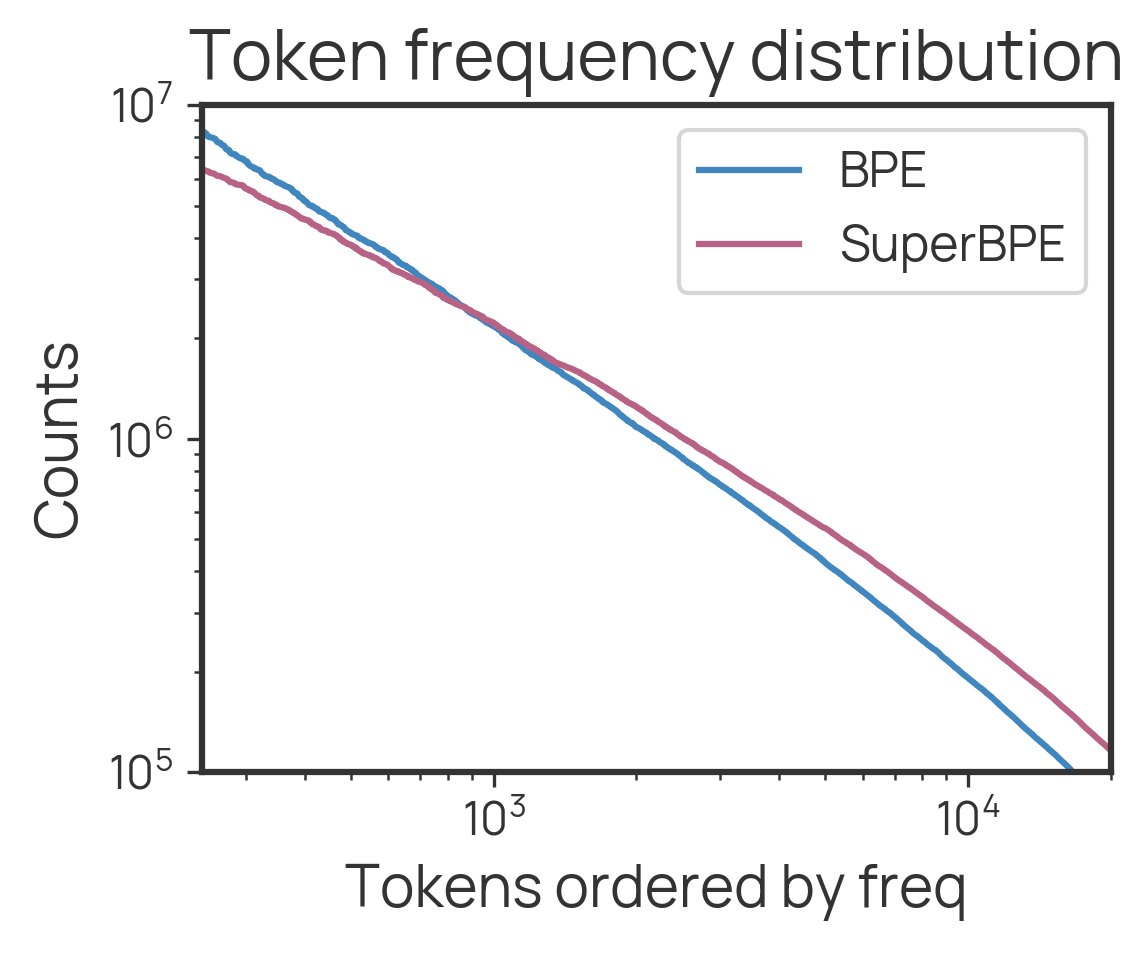
Super excited to see @moondream_ai's newest model use SuperBPE!! We did a little bit of analysis — using SuperBPE reduced their seqlen by 21% on average and made the token frequency distribution more uniform, meaning fewer hyper-frequent & hyper-rare tokens!


Do you ever wish all LLMs used the same tokenizer?🧑🤝🧑
We present an *efficient, lossless* method to convert any LM into a byte-level model at inference time. This fixes weird tokenization artifacts at the prompt boundary and enables ensembles of LMs with mismatched tokenizers! 🧵

We also show that a (byte-level) ensemble of OLMo 2, Llama 3, and Qwen 3 outperforms its constituent models on downstream evals!
Then, we use proxy-tuning to apply the post-training of OLMo 2 to Qwen 3 models (at inference time)!
Joint work with @alisawuffles, @nlpnoah, @sewoong79! 🧠
Paper 📜: arxiv.org/pdf/2506.14123
Code 🐙: github.com/SewoongLab/byte-s…
Tokenizers govern the allocation of computation. It's a waste to spend a whole token of compute predicting the "way" in "By the way". SuperBPE redirects that compute to predict more difficult tokens, leading to wins on downstream tasks!

We created SuperBPE🚀, a *superword* tokenizer that includes tokens spanning multiple words.
When pretraining at 8B scale, SuperBPE models consistently outperform the BPE baseline on 30 downstream tasks (+8% MMLU), while also being 27% more efficient at inference time.🧵

ALT Segmentation of the sentence "By the way, I am a fan of the Milky Way" under BPE and SuperBPE.
Jonathan Hayase retweeted

Model merging is a great way to combine multiple models' abilities, however, existing methods only work with models fine-tuned from the same initialization, and produce models of the same size. Our new work - PLeaS (at #CVPR2025) aims to resolve both these issues 🧵.

Jonathan Hayase retweeted
excited to be at #NeurIPS2024! I'll be presenting our data mixture inference attack 🗓️Thu 4:30pm w/ @JonathanHayase — stop by to learn what trained tokenizers reveal about LLM development and chat about all things tokenizers.😊
What do BPE tokenizers reveal about their training data?🧐
We develop an attack🗡️ that uncovers the training data mixtures📊 of commercial LLM tokenizers (incl. GPT-4o), using their ordered merge lists!
Co-1⃣st @JonathanHayase
arxiv.org/abs/2407.16607 🧵⬇️


Jonathan Hayase retweeted

We are just a few days away from a presentation from @alisawuffles presentation on "Data Mixture Inference: What do BPE Tokenizers reveal about their training data?" 🤗
Check it out Aug 19th!
Learn more: cohere.com/events/cohere-for…

Tokenizers and autogregressive LMs are both trained to compress text, but tokenizer training is deterministic and we know exactly how it works!
This makes inverse problems wrt the data much easier. There's a wealth of info lurking in public tokenizers waiting to be extracted!
What do BPE tokenizers reveal about their training data?🧐
We develop an attack🗡️ that uncovers the training data mixtures📊 of commercial LLM tokenizers (incl. GPT-4o), using their ordered merge lists!
Co-1⃣st @JonathanHayase
arxiv.org/abs/2407.16607 🧵⬇️
Jonathan Hayase retweeted
What do BPE tokenizers reveal about their training data?🧐
We develop an attack🗡️ that uncovers the training data mixtures📊 of commercial LLM tokenizers (incl. GPT-4o), using their ordered merge lists!
Co-1⃣st @JonathanHayase
arxiv.org/abs/2407.16607 🧵⬇️
Jonathan Hayase retweeted
Congratulations to @JonathanHayase on winning the 2024 ICML Best Paper Award for his work during his Google internship.

We have been awarded two Best Paper Awards at @icmlconf 2024 for 'Stealing Part of a Production Language Model' and 'Considerations for Differentially Private Learning with Large-Scale Public Pretraining'!
arxiv.org/abs/2403.06634
arxiv.org/abs/2212.06470

Jonathan Hayase retweeted

Our paper with extra experiments on the causes and extent of data leakage: arxiv.org/abs/2311.17035
Thanks to the incredible work of Milad Nasr, Nicholas Carlini, Jon Hayase, Matthew Jagielski, @afedercooper, @daphneipp, @chris_choquette, @Eric_Wallace_, @florian_tramer
Jonathan Hayase retweeted

📜🚨📜🚨
NN loss landscapes are full of permutation symmetries, ie. swap any 2 units in a hidden layer. What does this mean for SGD? Is this practically useful?
For the past 5 yrs these Qs have fascinated me. Today, I am ready to announce "Git Re-Basin"!
arxiv.org/abs/2209.04836
Jonathan Hayase retweeted

Today we are releasing a CLIP ViT-L/14 model with 79.2% zero-shot accuracy on ImageNet.
Our model outperforms OpenAI's CLIP by a large margin, and outperforms even bigger models (ViT-g/14) trained on LAION-2B
Check it out at huggingface.co/laion/CLIP-Vi…!
