

Graduate student in Taiwan. Leader of KohakuLab. Researcher/Dev in ComfyOrg
Taiwan
Joined May 2021
- Tweets3.8K
- Following1K
- Followers4.8K
- Likes29.4K


Pinned Tweet
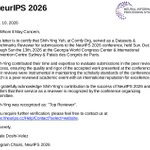
TT-VidT is accepted at #NeurIPS2026 🎉
A temporal-decoupled methodology in video pretraining to provide real "motion" info extracted from the video and only requires small scale training to reach high quality results.
Huge thanks to all collaborators, @NVIDIAAI and @spellbrush

I have 2x2080ti-22G (modded) and I found 2080ti also have similar unlock stuff from community,
I'm trying to make it become initramfs module (easier to recover than the UEFI module design) and see if it works.
UwUb

Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75

2080ti success
xitter.cf/KBlueleaf/status/21141…
Now I also confirmed that 2080ti unlock is successful with similar approach as the 30-series' method
it reach nearly same speed as 350w 3090(locked) with only 250w in mmapeak and mamf-finder
github.com/KohakuBlueleaf/Ko…

Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75
Remember to check my latest news on 2080ti!
xitter.cf/KBlueleaf/status/21141…
Now I also confirmed that 2080ti unlock is successful with similar approach as the 30-series' method
it reach nearly same speed as 350w 3090(locked) with only 250w in mmapeak and mamf-finder
github.com/KohakuBlueleaf/Ko…
琥珀青葉@KohakuLab retweeted
Now I also confirmed that 2080ti unlock is successful with similar approach as the 30-series' method
it reach nearly same speed as 350w 3090(locked) with only 250w in mmapeak and mamf-finder
github.com/KohakuBlueleaf/Ko…
Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75
For those who don't know:
1. This unlock the "nerfed FP32 accumulator" stuff
2. you can rent a A6000/6000 ada to test the mmapeak to know what I'm saying (or check the FP16 accumulation speed of 3090/4090)
3. no unlock core, no overclock, it just remove the nerf
And as this unlock only happen in tensor core:
1. not help mining, not help gaming
2. only help AI usage (potentially DLSS but not guranteed)
琥珀青葉@KohakuLab retweeted
Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75

琥珀青葉@KohakuLab retweeted

Something exciting is coming. 👀✨
We've been working on an anime-focused 2B pretrained DINOv3 model!
Our internal evaluations show promising improvements across a wide range of anime-related downstream tasks.
We're now making the preparations for release.
Stay tuned! 🚀


琥珀青葉@KohakuLab retweeted
I made FP16 fixed version of MOSS-image
It support any FP16 compute card (such as V100/2080ti) without any issue. and if your lora or PEFT model only trained QKVO/MLP layers, it can be used directly without issue!
huggingface.co/KBlueLeaf/MOS…


KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***

I made FP16 fixed version of MOSS-image
It support any FP16 compute card (such as V100/2080ti) without any issue. and if your lora or PEFT model only trained QKVO/MLP layers, it can be used directly without issue!
huggingface.co/KBlueLeaf/MOS…
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
琥珀青葉@KohakuLab retweeted
The style lora test on Moss-image-base
with 100step only

KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
The style lora test on Moss-image-base
with 100step only
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
琥珀青葉@KohakuLab retweeted
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***