

Scale-out, disaggregated, software-defined storage with performance like local flash. We enable our customers to achieve hyperscale efficiency and cost savings.
San Jose, CA | Haifa, Israel
Joined July 2018
- Tweets2.1K
- Following224
- Followers519
- Likes378




Pinned Tweet
🚀 Join us on Wednesday, June 12th at 9:00 AM PT for the "Securing, Backing Up, and Optimizing Kubernetes/Containerized Environments" EcoCast by ActualTech Media! Win a $300 Amazon gift card! 🎁 ow.ly/Fs3U50SfnnU
@kubernetesio #k8s @actualtechmedia #dataplatform

Is your business prepared for unexpected downtime? 🚨
See how Lightbits software-defined storage keeps your applications running—no matter what.
lightbitslabs.com/resources/…
#SoftwareDefinedStorage #SDS #BlockStorage #HighAvailability #CloudInfrastructure #StorageArchitecture

NeoClouds that unlock new margins by monetizing the KV cache will win.
Curious how? Read on:
lightbitslabs.com/blog/selli…
#AIInfrastructure #KVCache #NeoCloud #LLMInference #GPUComputing

We’re heading to NVIDIA GTC Berlin (Oct 20–22)!
See how Inferra by Lightbits accelerates long-context AI inference, drastically lowers TTFT, and delivers superior tokenomics.
Let's connect! 👇
lightbitslabs.com/event/nvid…
#GTC26 #GTCBerlin #AIInference #LLM #KVCache

Why $/GPU/hr is destroying your LLM inference margins 📉
Start measuring the business value your hardware actually produces.
Read the full breakdown here 👇
lightbitslabs.com/blog/why-t…
#AI #LLM #Inference #Tokenomics #GPUTokenomics #KV Cache

Lightbits Labs joins the AIDC Debate Podcast to discuss how next-gen AI workloads are being transformed. Tune in now👇 lightbitslabs.com/resources/…
#AIDCDebate #KVCacheOptimization #AIPerformance #GPUUtilization #PredictivePrefetch #AIInfrastructure #NextGenAI

Rebuilding a 10M+ token context window costs over 1.5 hours of 8-GPU compute time.
Why pay twice for the same prefill?
Read our breakdown of inference economics: 🔗 lightbitslabs.com/blog/the-m…
#LLM #AIInfrastructure #GPU #KVCache #Inference #MLOps

We’re heading to NVIDIA GTC Berlin (Oct 20–22)!
See how Inferra by Lightbits accelerates long-context AI inference, drastically lowers TTFT, and delivers superior tokenomics.
Let's connect! 👇
lightbitslabs.com/event/nvid…
#GTC26 #GTCBerlin #AIInference #LLM #KVCache

Ready to supercharge your Lightbits Private Cloud deployment? ☁️
Bookmark the master map now and empower your team to build faster and smarter! 👉 lightbitslabs.com/blog/know-…
#PrivateCloud #CloudEngineering #CloudInfrastructure

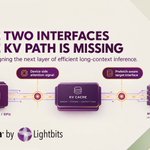
We wrote an open invitation to accelerator, fabric, and storage vendors to co-design two missing KV cache interfaces. Read the full breakdown by Arthur Rasmusson here: lightbitslabs.com/blog/the-t…
#LLMInference #KVCache #AIInfrastructure #HardwareAccelerators #MemoryFabric #vLLM

Learn how block storage architectures differ in HCI vs disaggregated storage, and which model delivers better scalability, performance, and cost efficiency.
ow.ly/Eu8I50XH9Vl
#BlockStorage #HCI #DisaggregatedStorage
On the latest episode of Truthin IT, Lightbits Labs explains how Inferra delivers faster TTFT, more tokens per GPU, and room for bigger context windows.
If you run GPU clusters, watch this one:
🎧 truthinit.com/index.php/vide…
#AIInfrastructure #GPU #AIInference #LLM #KVcache #MLOps

In our latest post, Arthur Rasmusson breaks down why ZDR and KV cache protection are the same problem, and proposes an architecture to turn ZDR from an unprovable promise into a cryptographically provable SLA.
lightbitslabs.com/blog/zero-…
#AI #LLM #Inferra #ZeroDataRetention

We’re heading to NVIDIA GTC Berlin (Oct 20–22)!
See how Inferra by Lightbits accelerates long-context AI inference, drastically lowers TTFT, and delivers superior tokenomics.
Let's connect! 👇
lightbitslabs.com/event/nvid…
#GTC26 #GTCBerlin #AIInference #LLM #KVCache

Lightbits Labs joins the AIDC Debate Podcast to discuss how next-gen AI workloads are being transformed. Tune in now👇 lightbitslabs.com/resources/…
#AIDCDebate #KVCacheOptimization #AIPerformance #GPUUtilization #PredictivePrefetch #AIInfrastructure #NextGenAI

Lightbits SDS is now officially certified for Red Hat OpenStack Services on OpenShift—unlocking a new era of cloud infrastructure modernization.
Learn more: lightbitslabs.com/press-rele…
#OpenShift #RedHatOpenStack #OpenShiftStorage #CloudModernization #SoftwareDefinedStorage #NVMeTCP

🔐 Ready to take your data security to the next level—without compromising NVMe/TCP performance?
Explore the full story 👉 lightbitslabs.com/blog/using…
#BlockStorage #CyberSecurity #DataStorage #NVMeTCP #DataProtection

We’re excited to join the Intel Capital AI Innovation Summit in Munich!
📌 Note: Spots are strictly limited. Request your invite here: luma.com/b3ek8mll
#AI #IntelCapital #SovereignAI #KVcache #LLM #MunichTech

Think your LLM inference pipeline is running at peak efficiency just because nvidia-smi shows 90%+ GPU utilization? Think again. 🚨
lightbitslabs.com/blog/the-u…
#AIInference #GPUUtilization #KVCache #LLMOps #Tokenomics #MachineLearning

Break free from DAS-vs-SAN compromises.
Modernize your data center and maximize efficiency!
👇 Dive into our full guide to disaggregated storage:
lightbitslabs.com/blog/the-u…
#DisaggregatedStorage #NVMe

Is your LLM serving strategy still treating KV cache as an afterthought? It’s time to rethink everything. Dive in now 👉lightbitslabs.com/blog/kv-ca…
#KVCache #AIInfrastructure #InferenceOptimization #GPUComputing
