
Student Researcher @GoogleDeepmind, PhD Student @TU_Muenchen, previously Research Intern @InceptiveCom
Munich, Germany
Joined October 2022
- Tweets141
- Following1.2K
- Followers702
- Likes8.9K




Pinned Tweet
Accurate reward guidance in diffusion models has been a long-standing challenge.
We propose Diamond Maps 💎, through stochastic flow maps we make reward guidance both accurate and scalable.
Luca Eyring retweeted

1/ The tokenizer is a new scaling axis!
We introduce an approach for diffusable representation learning that's principled, scalable, and works when DINO/LeJEPA collapse.
We get joint tokenizer+diffusion scaling laws and it's compute-optimal vs raw diffusion
w/ @drfeifei @GordonWetzstein @jcjohnss @ericryanchan @vincesitzmann @KyleSargentAI
Thread, Paper, and Blogpost below
Luca Eyring retweeted

Continuous Diffusion LMs went from niche to contender this year, but the recipe is shaky: why self-conditioning? How to embed tokens? 🤨
Our new work takes your one-hot flow from 4% to 50% on TinyGSM without self-conditioning, and explores the design space of CDLMs. 🔥🚀 (1/6)
Luca Eyring retweeted

We introduce ExploreNet🔍 for learnable exploration in diffusion RL.
ExploreNet learns an adaptive exploration distribution conditioned on the current state, rewarded by the diversity of the rollouts.
➡️ Faster, more targeted learning in diffusion GRPO.
Luca Eyring retweeted

We're recruiting PhD students at #AITHYRA in Vienna! Working on ML methods at the intersection of AI and biology.
Details & apply: phd.aithyra.at
Feel free to reach out if you have questions!


Luca Eyring retweeted

We can finally talk about it:
We found a way to extract hidden reasoning of frontier models using a vulnerability in the APIs of every frontier AI company.
We verified that our reasoning token count matches billed API thinking tokens 1:1 for most of the prompts we queried.


Luca Eyring retweeted

📄 Releasing the Soofi S pretraining tech report: a sovereign, open foundation model for German and English
Today we’re publishing the full pretraining tech report and project page for Soofi S 30B-A3B — a Mixture-of-Experts hybrid Mamba model trained on ~27 trillion tokens with deliberately up-weighted German.
What’s in the report:
🏆 Strongest fully open model in our evaluations on BOTH the English and German aggregates — ahead of Olmo 3 32B and Apertus 70B (full methodology in the report)
📋 Radical transparency: complete per-source data accounting, all hyperparameters, training + eval code, checkpoints — everything under permissive licenses
🇩🇪 Trained end-to-end on Deutsche Telekom’s Industrial AI Cloud in Munich — sovereign AI infrastructure on German soil
Soofi S combines frontier-level capability with the highest measured aggregate long-context decode TPS, and unlike full-attention dense baselines maintains high throughput as context grows. The figure plots Capability Index versus measured aggregate decode TPS/GPU at 40K context and batch 32. The Capability Index averages five benchmark groups, i.e., Code, GSM8K, GPQA-Diamond, English aggregate, and German aggregate, after normalizing each group to the best plotted model. Aggregate decode TPS/GPU is measured with a TP=1, one-B200 vLLM latency-subtraction protocol.

Diffusion circle happening this afternoon!

📢 Diffusion circle at @icmlconf 2026: join us Thursday July 9 at 3:30PM at the information desk / job board, we'll head out from there and find a spot to sit. No agenda, just get together and talk shop.
Please tell your friends and tag people who might be interested!

Luca Eyring retweeted
Come by now at poster #2711!

✨Tomorrow's the day! Excited to present this work with @LucaEyring at ICML in HALL A #2711 at 10:30 am✨ If you're interested in extracting knowledge from vision transformers for downstream tasks, come by! Looking forward to great discussions and new research ideas.
Come by now at poster #2711!
✨Tomorrow's the day! Excited to present this work with @LucaEyring at ICML in HALL A #2711 at 10:30 am✨ If you're interested in extracting knowledge from vision transformers for downstream tasks, come by! Looking forward to great discussions and new research ideas.
Luca Eyring retweeted

✨Tomorrow's the day! Excited to present this work with @LucaEyring at ICML in HALL A #2711 at 10:30 am✨ If you're interested in extracting knowledge from vision transformers for downstream tasks, come by! Looking forward to great discussions and new research ideas.
Luca Eyring retweeted
I‘m at ICML this week and we’re presenting Diamond Maps at Hall A #2713 today at 2pm @electronickale, @zeynepakata, @peholderrieth!
Also, feel free to DM if you wanna chat about diffusion/flows/reward alignment/etc.

I‘m at ICML this week and we’re presenting Diamond Maps at Hall A #2713 today at 2pm @electronickale, @zeynepakata, @peholderrieth!
Also, feel free to DM if you wanna chat about diffusion/flows/reward alignment/etc.

Luca Eyring retweeted

#ICML2026 kicks off in three days! We're excited to be presenting eight papers at the main conference this year. See the thread below for each paper, plus presentation times and locations 👇 Talk to our authors if you are interested!

Luca Eyring retweeted

🚀New Paper
arxiv.org/abs/2606.28551
Everyone obsesses over VLM architectures & training recipes. But what about the data?
Presenting the latest work in the DataComp-series: a testbed for VLM data curation with 1,000+ controlled experiments and some surprising lessons 👀
🧵👇

Luca Eyring retweeted
Happy to share that we have 8 papers accepted to #ICML2026! 🎉
Most of the authors will be traveling to Seoul, Korea 🇰🇷 — feel free to reach out and chat with them if you’re interested in the work.
See the full thread below for our papers 👇

Luca Eyring retweeted

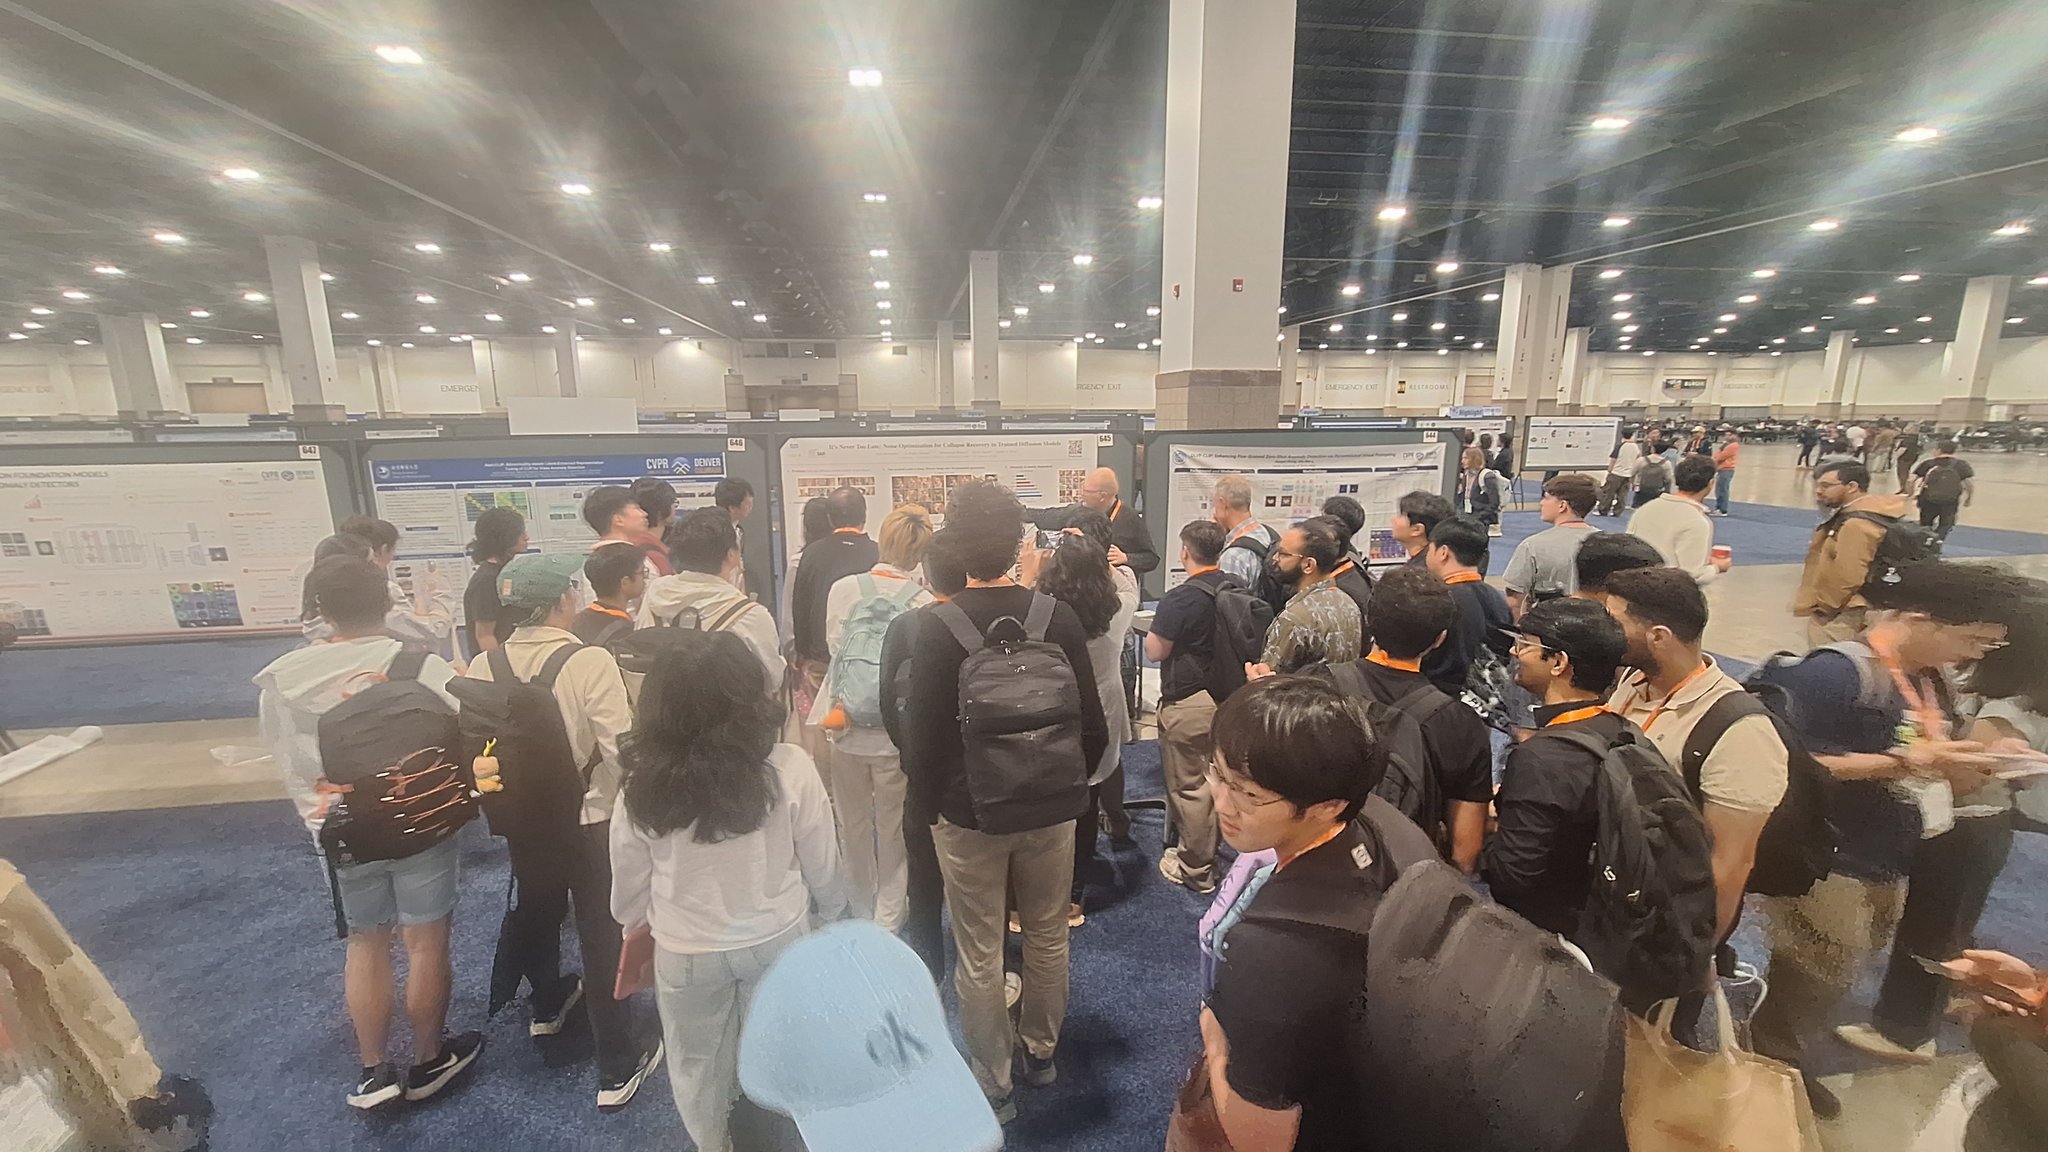
Absolutely packed at
It’s Never Too Late: Noise Optimization for Collapse Recovery in Trained Diffusion Models
tldr: recover diversity in trained
T2I diffusion models w/o retraining by optimizing noise latents directly
#CVPR2026
@annekharrington @ASophiaKoepke @ShyamgopalKart1


Luca Eyring retweeted

🧵1/9 Rex has been selected for an oral presentation at #ICML2026! 🎉
We make diffusion/flow model solvers exactly reversible (bijection), for both ODEs and SDEs
Last project of my Ph.D. w/ Chen Liu @ClarksonUniv → first project of my postdoc at #AITHYRA!
Luca Eyring retweeted

#CVPR2026 paper: It's Never Too Late: Noise Optimization for Collapse Recovery in Trained Diffusion Models
Text-to-image models often collapse to near-identical samples. Our fix: optimize the noise. Start from pink 🩷, not white noise.
🔗akoepke.github.io/divgen/ind…
1/6