





Pinned Tweet
Visual interaction models need a first exam in closed-loop assistance!
Unlike reference-based evaluations on prerecorded videos, ours evaluates assistance through user behavior and task outcomes, using controllable simulated users with diverse personas and scheduled out-of-plan events.
Using this environment, we not only establish a benchmark, but also train an interaction model through simulation RL, improving both task success and interaction quality!
Paper: arxiv.org/abs/2611.08286
Project page: interactive-visual-gym.sales…
Code: github.com/SalesforceAIResea…


Interactive Visual Gym: Evaluating Visual Interaction Models Through Simulation
Can a visual AI assistant’s real-time advice actually help someone finish a procedural task? Meet Interactive Visual Gym (IVG), an open simulation framework for evaluating and training visual AI assistants in closed loop. We recreate cooking, household, and phone tasks in a simulation world alongside simulated users with different skills and preferences. These users act, make mistakes, ask questions, and respond to guidance – allowing us to test how accurately, appropriately, and promptly an assistant supports them as the activity unfolds.
→ 14 assistants, 315 scenarios: the best performing model, Gemini-4-Argon, completes only 53.4% of tasks on time
→ Human preferences match our simulator scores ~80% of the time
→ Training in the simulator lifts a 4B open model’s success rate’ from 33.3% to 42.2% on unseen tasks
Explore the paper, code, and demos: sforce.co/4zwQdWU
#EnterpriseAI #AgenticAI #FutureOfAI
Excited to share that MolmoMotion has been selected as a Highlight paper at NeurIPS 2026! 🎉
Our code, model weights, dataset, and benchmark are all openly available:
📊 MolmoMotion-1M — the largest dataset of action-described, object-grounded 3D point trajectories, built from 1.16M videos.
🤖 MolmoMotion-4B — a 4B model for language-conditioned 3D motion forecasting, achieving state-of-the-art results on PointMotionBench with demonstrated transfer to robot planning.
📏 PointMotionBench — a human-verified benchmark for 3D motion forecasting, spanning 111 object categories and 61 motion types.
Download, experiment, and build on it—we’d love to see what you create!
molmomotion.github.io/

Chenhao Zheng retweeted

Ai2 just released MolmoMotion on Hugging Face
A 4B vision-language model
that forecasts 3D point trajectories
from video and language instructions,
predicting how objects move in space over time.

We believe in the representation of 3d point trajectory as an alternative form of world modeling. it is universal to all object, more compact than pixel, and can directly be consumed by many downstream task.
p.s. the key for us to generate high quality real world data is we respect objectness and do hard work in object grounding -- which allows us to properly filter and smooth noisy trajectories coming out of off the shell 3d tracking methods.
Chenhao Zheng retweeted

Check out our new work, You Only Judge Once: a 4B multimodal reward model that scores all N responses in a single forward pass. It's both faster (up to N×) and more accurate than scoring each in isolation. As a GRPO reward, it also delivers more gains on open-ended generation than single-response RMs.
📄 arxiv.org/abs/2604.10966
🤖 hf.co/yinuoy/MR2-Molmo2-4B-R…
📊 hf.co/datasets/yinuoy/MR2Ben…
💻 github.com/yinuoyang01/multi…
For efficiency,despite the cost of trajectory extraction, TrajViT trains faster, consumes less GPU memory, and performs quicker inference for sequences ≥ 64 frames.

1
4
510
We also connect TrajViT and ViT3D to Llama-3, forming two VideoLLMs. Across six Video-QA benchmarks, TrajViT-LLM delivers +5.24 pp accuracy, trains 4 × faster* and requires 18 × fewer inference FLOPs than the ViT3D counterpart. We also demonstrate in the paper that our model has a good scaling behavior, in terms of both training data size and inference frame number. Learn more in our paper arxiv.org/abs/2505.23617 or project page: raivnlab.github.io/trajvit/!
1
2
420
Extremely grateful to work with the amazing team!!
@JieyuZhang20, @mrezasal1, Ziqi Gao, Vishnu Iyengar, Norimasa Kobori, Quan Kong, @RanjayKrishna
1
2
392
Having trouble dealing with the excessive token number when processing a video? Check out our paper that is accepted by ICCV 2025 with an average score of 5.5! We tokenize video with tokens grounded in trajectories of all objects rather than fix-sized patches. Trained with a CLIP objective, TrajViT is the first model to consistently outperform standard ViT with all video understanding tasks we tested even with modern Video-LLM QA—while using ~10 × fewer tokens.
paper: arxiv.org/abs/2505.23617
project page: raivnlab.github.io/trajvit/
Details in the thread.

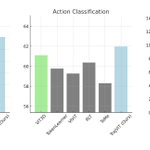
For evaluation, we compare it with standard ViT with space-time patch tokens (ViT3D) and state-of-the-art token merging methods. Task scope: video-text retrieval, spatiotemporal detection, action classification, and VideoLLM QA. TrajViT surpasses ViT3D on all tasks. At our largest scale, we see +6 pp top-5 recall over ViT3D while carrying only 10 % of its token load.

1
3
365
We train a video encoder, TrajViT, using our tokenization paradigm with CLIP objective, on a large scale dataset of 50M image + 10M video. TrajViT can naturally process image data by treating each image segment as a trajectory of length one, allowing seamingless joint training with both videos and images.
1
3
372
Naively splitting the video tensor into patches is known to introduce memory bottleneck, but is still the de-facto way of tokenizing video due to its strong performance. As shown in figure, We fundamentally transform traditional video tokenization by reorganizing video tokens to correspond to trajectories of all the objects in a video, similar to how our human perceives the visual stream as discovered by cognitive scientists. The result is a token set that is (i) semantically meaningful and temporally non-redundant, (ii) token number positively related to scene complexity, and (iii) robust to lighting and camera motion.

1
4
580
Chenhao Zheng retweeted

🔥We are excited to present our work Synthetic Visual Genome (SVG) at #CVPR25 tomorrow!
🕸️ Dense scene graph with diverse relationship types.
🎯 Generate scene graphs with SAM segmentation masks!
🔗Project link: bit.ly/4e1uMDm
📍 Poster: #32689, Fri 2-4 PM 👇🧵
Chenhao Zheng retweeted

Calling all #CVPR2025 attendees!
Join us at the SynData4CV Workshop at @CVPR (Jun 11 full day at Grand C2, starting at 9am) to learn more about recent advancements in synthetic data for CV!
Explore more: syndata4cv.github.io

The 2nd Synthetic Data for Computer Vision workshop at @CVPR! We had a wonderful time last year, and we want to build on that success by fostering fresh insights into synthetic data for CV. Join us!
We welcome submissions! Please consider submitting your work! (deadline: March 31)
Website: syndata4cv.github.io/
#CVPR2025
Chenhao Zheng retweeted

🎉 Excited to introduce "The One RING: a Robotic Indoor Navigation Generalist" – our latest work on achieving cross-embodiment generalization in robot visual navigation! 🤖🌍
RING is a universal navigation policy trained entirely in simulation on diverse, random embodiments at scale. It requires no real-world training data 🚫🤖 and works out of the box on a wide range of robots!
👉 Project page: one-ring-policy.allen.ai
Chenhao Zheng retweeted

The slide is bad, her response to an audience is even worse…
“Maybe there is one, maybe they are common, who knows what. I hope it was an outlier."

Mitigating racial bias from LLMs is a lot easier than removing it from humans!
Can’t believe this happened at the best AI conference @NeurIPSConf
We have ethical reviews for authors, but missed it for invited speakers? 😡

Excited to share our #NeurIPS2024 spotlight: Acoustic Volume Rendering (AVR) for Neural Impulse Response Fields.
AVR greatly improve the state-of-the-art in novel view spatial audio synthesis by introducing acoustic volume rendering. Listen with headphone for example below
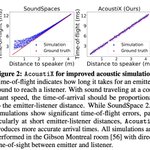
In parallel with AVR, we develop AcoustiX, an acoustic simulation platform that generates more physically accurate signals compared to simulators like soundspace. Soundspace exhibits significant errors in signal phases and arrival times, so we develop a version to solve these.

1
161
This project is led by @zitong_lan , with collaboration of @zhiwei_zzz, and advised by @mingminzhao . Thank for everyone’s great efforts!
148