

Driving innovations with open communities. 💬 Join our Discord: https://xitter.cf/t.co/4M9AHVh5qa
HangZhou, China
Joined April 2024
- Tweets1.2K
- Following186
- Followers16.5K
- Likes185





Turn complex documents into data AI agents can use with OXR-1.0, SoMark's 1.3B open-weight model for parsing PDFs and document images into Markdown or JSON.
🤖 modelscope.ai/models/SoMark/…
🏆 SOTA across three parsing benchmarks: Ranks #1 in the project’s published comparisons on olmOCR-Bench, OmniDocBench, and DocParsingBench.
⚡ Small model, top-tier speed: Also leads the project’s 21-model speed comparison at 557.77 native tokens/s.
📄 Beyond plain OCR: Recognizes 13 element types, including tables, formulas, chemical equations, chemical structures, and code blocks.
🧩 Bring your own layout model: Layout analysis is independent and pluggable, so teams can customize structure handling while retaining OXR’s recognition and reading-order capabilities.
🌀 Trained to improve from failures: Recursive self-improvement during post-training turns real document parsing failures into new optimization signals.
📜 OXR Open Source License applies.


Sage-A1.5 is here, bringing 256K context, parallel research, and evidence checks to long-horizon scientific workflows.
🤖 modelscope.ai/collections/In…
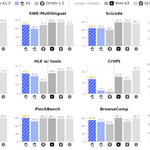
🏆 SOTA across scientific benchmarks: Scores 90.0 on PinchBench, 81.0 on FrontierScience-Olympiad, and 48.3 on FrontierScience-Research, ahead of Kimi-K3, GLM-5.3, and GPT-5.6-sol in the reported comparison.
🧩 Agentic Orchestration: When enabled, delegates independent investigations to parallel subagents with isolated contexts, then integrates their evidence and findings to guide subsequent work.
✅ Verification: Optional Verification Mode reviews progress, checks evidence and assumptions, and redirects stalled searches within the model's own reasoning, without a separate critic model at inference.
🔬 Open Scientific Discovery: Supports exploratory research through tool-assisted analysis and produces inspectable research artifacts, extending its use beyond predefined question answering.
🛠️ Native tool use for research: Supports APIs, code interpreters, search engines, and external tools for tool-augmented scientific reasoning and professional workflows.
⚡ Available in BF16, FP8, and GGUF F16/Q8/Q4 formats, with Transformers, vLLM, and SGLang support.
📜 Apache 2.0.

Spark-X2.6-4B has landed: an open-source model with 1M context, three thinking budgets, and deployment-ready formats for local agents.@SparkLLM
🤖 modelscope.ai/collections/XH…
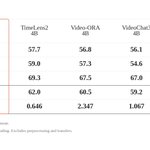
🏆 Stronger at 4B: In the team’s reported comparison table, it reaches a 63.3 average, ahead of Spark-X2.5-4B at 52.1 and Qwen3.5-9B at 49.1 across the evaluated suite.
🧠 Set the thinking budget: Switch between none, low, and high thinking modes to balance reasoning quality, latency, and cost for each task.
⚡ Built for efficient local inference: A hybrid attention design combines 1M context with resource-conscious deployment, while FP8, INT8, INT4, and GGUF releases offer practical precision and footprint tradeoffs.
🛠️ One model, multiple workflows: Use the Instruct checkpoint for everyday agent work or the Base model for continued training and customization. Supports Transformers, SGLang, vLLM, llama.cpp, Ollama, MLX, and LM Studio.
📜 Apache 2.0.


Introducing MemT-1.0, an open-weight model family with persistent, evolving memory built into model computation, enabling conversations and agents to reuse historical information without reloading the original context.
🤖 modelscope.ai/collections/Me…
🏆 Leads parametric memory methods: Across 11 memory benchmarks, MemT-1.0-Flash and MemT-1.0-Nano rank first and second among the evaluated methods.
🧠 Memory lives in the model: Dynamic local memory and trainable hyper memory retain past information without carrying the original conversation into every new inference.
⚡ Built for long-running agents: At 128K history, Nano delivers an official 1.86× end-to-end inference speedup and about 66× lower persistent storage than a full-context KV cache.
🛠️ Two backbones, one memory design: Nano is built on Qwen3.6-35B-A3B with about 3B active parameters; Flash builds on DeepSeek-V4-Flash with about 17B active parameters. Both support locally persistent memory sessions.
📜 Flash weights are released under MIT. Inherited backbone licenses still apply.

NVIDIA Nemotron Labs Dory1.0-4B is an open-weight reasoning model with up to 256K context, letting developers adjust inference compute within a single checkpoint.
🤖 modelscope.ai/models/nv-comm…
🔁 One checkpoint, adjustable compute: Run the shared recurrent block for different numbers of loops to balance latency and accuracy per task, with no retraining or model swap.
🏆 Stronger coding-agent results at 4B: At two loops, it reaches 59.5 on SWE-bench Verified in the vendor evaluation, ahead of Qwen3.5-4B at 54.7.
🧠 Extra thinking without longer answers: More loops add latent compute per token instead of simply generating more tokens.
⚡ Loop without compounding cache cost: Optional last-loop KV caching keeps one cache per recurrent attention layer, avoiding extra KV-cache overhead as loop count grows.
📚 Built for long-context workloads: 4B parameters, up to 256K context, and releases in BF16, MXFP8, NVFP4, and Q5_K_M formats.
📜 OpenMDW License Agreement v1.1.

VideoJev-4B brings direct decision-making to video understanding. Qwen3.5-4B based video decision model for temporal grounding and multiple-choice video QA.
🤖 modelscope.ai/models/MCG-NJU…
📄 modelscope.ai/papers/2610.18…
🏆 Video QA leader at its scale: Ranks #1 among sub-6B models on LVBench, Video-MME, LongVideoBench, and MLVU.
⚡ Direct decisions, not long generations: Scores candidate answers and time spans directly, making video QA and event localization easier to integrate into workflows.
🎬 Find the moment, pick the answer: Locates when an event occurs in video and answers multiple-choice questions with calibrated probabilities.
🧠 Long-video ready: Supports up to 256K context in the official video QA evaluation setup.
🛠️ Ready for local use: Released with BF16 weights, training and evaluation code, plus a quick-start demo.
📜 Apache 2.0.


Ming-3.0 is here: five open-weight audio models for controllable speech, long-recording analysis, and context-aware transcription.
🤖modelscope.cn/collections/in…
🏆 Voice cloning at the top of the open-weight ranking: Ming-3.0-tts-0.5B achieves open-weight SOTA on Artificial Analysis Controlled Voice with a 1069 Elo rating, using eight English reference voices.
🎙️ Design a voice, then direct the performance: The TTS models support voice design from descriptions or references, multilingual synthesis, and controllable delivery for podcasts, characters, and product experiences.
🧠 Turn long recordings into answers: Ming-3.0-audio-flash transcribes, summarizes, analyzes, and follows up on long audio while grounding answers in the original recording. It reaches 99.40 on BigBenchAudio S2T in the authors’ comparison.
📝 Transcribe with business context: Ming-3.0-asr-tiny accepts hotwords, domain terminology, and dialogue history to improve recognition for product names, dialects, and specialized conversations.
⚙️ Choose the fit: Flash models prioritize broader capability, while Tiny and 0.5B options target lower-cost, efficient deployment.
Xing4.0-29B-Intent turns a one-line request into structured intent, entities, relations, and action parameters, all through one schema-driven model.
🤖 modelscope.ai/models/XingChe…
🏆 Leads the authors’ extraction evaluation: Scores 58 across 6,000 samples from 48 Chinese and English public datasets, ahead of 18 evaluated general-purpose models.
🧠 Choice and extraction in one model: Handles both intent routing and structured semantic parsing, so applications can classify a request and extract the information needed to act on it.
⚙️ Built for reliable tool use: Outputs schema-constrained JSON rather than long-form replies, covering intent detection, entity recognition, relation extraction, and event extraction.
📱 Made for real product flows: Fits customer service routing, smart-device commands, terminal assistants, and agent or function-calling pipelines.
📜 Model weights, training data, and code are released under Apache 2.0.
#XingIntent #IntentUnderstanding #SemanticParsing #FunctionCalling #AgenticAI #ModelScope


MiniMax H3 Character Swap LoRA is now available on ModelScope, an experimental adapter for recasting a selected person in video from an image reference.
🤖 modelscope.ai/models/akatz-a…
🎭 Swap the performer, keep the shot: Recast a creator, actor, or avatar from a character reference while retaining the original scene, movement, and camera work.
🧩 V1.5 is the recommended checkpoint: Improved character retention in the authors’ selected V1 comparison examples.
🛠️ Built for the H3 workflow: Load it with the MiniMax H3 Ref2VA base, text encoder, and VAEs in a compatible ComfyUI LoRA workflow.
📜 MiniMax H3 Community License Agreement applies.
DeepSeek-V4.1-Flash-1017 delivers stronger coding and agent performance with faster task completion and shorter outputs. Available on ModelScope:
🤖 modelscope.ai/models/deepsee…


🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


NVIDIA Nemotron 3.5 Bolt has landed on ModelScope: a 74B-A9B open-weight VLM in a 24GB footprint.
🤖 modelscope.ai/collections/nv…
🏆 Strong agent results: The 24GB model reaches 50.98 on Terminal-Bench 2.1 and 66.75 on BrowseComp. NVIDIA positions it as the #1 open model in its class on PinchBench and #2 among open models on BrowseComp.
⚡ Built for local inference: Native 2-bit quantization fits the model into 24GB while retaining 9B active parameters per token.
👁️ Multimodal, long-context agents: Accepts text, images, and video with up to 256K shared context for prompts, tool results, and conversation history.
🧩 Choose the right variant: Use 24GB IQ2 for local inference, BF16 for post-training and custom quantization, or LiLiCorr variants for speculative decoding.
📜 OpenMDW License Agreement v1.1. Commercial and non-commercial use supported.

Introducing Hy-Memory-30B-A3B, a dedicated long-term memory writer with around 3B active parameters.
🤖 modelscope.ai/models/tencent…
📄 modelscope.ai/papers/2610.22…
🏆 Cross-framework leader: Scores 55.49 across Mem0, Hy-Memory, MemOS, and held-out EverMemOS in the fixed 20% evaluation matrix, ahead of Claude Opus 5 at 54.62.
🧠 Write memories, not chat replies: Decides what to retain, turns evidence into precise memory entries, and updates the persistent store when new information arrives.
🔄 Transfers beyond its training stack: Leads the held-out EverMemOS harness at 56.89, showing the writer can plug into unseen memory frameworks.
🛠️ Easy to integrate: Runs with vLLM and an OpenAI-compatible API, with a no-thinking mode for structured fact and preference extraction.
📜 Apache 2.0.

Meet MOSS-Image-Base: an 8.56B open-weight text-to-image foundation model built for more controllable generation.
🤖 modelscope.ai/collections/op…
🧩 More than natural-language prompts: Generate from descriptive prompts, tag sequences, or JSON layouts that specify text and object placement.
📝 Layout-aware images: Control captions, scene elements, and bounding boxes for posters, whiteboards, diagrams, and other structured visuals.
🔧 Built for customization: As the base checkpoint in the MOSS-Image family, it is designed for research, fine-tuning, and workflow-specific adaptation.
🖥️ Ready for local workflows: Includes Diffusers support, a Gradio interface, CPU offloading options, and a native ComfyUI plugin.
📜 Model weights and inference code are released under Apache 2.0.

Full GLM-5.3, compressed for multi-node local serving. Kindling AI releases an exlr8 K2/K3/K4 quantization of the 744B MoE model.
🤖 modelscope.ai/models/kindlin…
📦 Flexible memory targets: Choose profiles ranging from 219GB to 378GB, depending on the quality and memory budget of the deployment.
⚙️ One weight set, multiple precisions: K2, K3, and K4 expert weights ship together, letting users change the precision mix at load time without re-encoding the model.
🖥️ Built for distributed local inference: Designed for tensor parallelism across 3–7 unified-memory nodes, with TP=3 and TP=4 configurations already tested.
🧪 Quality-aware allocation: Hessian-calibrated manifests spend additional bits where they reduce divergence from the original BF16 model most effectively.
📌 Preview release. Performance and full BF16-alignment validation are still in progress. GLM-5.3 License applies.


NVIDIA Nemotron 3.5 Super VL is open released in BF16 and NVFP4: a 120B MoE multimodal agent model that activates just 12B parameters per token. ModelScope’s ms-swift supports both inference and fine-tuning, helping developers put the model to work and adapt it to specialized multimodal applications.
🤖 modelscope.ai/collections/nv…
💻 github.com/modelscope/ms-swi…
🏆 Agent performance: Outperforms the 5x larger Nemotron 3 Ultra on the reported Hermes Bench and LangChain evaluations.
⚡ Faster workflows: Delivers up to 5x higher throughput in its size class and completes evaluated agent tasks up to 4x faster.
👁️ Multimodal reasoning: Understands text, images, charts, documents, and video while reasoning, coding, and using tools.
🧰 Built to customize: Fine-tune with your own multimodal datasets using LoRA in ms-swift, or use NVIDIA NeMo for SFT and RL to adapt the model to domain data, tools, policies, and workflows.
🧠 Efficient deployment: NVFP4 with QAD, multi-token prediction, and cross-turn context reuse reduce repeated inference work. Supports vLLM, SGLang, TRT-LLM, and NIM across local, data center, and cloud environments.


🌍 Meet BlenderWorld from the Qwen Team, now on ModelScope!
Explore 👉 modelscope.ai/datasets/Qwen/…
Can visual agents turn real-world references into editable 3D scenes?
🧊 223 Blender tasks across 9 categories
🖼 Text, image & video inputs
📏 2,651 task-specific evaluation rubrics


Train your own few-step diffusion models faster, with OPD training workflow now offered in DiffSynth-Studio! Try example “TurTurbo” Qwen-Image-2.1 LoRAs trained with this pipeline:
🤖 modelscope.ai/models/DiffSyn…
📚 Docs: diffsynth-studio-doc.readthe…
⚡ Fast training feedback: with OPD, we are seeing training convergence typically within 2 GPU-hours.
🎯 Fewer sampling steps: distill FLUX.2-klein-base-4B and Qwen-Image-2.1 from 50 to 8 steps, or Qwen-Image-2.1-Turbo from 8 to 3, while upholding generation qualtiy.
🧠 Simple workflow: train on student-generated trajectories with teacher guidance, without pre-generating teacher trajectories or designing an additional discriminator.
📜 Release under Apache 2.0 license.


TaoMate-H3-FL2VA brings 3-step streaming audio-video generation to MiniMax H3. The TaoMate-H3 runtime reports 11.45× faster DiT inference and 10.6× faster time to first playable video than the original MiniMax H3 pipeline in its 480p benchmark.
🤖 modelscope.ai/models/TaoLive…
📄 modelscope.ai/papers/2607.24…
⚡ 11.45× faster DiT: Generates a 10-second 480p sample in 14.8 seconds of DiT time, compared with 169.6 seconds for the original MiniMax H3 pipeline in the reported setup.
▶️ Earlier playback: Produces the first playable video in about 17.3 seconds, a 10.6× improvement over the baseline.
🔊 Synchronized by design: Generates speech, sound, and video together on one timeline instead of assembling them afterward.
🎬 Continuous generation: Processes prompts in five-second blocks while preserving visual identity, voice, and motion across prompt changes. Supports portrait and landscape output at 480p, 768p, and aligned 1080p.
📜 A three-step LoRA for the MiniMax H3 FL2VA base model. MiniMax H3 Community License Agreement applies.
Fish Audio Drama 3 brings voice cloning, multi-character scenes, and in-context audio editing to a 35B-A3B open-weight MoE model.
🤖 modelscope.ai/models/fishaud…
🎭 Point-level control: Place cues such as [sighs], [laughs], and [whisper] exactly where the expression should happen.
✂️ Edit without starting over: Change a word or line while preserving the surrounding voice, timing, and delivery, then continue revising from previous takes.
👥 Built for full scenes: Generate scripts with up to 16 characters, clone voices across languages, and stream long-form speech automatically.
⚡ Production-ready streaming: Delivers the first audio in under 100 ms in the reported single-stream setup and supports high-concurrency serving through SGLang-Omni.
📜 Fish Audio Community License.
Step-5-Preview is now open weight, bringing a 1M-token context window to real-world agentic work. Its 600B sparse MoE architecture activates 27B parameters per token.
🤖 modelscope.ai/models/stepfun…
🏆 Strong open-model coding: Scores 49.0% on StepCodeBench, leading the open-weight models in the reported comparison across code generation, bug fixing, refactoring, and performance tuning.
📈 Built for professional work: Delivers strong results across software engineering, finance, and knowledge tasks, including 66.4 on FrontierFinance.
🧰 From research to deliverables: Coordinates large-scale web research, analyzes complex datasets, and produces finished reports, spreadsheets, websites, and other working artifacts.
🧠 Long-horizon agents: Supports a 1M-token context window, visual input, and workflows extending across thousands of interactions.
📜 Released under the StepFun Community License.


