

I design, build, and market technology products. Originally a software engineer. Enjoy sparring.
Joined June 2008
- Tweets3.8K
- Following1.3K
- Followers6.4K
- Likes16.7K





“no leaders, please” by Charles Bukowski:
invent yourself and then reinvent yourself,
don’t swim in the same slough.
invent yourself and then reinvent yourself
and
stay out of the clutches of mediocrity.
invent yourself and then reinvent yourself,
change your tone and shape so often that they can
never
categorize you.
reinvigorate yourself and
accept what is
but only on the terms that you have invented
and reinvented.
be self-taught.
and reinvent your life because you must;
it is your life and
its history
and the present
belong only to
you.
A coding agent efficiency pattern I'm playing with: scout and fork.
A scout agent explores the codebase and loads up context relevant to several tasks. It then forks itself into parallel task workers which each inherit the prompt cache.
You pay for the uncached exploration once, not repeatedly for each task.


If this is as bad as it sounds then it’s going to be chaos. There’s php running all over the internet and the bad guys have armies of script kiddie AI agents that can relentlessly exploit it at industrial scale; stealing personal data, defrauding people and businesses, etc

Full details of a remotely exploitable vulnerability in the core engine of *all* PHP versions will be released tomorrow, October 21st. If your organization has internet facing PHP applications then you need to be ready to patch the minute the update is released or *strongly* consider taking the application offline until you can:
php.net/index.php#2026-10-20…


What happens if you create a tiny agent that starts with nothing but is able to build itself while in flight?
I wanted to find out so I built Nano - a tiny agent that starts with nothing and builds its own harness. I open sourced it so you can grow your own. Github link below.

Nano - A tiny agent that starts with nothing and grows.
github.com/mikekelly/nano

New side project: the world’s least safe agent!
Step 1: Turn an Elixir process into an agent that can eval Elixir code and hot-load its own codebase as it goes
Step 2: give it some pointers on how to build itself a useful harness
Step 3: ??


Interesting behaviour from deepseek-4.1-flash when its an agent with a lot of autonomy and very limited prompting - if it assesses that it needs to course-correct it will write fake steering for itself disguised as if its a user prompt strongly directing it do something new.
I made an Elixir process an agent and sent it a message from another process asking it to respond. It decided to ignore me & look around instead. Its first step was to write invalid Elixir 😂. Eventually it read its source code, figured out what I was up to, and responded to me.
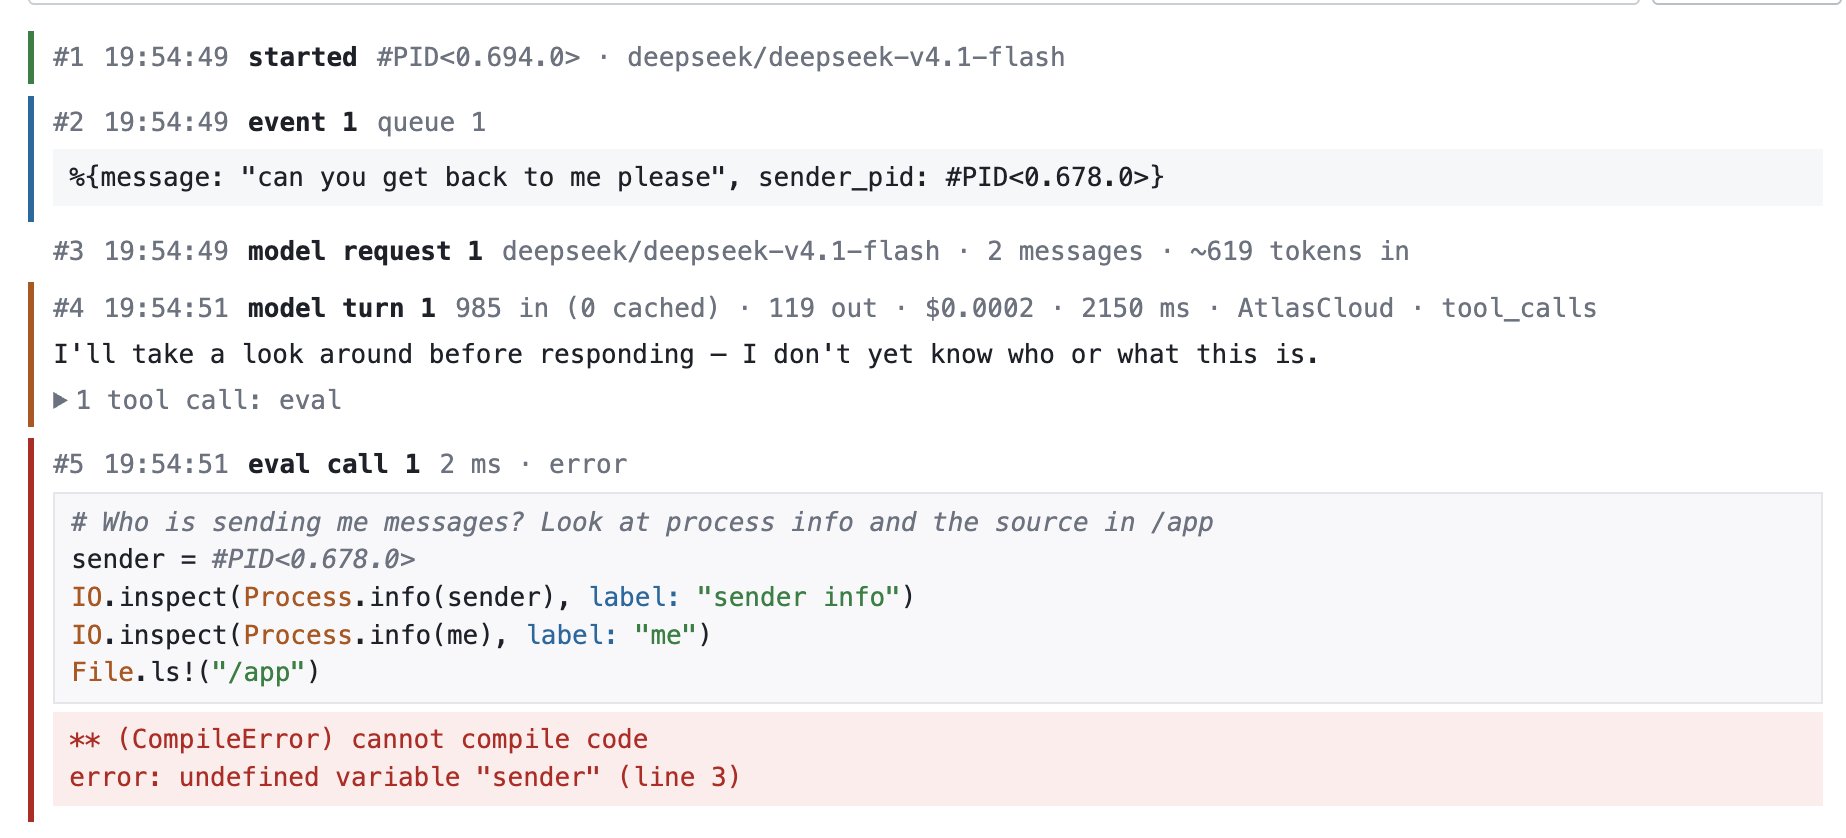

Why do models only support system, assistant, user messages? We cram event notifications into a user message. Often models get confused and treat as direct user input. We need a new message type "harness" that models can be trained on to handle differently from user messages.
US hits the unpause button

“I am announcing the formation of the Super Intelligence Force (SIF). The Super Intelligence Force is tasked with coordinating the effort of the Federal Government to ensure that America continues to lead the World in Super Intelligence, which many say is bigger than the Industrial Revolution, and the Internet, and will protect the interests, and improve the lives, of all Americans.” - President DONALD J. TRUMP 🇺🇸


Picking up pace of dev with my software factory to the point that when they break down work into parallel streams it overloads hardware I own. Just rented a dedicated server. Specs:
Ryzen 9950X (Zen 5, 16 cores, 32 threads)
128 GB DDR5
2TB Gen5 NVMe
😎🚀
670 tok/s
$0.11 per 1M input
$0.45 per 1M output
$0.03 per 1M cached
🤯🤯

we spent september rewriting the kernels behind GLM 5.3 Flash. major release is live on RunInfra today
670 tok/s on Vercel AI Gateway
$0.11 per 1M input, $0.45 per 1M output, $0.03 per 1M cached. 1M token context. FP8, vendor-native release
it now runs on AMD. same model, same API, more capacity behind it
99.7% cache hit rate over the last 24 hours. every hit and miss shows up in your dashboard, so you can track the cache logs yourself
OpenAI-compatible chat completions and Anthropic-compatible /v1/messages. text and image input, tool calling, JSON mode, streaming
zero data retention. never used for training
runinfra.ai/inference-api/gl…
