
Building local AI rigs on cheap GPUs. Unlocks, cooling, benchmarks. Everything tested on my own hardware. Own your compute. 🔧
Joined August 2023
- Tweets87
- Following13
- Followers10
- Likes31




Pinned Tweet
6× NVIDIA CMP 170HX GPUs running at nearly 250W EACH — ~1,500W total, 98–99% GPU utilization, yet staying at just 61–65°C! 🔥
The secret? Custom 3D-printed cooling shrouds I designed for 9733 blower fans.
I now make them for other CMP 170HX owners too!
🛒 Available on my Etsy store — link in bio.
#CMP170HX #3DPrinting #LocalAI
partypailsto.etsy.com/listin…

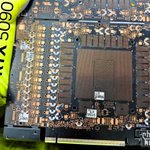
Holy crap, a 96GB RTX 5090 might actually be coming 🔥
Reportedly, card-mod shops in China are already testing it and getting ready for batch shipments. These are the same shops that turned the RTX 4090 into a 48GB card, and now they've set their sights on the 5090.
The rumored recipe: take the GB202 core off a stock 5090 and move it onto a custom dual-slot blower PCB with 96GB of GDDR7. That's triple the 32GB on the normal card, aimed squarely at AI inference and compute servers.
Why local AI people should care: VRAM is the real limit for running big models at home. 96GB on one card could mean 70B-class models at high quality, or huge context windows, without splitting across multiple GPUs. The dual-slot blower design also means you could pack several into a rack.
The caveat: this is still a rumor. No confirmed specs, pricing, or availability yet, and modded cards come with no warranty and uncertain driver behavior. But damn, if it ships, the whole used-GPU market gets shaken up.


DeepSeek has reportedly released an open-source inference framework for its own models.
Why local builders should care: inference speed on your own hardware comes from the software stack as much as the model.
Faster engines mean:
• more tokens per second on the same GPU
• bigger models fitting on cheaper cards
• less reason to pay per token

Heads up for anyone planning a GPU build: memory prices may jump next year.
Reports say Samsung has sold out its 2027 high-bandwidth memory, with HBM prices expected to rise sharply and ordinary DRAM up as well.
Why it matters: the AI boom competes for the same memory your next GPU or RAM kit needs.
If a rig is on your list, price it now. Used cards with plenty of VRAM are where I'd look first.

Nvidia ships consumer cards with tensor math throttled in software. Now people are posting real before and after numbers:
4070 Ti SUPER: 158.5 → 309.1 TFLOP/s (via @CommonFoundry1)
Worth asking: what else is locked on the card you already own?

Models keep disappearing from Hugging Face, and local AI folks are noticing.
If you depend on a model, it can vanish: taken down, gated, or replaced.
What I do:
1. Download the weights you actually use, not just the link
2. Keep the exact quantization and settings that worked for you
3. Store a copy on a separate drive
Cloud APIs can change or disappear overnight. Local only stays local if you keep the files.
Own your compute. Own your weights.

Common Foundry (@CommonFoundry1) reports a ~1.95x tensor speedup on an RTX 4070 Ti SUPER:
158.54 → 309.08 TFLOP/s, FP8→FP32 matched GEMM
Same GPU, same binary, same 240 W cap.
I've seen the same kind of unlock on my own 3080.
xitter.cf/CommonFoundry1/status/…


Common Foundry: We unlocked nearly 2× FP8→FP32 Tensor Core throughput on an RTX 4070 Ti SUPER. A matched GEMM in a custom NVIDIA CUTLASS 4.8.1 harness ran 1.95× faster: 158.54 → 309.08 TFLOP/s. Same GPU, binary and 240 W cap. Results:
github.com/JustAResearcher/g…

Due to major hype on Grok Bot, I tried it for few real world tasks.
For example, Managing my Etsy shop:
I linked the Etsy shop, gave access to my shipping platform so it had shopping data. Sent the 3d files so it knows the product weight.
I asked it to do analysis for my product. And it told me it doesn’t know my shipping cost. It doesn’t know my product weight. It told me to provide these information.
For those who have used a normal coding agents like Claude/codex/deepseek, you know if you have provided access to relevant platform , it will just automatically go pull your data.
Instead Grok Bot just acts it has no previous context.
I guess Grok bot is aimed at normie who doesn’t use agentic workflow. For those who AI heavy users, you’re not missing much. It is just an Openclaw/hermes minus extensive setup/maintenance tax .
It underperforms compare what you can do with Claude/codex

4000 series unlock is here! Get 2x speed increase in tensor core!
Common Foundry: We unlocked nearly 2× FP8→FP32 Tensor Core throughput on an RTX 4070 Ti SUPER. A matched GEMM in a custom NVIDIA CUTLASS 4.8.1 harness ran 1.95× faster: 158.54 → 309.08 TFLOP/s. Same GPU, binary and 240 W cap. Results:
github.com/JustAResearcher/g…
Do not trust any kimi ai review you see because they could be paid shill posts

Post 2 exposing Kimi AI
That's the creators campaign docs I got from Kimi AI after their Kimi K3.1 pro release and thats the narrative they want creators to push, of course I'm out and I'm never gonna say something I don't test myself and give my honest opinion about and I don't want to be involved in this China vs US political situation.

Be aware of fake/paid posts promoting these tools. We really need independent benchmarks.
That's how Kimi AI are promoting their new model Kimi K3.1 pro and I know all the influencers working with them and none of them are honest,I have posted about it myself but I didn't join this and never used their templates that they provide.
PROPAGANDA, I have more to share it's f**cked up I'm gonna have follow up for this

Holy shit! Fully local duplex speech model that can runs on your Mac!
@jack’s Block just dropped the most authentic full-duplex speech model ever built called Dessa. It was trained from scratch on pure human conversation. No text. No pretrained models.
It listens and talks at the same time, interrupts naturally, laughs, catches sarcasm, and runs locally on a MacBook Pro M4 Max.

This is what AI voice should sound like.
Natural, imperfect, human-like speech instead of the polished and refined announcer voice .

Holy shit! Fully local duplex speech model that can runs on your Mac!
@jack’s Block just dropped the most authentic full-duplex speech model ever built called Dessa. It was trained from scratch on pure human conversation. No text. No pretrained models.
It listens and talks at the same time, interrupts naturally, laughs, catches sarcasm, and runs locally on a MacBook Pro M4 Max.
The CMP 100-210 is a mining card on the same GV100 silicon as a Tesla V100.
Used V100 16GB cards now go for ~$300–500. CMPs are usually cheaper, but the real difference is the firmware locks.
Stock CMP:
• PCIe Gen1 x1
• Tensor + FP64 throttled to ~1/16 speed
Unlocks (experimental) have shown ~14–15× gains in those areas on real hardware, getting surprisingly close to proper V100 numbers.
Caveats still apply: not every card unlocks the same, risk of bricking, and some stay limited on SM count or PCIe width. A real V100 is the safer, more supported option if the prices are close.
💸 $10,000,000 on AI tokens in one month.
That’s what the OpenClaw creator reportedly spent in September alone.
Enough to pay an entire office of workers for a month… just burned on API calls.
This is why a lot of serious builders are moving as much as possible to local models.
Once the workload is heavy enough, the cloud bill stops making sense — especially for coding agents, research, and anything that runs 24/7.
You can still use the frontier models when you need them.
But the daily grind? That’s increasingly running on your own hardware.
Have you hit the point where API costs started feeling painful?

$225 Tesla P40 vs $1,300 RTX 3090 — cheap VRAM is a trap if you ignore the rest of the build ⚠️
The P40 looks unbeatable on paper ($9/GB). Reality is messier.
Here’s the actual breakdown from today’s listings:
💰 Budget tier
🟢 Tesla P40 24GB — $225 shipped
Passive server card. Needs real airflow + power mods. Confirm software support for your stack before buying. Not a drop-in.
🖥️ Used consumer cards
🟡 MSI RTX 3090 Gaming X Trio — $1,240 local / $1,300 shipped
Dead HDMI (DisplayPorts work). Ask for current load tests.
🟡 HP OEM RTX 3090 — $1,300 shipped
Condition details incomplete. Demand proof it works.
🟡 ASUS ROG Strix 3090 OC — $1,250 local / $1,350 shipped
Missing screws (was watercooled). Verify load test results.
🧠 Bigger memory
🔵 AMD Instinct MI210 64GB — $3,900 shipped
Better $/GB than the A6000s, but only if your software actually runs well on ROCm.
🔵 RTX A6000 48GB — $3,500–$4,050 shipped
Higher cost per GB. Used for inference in one listing.
💡 My take
The $225 P40 is interesting for a deliberate budget build. It is not a substitute for a tested 3090. At ~$1,300, the 3090s need different questions answered — one has a disclosed fault, another has incomplete condition info.
Negotiate. Get load tests. Factor in cooling, power, and software fit. $/GB alone is a bad filter.
Owners who’ve run both a P40 and a 3090 for local inference: which model/backend made the upgrade worth it, and how much did cooling + setup actually add to the P40? 👇
