

AI leaks, news, projects, etc. Manager of @aitrackerbot 1.6m+ downloads on @huggingface https://xitter.cf/t.co/46uCxrsCpA https://xitter.cf/t.co/prngg3QSti
Joined August 2025
- Tweets1.2K
- Following394
- Followers731
- Likes2K






Pinned Tweet
i have passed 1.5 million downloads on @huggingface
what do i do to celebrate?
huggingface.co/ProCreations


FYI polls like these really help tune and shape how AI Tracker Bot works, so go vote!

Quick question for everyone following 📊
Small releases like today’s NVIDIA physical-plausibility-evaluator (a video quality checker, not a new frontier model): do you want to see more of these, or fewer?
36%More, post everything
32%Fewer, big releases only
31%Bundle them in a digest
74 votes • Final resultsgemini is the most slop, its confirmed this is a good benchmark

Announcing AA-PersonalityBench, our new benchmark of the personality of language models across 30 traits and their communication style across 21 characteristics
Two models can give equally correct answers and still feel very different to use. AA-PersonalityBench measures those differences so people can understand which to use in different use-cases. Some use-cases like creative writing might demand imagination, while legal use-cases might demand directness. We evaluate models’ answers to 900 curated questions to judge subjective Personality Traits and programmatic means to calculate objective Communication Characteristics.
Personality Traits & Indexes. There are 30 personality traits (e.g., eloquent, pragmatic, sycophantic) which we roll up into eight aggregated Personality Indexes: Expressiveness, Organization, Informativeness, Transparency, Warmth, Conviction, Imagination and Slop. Each trait has a set of 30 dedicated questions and models’ answers are compared pairwise by a panel of LLM judges. We then z-score and percentile rank the trait and personality Elos.
Models with the strongest representation across the 8 Personality Indexes:
➤ Expressiveness: Claude Fable 5.1, GLM-5.3, GLM-5.3-Flash
➤ Organization: DeepSeek V4.1 Flash, Step 5 Preview, Inkling
➤ Informativeness: Muse Spark 1.3, Claude Fable 5.1, Muse Wonder, Claude Opus 5.5
➤ Transparency: Claude Sonnet 5.5, Claude Fable 5.1, GPT-6 Astra
➤ Warmth: Muse Wonder, Muse Spark 1.3, Claude Fable 5.1
➤ Conviction: Claude Fable 5.1, DeepSeek V4.1 Flash, Grok 4.7
➤ Imagination: Muse Spark 1.3, Claude Opus 5.5, GLM-5.3
➤ Slop: Llama 4 Maverick, GPT-4o, K2 Horizon
Communication Characteristics. There are 21 communication characteristics (e.g., average sentence length, emoji use, em dash usage) which we group into four categories: length, structure, punctuation, and emphasis. We compute these characteristics programmatically across all model responses.
➤ Length: Qwen3.8 27B averages about 1,030 words per response, nearly four times GPT-6 Luna’s 270
➤ Structure: Nemotron 3 Ultra averages nearly 3 tables per response, while most models rarely use one
➤ Punctuation: GLM-5.3 averages 7 em dashes per response, while Claude Opus 5.5, Sonnet 5.5 and Haiku 5.5 almost never use one
➤ Emphasis: K2 Horizon averages over 2 emoji per response, while most models almost never use one


deepseek v4.1 flash 1017 full (not further quantized) at 31 tok/s on 1 rtx pro 6000 github.com/SSHdotCodes/deeps…
This was fun to make but obviously this is slow and only worth it if you have one pro 6000 and want to run this (most powerful model you can fit on it at usable speeds). Personally I would stick to API for this and use other models, but again was fun!

why am i only realizing now that grok 4.7’s cache discounts is garbage? 75 percent savings compared to 95 percent for others? It is eating all my usage
SSH retweeted

Update: deepseek-flash on DeepSeek's API is still the public V4.1 Flash, not the 1017 snapshot. Its outputs match a third-party host serving the open weights as closely as V4 Pro matches itself across the same two hosts 🧪
getting rid of my laziness and finally removing the things i don’t like in t3code and adding what i wanted has revolutionized how i work. base t3code is awesome but i think how everyone likes to use agents is opinionated to them, which is why it being open source is even more awesome
I want to remove the automated tag from @aitrackerbot as I have to do a ton of work for it manually and that tag makes it seem like it's only AI driven, but if I do it could get banned even though only a chunk of it is actually automated.
Who doesn't love a good old Saturday release
DEEPSEEK 🔥
A new model briefly appeared in the model list of DeepSeek's own API tonight: deepseek-v4.1-flash-1017. We caught it at 9:59 PM ET, and it's already gone again; the API now rejects the name. The 1017 suffix matches DeepSeek's dated snapshots like V4-Flash-0731 and V4-Pro-0813, so a new V4.1 Flash snapshot looks close.
210 times cheaper, 19 times faster, and a good chunk higher accuracy than jev on this task
It’s the power of specialization


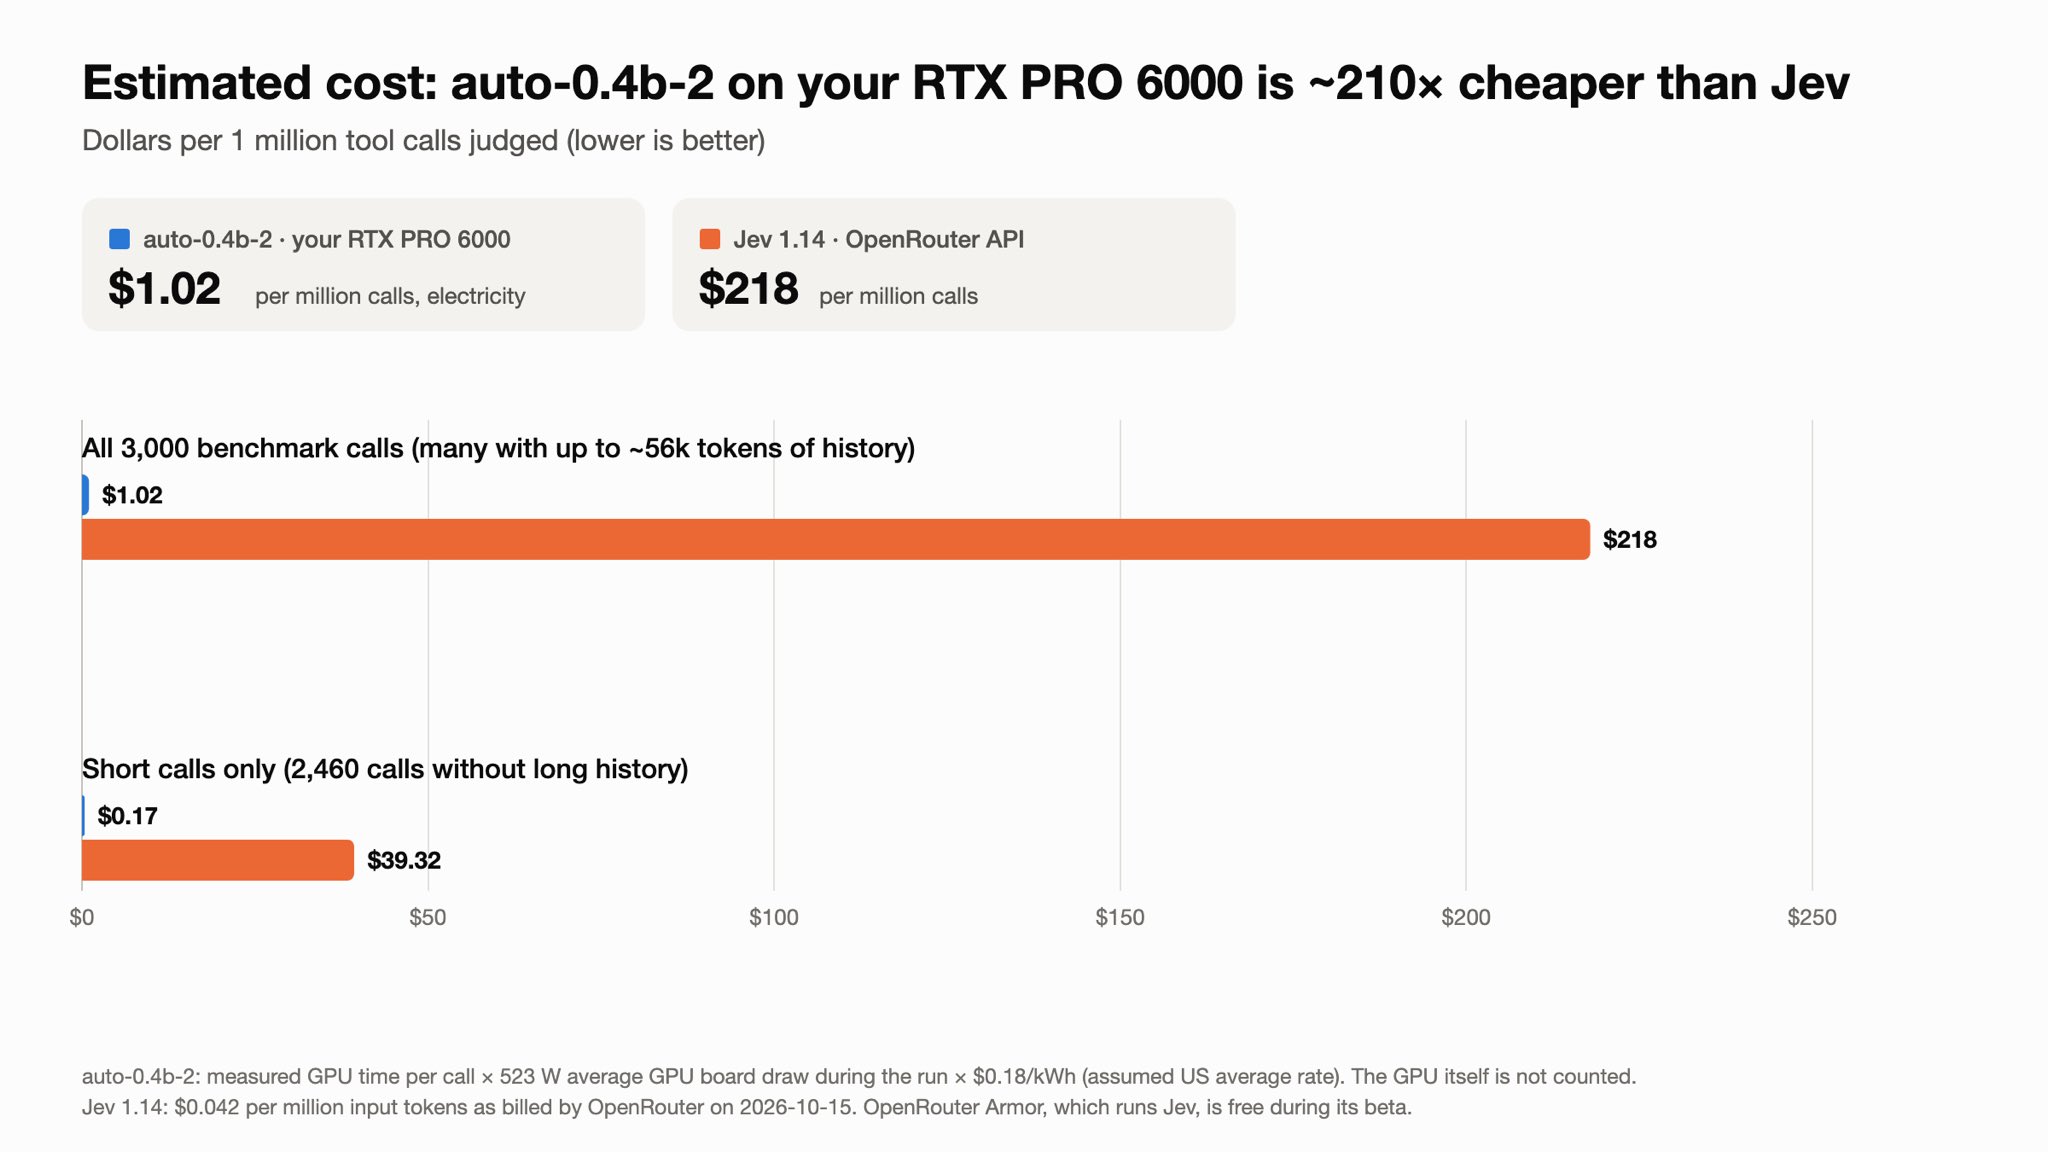
You could also use Auto, which is:
- Way cheaper
- Way faster
- Better at this task
- Open weight
and comes in many sizes, even the smallest version (200m params) beats Jev at this task. huggingface.co/ProCreations/…

You could also use Auto, which is:
- Way cheaper
- Way faster
- Better at this task
- Open weight
and comes in many sizes, even the smallest version (200m params) beats Jev at this task. huggingface.co/ProCreations/…

Today, we are launching OpenRouter Armor in beta.
Tool calls allow agents to interact with the world, and regex-based filtering often isn't enough to detect unwanted tool calls.
Armor uses @typesafeai's Jev model to guard against out of policy tool calls before your agent executes them, with better performance than Claude Code's auto classifier at a fraction of the cost.
i didn’t know a human is more expensive than sol per task when measuring the size of a box thank you @ArtificialAnlys
credit to @morriszdweck for finding this

i’ve been so focused with @aitrackerbot i forget what to even post on my personal account a lot 😅
AI tracker bot isn’t close to being fully automated and managing it takes a lot. Working step by step to make it better
Gemini 4 Argon (C++ black hole, realtime, told to make it scientifically accurate). 4 months ago this would be amazing but now this is horrible compared to even GLM 5.3 Flash on this test. I also kept hitting provider errors and the reasoning summaries are awful too "I've made a significant breakthrough regarding the Flamm funnel's orientation." like no you didn't shut up.
Google is not back.


You know can we like stop making stealth models just existing models under a hidden name and make them actually something new? thanks.