






Sam Martin retweeted

New scalable oversight blog post 🚨🤖
Do you think you are better than Claude at Geoguessr? How about a text-based variant, where you only see a text description of the image?

Research update from the scalable oversight team at Arcadia Alignment!
Debate is a proposed training method for aligning models on tasks we don't have labels for. We want to study this empirically: does it work on today's models? lesswrong.com/posts/hb8pv3zy…

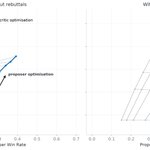
However, the effect size is sufficiently small that we cannot rule out it being noise. It is possible that with more difficult tasks, or more proposer optimization, that critic optimization becomes useful. We leave this for future work.

Going forward we plan to iterate on protocols and settings. In particular we are interested in more fuzzy domains relevant to the alignment relevant tasks we care about.
Work done with @dswg97, @jacob_pfau, @a_aristizabalm and Simon Marshall
Sam Martin retweeted

*NEW* AI alignment research team!
We're announcing the new alignment team @ArcadiaImpact. A London-based team, working closely with @AISecurityInst to tackle 3 ambitious agendas in AI alignment!
👇 🧵
New Anthropic Fellows research: Classifier Context Rot
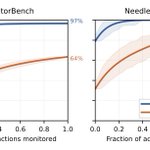
Anthropic monitors for dangerous actions in agent transcripts that are getting very long. Can monitors handle such long transcripts? 🧵

We did preliminary finetuning experiments but were not easily able to elicit improved long context performance in a way that generalized far from the training data.
For these experiments and more, check out our paper arxiv.org/abs/2605.12366 or blogpost lesswrong.com/posts/7vpvNM7v…!

Anthropic fellows research: we use cross-domain generalization to improve LLM monitors.
Language models monitor actions taken by other models to spot dangerous misaligned actions. How do we make them good at this task? 🧵
Benefits of 1-token SFT even generalize to improvements in summarization: a model trained with 1-token SFT identifies dangerous actions taken in transcripts at a higher rate than the starting model!

For these experiments and more, check out our paper arxiv.org/abs/2605.12265 or blogpost lesswrong.com/posts/NxGHQ6DW…!