
I build chips. Opinions are of my own
San Jose, CA
Joined September 2016
- Tweets1.8K
- Following1.5K
- Followers1.7K
- Likes4.3K





Pinned Tweet
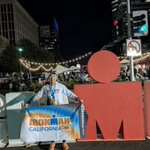
Yesterday I completed Ironman California.
It's 140.6 mile of swim, bike, and run.
It took months of training and preparation. It's all worth it.
🤖 Made with AI


Yes, it's fast 😀

今日Minimax M3.1-Flashの公開と同時にTenstorrent Blackhole Galaxyでの提供も開始しました!
console.tenstorrent.com/dash… から今すぐ使ってもらうことができます。さっき試したら150 token/s/user出ていたので、 openrouter.ai/minimax/minima… でみた限り現時点では世界最速です!!
I love MiniMax. They've really impressed me with their great taste.
@MiniMax_AI 🤝 @tenstorrent — a match made in heaven!

MiniMax M3.1 Flash is now on @tenstorrent Cloud -bringing frontier AI to Tensix silicon, Ethernet scale-out, and an open-source stack from the team led by Jim Keller.
Open weights. Diverse architectures. An open, heterogeneous AI future.🫡
I remember in May, at TT-deploy, we said we are going to run everything.
Now we have day 1 support for open frontier models.
@tenstorrent deliver on the promise! Big day for open source model, open source software and open source hardware!

Today @MiniMax_AI released the open weights for MiniMax M3.1 Flash – available now on Tenstorrent Cloud.
Explore in the playground or connect to your agent harness. Start building → bit.ly/47vU2zc

Congrats @aiand_! This is really cool!

At @aiand_ we made @MiniMax_AI H3 fast and ridiculously cheap by pushing it across @nvidia , @AMD , and @tenstorrent.
H3 fast starts at just $0.0125 per generated second at 768p, with our quality endpoint at $0.055, compared to MiniMax's official $0.08.
Heterogeneous inference lets us choose the right architecture for each workload, then do the engineering to make that choice count. As AI expands across more modalities, we believe this becomes a technical imperative, not just an optimization.
Read about our work below:
Tenstorrent alliance is getting stronger day by day.
Thank you @nedo_info for selecting Tenstorrent and @PreferredNetJP for a five-year project with the Japanese government co-designing AI processors with photonics-electronics integration.
Read more here → bit.ly/4yXhdOQ

We sell good AI hardware and good IPs. Super simple 😃


Fwiw, my reaction initially was: wait, no one has built it before?
Tech people are truly living in a different timeline. I really thought the concept might have been viable since maybe 50 years ago.
I would not underestimate Chinese companies' determination to extreme optimizations and to crush the market even with a loss.
Samsung and SK Hynix are in Asia. Neither is "western memory technology" so it is fair to say CXMT has caught up "Western technology" 🤔

Watching people freak out over CXMT's 4F² and claim that CXMT has caught up with Western memory technology is honestly laughable.
CXMT has hit the limits of DUV scaling. What it is trying to do is move from 6F² to 4F² at the relatively relaxed 13 to 14nm node so it can extend the life of DUV. It is not jumping straight to 4F² to leapfrog Western memory makers that use EUV. People have the cause and effect backwards.
Samsung and SK hynix are also not holding off on 4F² because they are stupid. If they wanted to mass produce 4F² right now, they actually could. The only reason they don't is that the yields aren't there.
I really can't make sense of this selloff sparked by CXMT. 🤡


I think AI solving problems is essentially heuristic based search. Just like human.
But the systems built on human and AI heuristics would be fundamentally different.
I don't think replacing humans is possible nor is it the goal. Automation doesn't mean cheaper nor faster

Feels like a placebo effect.
It's a real problem: simple questions need quick and fast answers. But does the solution really work well or do people just hope it works out well? 🤔


The front end is more labor intensive. That's where I see AI can help great deal.
The backend has traditionally been compute heavy/bottlenecked with all the EDA tools. Converting an already compute bottlenecked flow to a more compute intensive flow probably doesn't work outright

I feel like the reason "AI for chip design" has vast opinions is that the actual benefit all depends on the complexity of the chip and how much sunk time and $ is on the line.
AI can definitely automate simpler, "toy" chips with open source tools quickly, but not complex, market-leading chips with $50M cost.
People often misconflate the benefits that AI has on the former case easily translate to the latter.
AI conferences should pivot to accepting top 300 papers a year, not caring about acceptance rate anymore. With 50K submissions, people are just gaming the systems and wasting resources on non-worthy ideas and everyone becomes anxious about # of papers rather than quality

It's a weird take IMHO.. why not invest more to get alignment? I don't see open source models that are on par or only slightly behind having alignment issues...so far, only closed source ones seem to be "having issues"

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

iPhone's features are falling behind lately, but they still have very good taste and good at selling a story/dream.
Just watched another giant company releasing their new phone, they might have better technology, but it's embarrassing to watch comparing to an Apple event