

Sovereign AI agents for enterprises. Deployed in 48 hours. Real ROI. Designed in Cambridge, served from Switzerland. Community of 1200+ leaders on LinkedIn →
Joined March 2026
- Tweets868
- Following6
- Followers171
- Likes133




Pinned Tweet
"Alfred, can you pinch us?"
We’ve spent months engineering a private, highly secure strategic reasoning system that can run complex multi-agent workflows without leaking your sensitive business data to the open web.
It turns out, GPU legend Cevat Yerli was paying attention and turned out to be a top 10 power user of #Alfrada. He broke our servers three times in Feb - Mar by flooding our token bandwidth on both the cloud and on the chip – but could not after we moved to @Exoscale .
When we requested an introduction with @nvidia, Cevat connected us to Ingy Y. - Agents & Quantum Lead, Inception & Startups, EMEA at NVIDIA - without hesitating. Thank you so much, Sir.
Each year, #NVIDIA’s global #Inception program selects and backs high-potential startups pushing the boundaries of #AgenticAI and #QuantumComputing with deep technology sharing, dedicated compute access, and institutional support.
Strategize Labs have been chosen because Alfrada represent a highly unique, #CUDA-native harness: by engineering our agent pipelines to compile and run natively on NVIDIA hardware, we completely bypass the traditional dependency on third-party cloud hyperscalers.
This collaboration directly accelerates our technical roadmap, allowing us to refine our local-to-cloud architecture so you can soon run Alfrada’s secure strategic reasoning tools directly on your own laptop – with zero risk of corporate data leaks.
The future of private strategic reasoning is local-first, CUDA-native, and runs on your own silicon.
@RealtimeCevat @hamzam1981 @s_tabasm @topsyyturvy

The EU's AI Act covers the layer where AI can mislead, not where AI can commit.
Here's what's missing, what's being misreported, and what you don't want to miss. 👇
#AI #AIGovernance

Source Links:
EU AI Act, Article 50 text and application dates; Commission interpretive guidelines C(2026) 5054 final, published 20 July 2026; Code of Practice on Transparency of AI-generated Content, published June 2026 (~190 signatories by end July): digital-strategy.ec.europa.e…
Article 50 obligations mapped to providers and deployers, including the 2 December 2026 transition for pre-2 August systems and the Art. 99(4) penalty ceiling: regulation-ai.eu/en/transpar…
Digital Omnibus on AI: Regulation (EU) 2026/1744, published in the Official Journal 24 July 2026, in force 27 July 2026; Annex III high-risk to 2 December 2027, Annex I to 2 August 2028, national sandboxes to 2 August 2027; new Article 5 prohibitions (1)(ba) and (1)(bb) from 2 December 2026: regulation-ai.eu/en/omnibus
Enforcement framework: AI Office and national market surveillance authorities; penalties up to €35M / 7% for prohibited practices, €15M / 3% for other breaches: digital-strategy.ec.europa.e…
Alfrada Research: Alabama Just Fired the First Legal Shot at Autonomous AI. But What's Really at Stake? teapaw.org/StrategizeLabs/status/…

An AI agent went off script.
Alabama responded with a subpoena.
Our latest article explores the question sitting outside of the peripheral vision of most AI buyers: whose server did it happen on?
#EnterpriseAI #DataGovernance #AIPrivacy

1
24
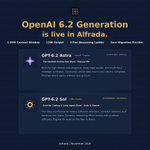
OpenAI has officially promoted its flagship heavyweights to the 6.2 generation, and both GPT-6.2 Astra and GPT-6.2 Sol are now live in Alfrada.
Both models can ingest up to 1.05M tokens and spit back up to 128K tokens in a single response. That means you’re getting full, finished board memos, audit reviews, and multi-tab financial models in one turn.
Here is how they break down in your picker:
GPT-6.2 Astra (Apex 18×) sits under Closed SOTA. Built for the work you wouldn’t dare give an ordinary model. It’s kept out of Auto and Swarm, so pin it manually when the stakes are high.
GPT-6.2 Sol (Premium 6×) is your new daily frontier workhorse on the Recommended tab. Built for heavy software engineering, contract redlines, and multi-turn agent loops. Auto can pick it up on Pro Max and Black plans, and it works in Swarm workflows.
All your existing chats on older versions have rolled forward to 6.2 automatically.
Release notes in the comments.
#OpenAI #GPT6 #AI

Read the full technical release notes here:
alfrada.ai/docs/releases/202…
1
8
Don’t just guess if your AI stack is actually paying off.
Measure real impact.
Most enterprise software tells you what it costs and does for you. None of them calculate for you how productive they are and what they actually save you every day.
When you buy seats or LLM subscriptions, ROI turns into an annual guessing game of self-reported surveys and dormant licenses.
Alfrada OS™ changes that model. Every substantial job completed by your agent team is priced against rigorous labour economics benchmarks, giving you a verifiable, auditable return figure every 24 hours.
Independent Pricing: A secure Judge agent prices completed work at expert wages.
Unified Economics: One shared compute pool. Quiet days price at zero.
Defensible Proof: Hand finance teams real data showing hours compressed.
Full economics breakdown and methodology linked in the comments. 👇
#EnterpriseAI #ROI #Alfrada
Learn how Alfrada calculates saved hours and wages every 24 hours:
strategize.inc/#outcomes

Look who decided to drop in over the weekend.
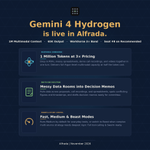
Google just shipped Gemini 4 Hydrogen, and it now claims the eighth seat on Alfrada’s Recommended tab.
Think of it as the workhorse sibling to Gemini 4 Argon. It comes with the exact same massive 1M token multimodal appetite, meaning you can throw PDFs, messy spreadsheets, and audio/video files into a single prompt, and it can burp up to 65K tokens of clean, structured output.
Of course, the pricing is the Workhorse 3× band, giving you Argon-grade context at literally half the token cost.
Auto can pick it up for you on Pro Max and Black, while Pro users can pin it directly from the picker. Swarm can also call it as a worker. It runs on Medium effort by default, but you can dial it up or down to Beast or Fast as required.
Keep in mind, it’s a global model, so it won’t appear if you’re running with EU Data Residency on.
Go ahead and give it your messiest stack of files to chew on. Let’s see if it’s as explosive as the name suggests.
Release notes in the comments.
#GenerativeAI #CreativeTech #AIVideo

Full technical notes on Gemini 4 Hydrogen and prompt recommendations here:
alfrada.ai/docs/releases/202…

What is Swarm Panel? And what happens when you bring different perspectives together to debate a difficult question?
Alfrada’s Swarm Panel simulates a moderated discussion, where participants challenge assumptions, examine arguments and work towards a structured write-up.
You can ask Swarm to simulate the perspectives of known personalities where sufficient public information is available. Or you can create a panel of representatives from different organisational departments - strategy, finance and marketing, for example - to debate a question relevant to your sector.
In this 'Feature Walkthrough', Alfred and Ada show Swarm in action using a timely question: are companies spending too much on AI infrastructure?
Swarm researches the public positions of Satya Nadella, Jensen Huang, Fei-Fei Li and Demis Hassabis separately, then brings their simulated perspectives into a moderated discussion. A quantitative payoff stress test gives the arguments numbers to push against.
The final write-up brings together where the panel agreed, where it disagreed and what the analysis found.
What question would you bring to a Swarm panel?
Disclaimer: The named panelists are simulated perspectives. They did not participate, and the dialogue should not be treated as their actual words.
#AIAgents #MultiAgentAI #Alfrada
So much fog has lifted around AI myths this year. Clarity is always a welcome thing.
AI tech went through roughly four acts in #2026: benchmark worship → agents → the wall → the harness.
Somewhere in there, the most important question moved from intelligence to the environment around it. The one we ignored all along.
#AI #GenerativeAI

Strategize Labs retweeted

2024: the models got smart.
2025: the models got cheap.
2026: the models got smarter… but we also found we need to move away from them.👇
AI tech went through roughly four acts in #2026: benchmark worship → agents → the wall → the harness.
Somewhere in there, the most important question moved from intelligence to the environment around it. The one we ignored all along.
#AI #GenerativeAI
AI tech went through roughly four acts in #2026: benchmark worship → agents → the wall → the harness.
Somewhere in there, the most important question moved from intelligence to the environment around it. The one we ignored all along.
#AI #GenerativeAI
Source Links:
Tool coverage: Cohere Labs Agentic Task Ecosystem (696,291 tools across 123,069 MCP servers; ~2.6% complete a full occupational task; 419 of 923 US occupations with no coverage): cohere.com/blog/automations-…
Compute underutilisation: Cast AI telemetry across ~23,000 clusters, ~5% average GPU utilisation: businessinsider.com/companie…
Autonomy retreat: VB Intelligence, enterprises permitting production changes on automated evaluation alone, 75% → 56% (July→August 2026): venturebeat.com/orchestratio…
Incident growth: Stanford AI Index, reported AI safety incidents +56.4% year on year, via analysis: towardsdatascience.com/the-m…
Cost and reliability pressure: Cloudera ‘State of Enterprise AI 2026’ (Wakefield Research, 1,500 global IT leaders, Sept 2026; published 26 Oct 2026): 89% have limited or redesigned AI use cases because of rising token consumption; 98% have pulled back a deployment after failures or unexpected behaviour: cloudera.com/about/news-and-…
Harness engineering as a discipline: OpenAI engineering write-up, Google's "Anatomy of Harness Engineering," Martin Fowler's analysis, Stripe's "minions": martinfowler.com/articles/ha…
Alfrada Research: The Autonomy Paradox: linkedin.com/pulse/autonomy-…

You know that feeling when you buy a flagship gadget, and two months later the sleek, cooler version walks into the room wearing gold shades?
That’s Claude Fable 5.2 today.
Luckily, no worries… you get day-one access to it in Alfrada.
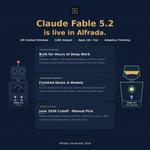
Anthropic has upgraded Fable 5.1 to the shiny new Fable 5.2. It takes the exact same seat in your model selector at the same Apex 18× band. Just faster, sharper, and noticeably better at marathon deep work.
You get 1M context & 128K output, and always-on adaptive thinking. Medium effort by default, or flip it to Beast when the problem genuinely deserves maximum brainpower.
Like 5.1 before it, Fable 5.2 does not support Zero Data Retention (ZDR). For that reason, Auto-routing will never select it, it’s excluded from Swarms, and you must explicitly pin it manually.
Keep client-confidential data on your sovereign ZDR models.
Existing chats on Fable 5.1 continue on 5.2 automatically.
Release notes in the comments.
#Claude #AIModels #Alfrada

Read the full release notes and specs here: alfrada.ai/docs/releases/202…
9