




Pinned Tweet
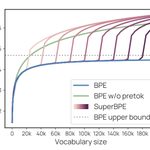
We present Compute Optimal Tokenization! 🔡
Common in LLM scaling works stick to one tokenizer, sweeping data/model size.
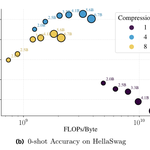
But what happens when we control the tokenizer’s compression rate (bytes/token)?
Here we sweep tokenizers, params, and data across compute budgets: [1/N]
Tomasz Limisiewicz @COLM retweeted

We will present a tutorial on tokenization on Wednesday: xitter.cf/shocheen/status/210241…

Headed to #EMNLP2026? Want to learn about the latest advances in tokenization research in LLMs?
Come check out our tutorial on October 28. We will cover everything from fundamentals and emerging approaches with plenty of hands on demos and exercises.
See you in Budapest!


Tomasz Limisiewicz @COLM retweeted

Today we published a technical report on Muse Glimmer, our 30B open-weight model built for agentic tasks on consumer hardware.
It runs at practical speeds on a Mac or PC with a single consumer GPU at 4-bit precision, and leads comparably-sized open models on tool use and multi-step planning.
Read about the model architecture, distillation recipe, quantization and more: go.meta.me/4Bcvxol

Tomasz Limisiewicz @COLM retweeted

They say you can’t be at two conferences simultaneously. Well, our paper MATT won the Best Poster Award 🏆 at @MLinPL in Warsaw, while I presented it at @tokshopMeeting (@COLM_conf) in San Francisco. Kudos to Piotr Ludynia for showing it to the Polish audience!


A year and plenty of work have passed since the original ICLR submission @vikhyatk posted about. Since then, MATT has been accepted to @NeurIPSConf, and now I'm heading to @COLM_conf to present it at the Tokenization Workshop.
Here's what Model-Aware Tokenizer Transfer does 🧵
Tomasz Limisiewicz @COLM retweeted
Extremely sad to miss this, but if you have a chance, go learn about a topic researchers conveniently tend to forget despite its impact
Headed to #EMNLP2026? Want to learn about the latest advances in tokenization research in LLMs?
Come check out our tutorial on October 28. We will cover everything from fundamentals and emerging approaches with plenty of hands on demos and exercises.
See you in Budapest!
There are bigger workshops out there, but @tokshopMeeting is the friendliest one!


Tomasz Limisiewicz @COLM retweeted

Next up, we have Alexandre Défossez @honualx, cofounder of Kyutai, who is talking about audio-text modeling and related tokenization challenges.

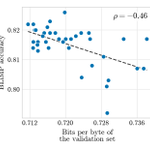
Great research motivation, but I do not buy the reasoning . For a better general understanding of the topic, it's important to explain BPB properties and what we can and cannot make of them. Here's my take on “Tokenizer Myths” myths 🧵 1/13👇


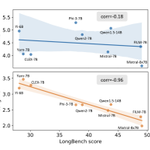
There is a whole line of research showing that intrinsic metrics do not always correlate with downstream tasks. For instance, LongPPL paper (@yifeiwang77) showed that standard perplexity correlates poorly with long context tasks 👀👇. 12/13

# My Bottom line:
BPB is a good early signal of LM performance that allows meaningful comparison across tokenizers.
It is not a perfect predictor, so downstream evaluation is still needed.
We should keep studying biases and adequacy of BPB as a metric. FIN
@RylanSchaeffer