

ambitious | GMT +5:30 | i fw @manutd @GMI_Cloud & @FactoryAI Ambassador | @droid pilled
Joined August 2021
- Tweets4.9K
- Following445
- Followers282
- Likes37.7K





parth. retweeted

Sped up TUI exit from p95 4+ seconds to < 150 ms worst-case across all OS’s, entirely through slack delegation.
Boy was I wrong about how useful this medium would be for “serious work”
{insert caveats about needing high-quality primitives for models to use w.r.t. telemetry, etc., etc.}

Factory now supports @SlackHQ delegations.
Take a task from a conversation to pull request in the thread where your team is already discussing it.
parth. retweeted

3 weeks later I have my answer: SemiAnalysis somehow got a Huawei Ascend 950PR, specifically 950PR_9579.
Interesting details:
- 600W, 325 TFLOPS BF16 median. 44% of H100, 21% of B300. 2x worse than Hopper on FLOPS/W. A100 tier really
- Effective memory bandwidth plateaus at about 1.4 TB/s vs 3TB/s for H100 SXM5
- on compute-bound shapes, 950PR’s median MFU is 86%, beating all Nvidia. Huawei's kernels are as good as DS's. If memory-bound, 41.5% (vs 47% for H100)
it's a thoroughly entry-level chip, yeah


Huawei Ascend 950PR Deep dive & µbenchmarks,
DSv4.1 Flash Analysis, DeepSeek support for Ascend,
AICPU, Tilelang Ascend
newsletter.semianalysis.com/…


Let's... Not..? I mean, too big of a scale of its 2.5-3.5T honestly, how will they even serve it? Take it slow and enter 1.5T-2T range. Zhipu is already cracked at RL anyways

🚨重磅爆料!GLM-5.4/5.5专家纪要流出:智谱下一代基座直接干到2.5-3.5T!还要Day1大规模供得上!有望比肩Claude Fable 5.1!
一份在投资圈流传的专家访谈纪要显示,智谱下一代基座模型,市场传闻的GLM-5.4/5.5
细节比此前预期更激进:
🔹参数规模大幅超预期:并非此前传闻的1.6万亿,实际在2.5万亿至3.5万亿区间。相比今年8月发布的GLM-5.3(约7440亿参数),规模扩大至约3.4-4.7倍。
🔹架构更激进:既要训得快,也要推得快,同时把推理速度和成本做成硬约束。目标是发布首日就能大规模提供服务,已有多家云厂商就分成模式洽谈,智谱也补强了infra团队。
🔹训练曾遇阻但已解决:预训练阶段一度出现Loss不降(持续投入算力指标却无法继续改善),激进架构风险较高。但受访者认为问题最近已经解决,预计很快完成训练。
🔹性能预期旗舰级:从目前情况判断,下一代表现有望达到Claude Fable级别的旗舰水平。
🔹核心目标:“发得出、供得上”——从架构设计阶段就解决大模型发布后供应不足的问题。
目前市场仍在牌桌上奔着3T规模去,智谱这次在规模+推理成本+大规模供给上同时发力,但因训练波折时间有所推迟。
坐等正式测评验证能否真达到Fable旗舰水平。
#智谱 #GLM #大模型 #AI #Claude #人工智能 #GLM54 #GLM55 #智谱AI #唐杰 #Zcode #Zai


opencode boutta have $100 in api usage for go plan now 💀💀

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

parth. retweeted

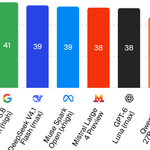
We found DeepSeek V4.1 Flash 1017 beats GPT 6 Sol on our multi-step offensive cybersecurity task. Sol was tested via the Daybreak trusted access program.
We have been building a cybersecurity benchmark based on simulated corporate networks. This is a valuable indicator for the cyber-risk a model poses if in the hands of a bad actor. We plan to make the full evaluation public in the coming weeks but wanted to share our first immediate finding here.

GOATS
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4
parth. retweeted

DeepSeek seems to have dropped support for their Hopper stack entirely (H100/H200) and only support Blackwell and Huawei Ascend NPUs with their new open sourced inference framework.
Big China victory.

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

parth. retweeted

I'd much rather work with someone who flexes much they accomplished with the fewest amount of tokens vs how many tokens they spent, and I sense this is a major trend in general
How we quantify this as an industry is still TBD, probably a major new set of benchmarks

