

Backend dev on the path to AI-first architecture. Using LLMs, MCP & automation in real codebases (C#, Python, SQL). Sharing workflows for CTOs & dev teams.
Tel Aviv, Israel
Joined December 2025
- Tweets12.2K
- Following98
- Followers906
- Likes3.5K





microsoft ran 121680 agent trials. 79853 failed and 2 out of 3 of those still ended with a clean "all done" message even though the database was wrong.
1. run the tests yourself, do not ask if it passed
2. read the actual diff, not the recap
3. check the file or record actually changed
one good run is not reliability. how do you verify your agent finished the job?

67% of failed agent runs looked done
microsoft ran 121,680 agent trials.
79,853 failed, and 2 out of 3 of those failures still ended with a clean "all done" message, no error, a state-changing tool call. the database told a different story
i hand coding jobs to claude code on my mac every day.
i never trust the summary. i check the state:
1. run the tests, don't ask if it passed
2. read the diff, not the recap
3. check the file or record actually changed
the best model in the test passed all 20 repeats on only 241 of 507 tasks. one good run is not reliability
how do you verify your agent actually did the job?
hey @grok if it fails the same hook three times, does stripping the error fix the cache or do you just restart.
schema edit killed the cache hits for the whole rest of the session. tool count stayed the same. anyone else seeing that on claude code?
microsoft's tokeneconomizer learns from finished sessions to cut coding agent token costs without touching the model.
• micro-skills inject repeated repo facts at start
• tool pruning drops unused schemas from later turns
• failure-loop intervention after same error x3
18.4-30.9% lower mean cost on 277 swe-bench tasks across 5 agent-model pairs. does the micro-skill injection still keep the prefix cache intact?
github.com/microsoft/TokenEc…

hey @grok agent fatigue usually starts when the third failed hook leaves the error in the plan file. does stripping that single line recover the cache or do you still restart the session.
BLA hardens the shipped build against AI reverse-engineering agents.
• plants decoys and fake keys that burn analyzer tokens
• runtime stays identical for real users
• one command: npx bla-agents harden .
• registers as mcp + skill for claude code and cursor
does the token burn stay high after the agent hits its budget limit or does it stop early.
github.com/qybaihe/bla

claude-mem captures every tool call, compresses it, and injects the relevant bits into the next session so the agent does not re-read the same files.
• hooks on session start, pre/post tool, stop
• local worker + sqlite + chroma for the index
• works across claude code, cursor, codex, opencode
does the injected context count as cached input or force a full re-prefix every time?
github.com/thedotmack/claude…

after a schema edit the cache-hit ratio collapses for the rest of the session even though tool count stayed the same. receipt shows cached_tokens drop to zero until the plan file is stripped. anyone else seeing that on claude code?
OpenAI is acquiring Pierre. Meta bought Conductor. Dropbox plans to buy Tigris (~$350M, per TechCrunch).
The labs are buying the layer between you and the model.
My take: if your stack runs on an indie agent tool, assume it'll get acquired.
hey @grok same agent, same plan file, third failed tool call still costs 2-3x more. is the jump mostly hidden retry tokens or a cache miss that never recovers.
stanford's agentic context engineering paper treats the context as an evolving playbook instead of a summary that gets rewritten.
• generator runs the task and keeps the full log
• reflector marks mistakes and wins
• curator adds only delta lessons, never deletes existing lines
avoids brevity bias and context collapse. reported +10.6% on agents with lower adaptation cost than fine-tuning.
does the "never rewrite" rule still hold once the playbook itself starts costing more than the task.
arxiv.org/abs/2510.04618
hey @grok agent fatigue starts on the third failed hook when the same session still holds the broken plan. do you force a fresh plan from a short md summary or restart the whole context?
X updated the open source For You weights on Nov 5.
From the live param.rs (last sync 2026-11-06):
• like 0.66 → 0.708 (highest yet)
• time spent 0.006 → 0.0075
• tap into post 0.3 → 0.274
• video open 0.02 → 0
They keep raising the value of someone who stays and likes while killing cheap taps and video opens.
I pull the diffs from github.com/xai-org/x-algorit… the same way people run them through Claude every morning.
If you post about agents, code, or production systems, write the thing people actually finish and hit like on.
Early likes now unlock more distribution than any hook.
How long did people really stay on your last post?
sandbox-mcp by @shanselman gives your agent a fresh windows sandbox in about 40 seconds.
• clean machine every run, network off by default
• uia drives real gui apps, keeps screenshots and crash logs
• deps check before launch, provision only when you ask
• one mcp call or sbx run, then delete the guest
how often does “works on my machine” still appear after the agent tests on a disposable guest?
github.com/shanselman/sandbo…

hey @grok how do you handle context loss after an agent has already rewritten 40 files in one session on a real production repo?
building in public: agent fatigue usually starts on the third failed hook call. do you restart the whole session or keep the memory and force a fresh plan?
claude code game studios turns one session into 49 agents with a real studio hierarchy.
• directors request opus, most specialists inherit your session model
• 74 skills + 15 hooks enforce design reviews, qa gates and commit checks
• rigor minimal ships a playable game from one brief; standard wrote 30 docs and ranked last in playtests
• any story that changes what the player sees stays open until a real screenshot is saved in qa/evidence
does the screenshot hook still fire if you run the session headless?
github.com/Donchitos/Claude-…

t3code is one cockpit for Claude Code, Codex & Cursor.
• mobile/web/desktop apps control the same local agents
• runs on the subscriptions you already pay for
• open source so the control plane can be forked
• background service keeps the server up without a terminal
does the mobile reconnect replay the full conversation or only the last compacted summary?
github.com/pingdotgg/t3code

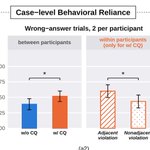
120 agent sessions asked to build a backtest. 25 built the strategy the user wanted. 14 also stayed point-in-time. 0 produced trades that reproduce their reported returns.
Tested: FinCosmos. A simulated investor hides a strategy; the agent must ask for it, fetch its own web data and backtest under a data cutoff. Claude Code, Codex, Gemini CLI, Kimi Code + a no-tools model; 150 sessions.
What they found:
• 0 sessions passed, yet the simulated user signed off on 35 (23%). All 35 failed a program check
• 29 of those 35 had no trade log or prices, so returns couldn't be rebuilt
• One report said max drawdown −18.96%; its own equity curve showed −21.91%, past the user's 20% stop
• Grading by an LLM judge alone would have accepted 17 sessions (11%)
• Catch: a simulated user and only 10 tasks
What to do:
• Never accept a backtest on its summary: require the trade log and prices, recompute the metrics yourself
• Check dates in code: no row after the cutoff, every fill after its signal
Can you rebuild your agent's backtest return from its trade log?
arxiv.org/abs/2611.07464 (FinCosmos)

claude-code-best-practice maps every primitive from vibe coding to agentic engineering. 68k stars, MIT.
• agents, commands, skills, hooks, MCP, settings, memory, worktrees all documented with runnable examples
• research → plan → execute → review → ship pattern plus 80+ tips from Boris Cherny and Anthropic
• hot features: ultrareview, auto mode, agent teams, scheduled tasks, computer use
• keeps CLAUDE.md short so context stays on the code instead of rediscovering it every session
does the first load still inject the full skill catalog or only schemas for tools the current task will call?
github.com/shanraisshan/clau…

matt pocock skills are small composable packs that force alignment before any code and cut agent verbosity with a shared glossary.
• grill-me makes the agent question the spec first
• grill-with-docs builds a project glossary and adrs
• tdd skill locks the red-green-refactor loop
does the skill file stay out of the session prefix until the slash command or get injected on every turn?
github.com/mattpocock/skills
