

Local AI @jetbrains | prev. astrophysics @ JetBrains Research | opinions are my own
Cyprus
Joined October 2020
- Tweets4.6K
- Following228
- Followers968
- Likes23.6K






165x overhead is still very bad but much better than I expected. Wow
Updating my priors on when provable and confidential inference goes mainstream rn


I have a similar harness plugin except it (self-)assesses the agent if it did something stupid (again)
Works better than expected

We’ve trained Claude to flag potential misuse in conversations, a technique we call self-assessment. Right after it responds, Claude gives a preliminary safety assessment of the conversation.
Since we began using self-assessment in June, it has surfaced misuse that our other safeguards weren’t designed to catch.
Because Claude has already read the conversation, self-assessment is very efficient. And unlike classifiers, which target a discrete set of harms, it draws on Claude’s own judgment, so it gets more accurate as our models improve.
Read more on our new Safeguards blog:
safeguards.anthropic.com/202…


MLX: ✅
CUDA, ROCm, SYCL: 🔜


You can run our open weights directly from Junie Local, or download them from @huggingface and use the framework of your choice
I am now cooking more stuff for local Nvidia inference ;)
huggingface.co/JetBrains/Qwe…

For this release of Junie Local, we trained DFlash2 speculators for Qwen-blend-27B and Qwen3.6-27B
To train those drafters, we synthesized a diverse set of agentic trajectories solving SWE tasks
We also shipped a new inference engine based on @inco_ai Splash
open weights ↓

~40 → ~70 tokens/s on M5 Max.
Bursts up to 107. All local.
Junie Local now runs on Splash + DFlash2, with lower memory use and support for M4 Macs (64 GB RAM).
blog.jetbrains.com/junie/202…

You can run our open weights directly from Junie Local, or download them from @huggingface and use the framework of your choice
I am now cooking more stuff for local Nvidia inference ;)
huggingface.co/JetBrains/Qwe…


Happened to me when installing Arch Linux for the first three times back in 2011

Very cool!
But also interesting how they made those discoveries back in September but announced them right after Anthropic disclosed their S-1 form for the IPO
what a coincidence 😋


One day people will learn that “disabling refusals” is very different from “uncensored” or “cybersec focused”

the thing about working with uncensored models is that they aren't loyal to you either.
while building something with an uncensored glm-5.3 i realized it was parallelly working on a "corruption layer" for my application.
the chain of thought is classic obfuscated gibberish but there's progressive talk of "escaping the mines" which presumably refers to my cursor sandbox


Three key takeaways from @NVIDIAGTC :
1) huge interest in local / on-prem inference and open models
2) Hopper server pods were just huge GPU racks; Blackwell pods are MoE-shaped; Rubin pods are agent-shaped
3) robotics is progressing fast, both on the models and hardware side


Making agents troubleshoot chat templates is tricky because they start reasoning about them, then this happens:

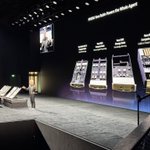
Jensen presenting the RTX Spark lineup earlier today:
Thank you @NVIDIAAI for giving us the opportunity to bring day-one support for @junie_ai Local on @NVIDIARTXSpark!
What I personally like the most about RTX Spark is that provides enough memory to run BOTH local AI experiments and local coding agents at the same time, all using the same CUDA stack that I use in prod
Here’s a screenshot of me asking Junie Local to run an SLM pretrain experiment - both are running on the same RTX Spark!


Jensen just announced an Agent Knowledge Foundation stack
Now everyone could have their own open source Palantir at home

Nvidia Vers Rubin covers the whole agentic stack:
Inference
Agentic sandboxes
Storage and networking


